
KINTOテクノロジーズ の技術ブログ
全1132件
はじめに グローバル開発グループのWuです。普段Web/Portalのプロジェクトマネージメントの仕事をしています。 最近ボクシングジムにまた通い始めました。筋トレとダイエットを頑張っていきたいです! 私たち開発しているWebサイトにMicrosoftのClarityというヒートマップツールを導入したので、そちらについてお話します。 導入背景 モビリティサービスKINTOのグローバル展開を紹介する Global KINTO Web では、ユーザーのページ滞在時間が短かったり、直帰率が高いなどの課題を抱えています。Googleアナリティクスのイベントでスクロール率やクリック率を数値でチェックしていますが、ユーザーの行動、ユーザーの興味関心はどこにあるのかはGoogleアナリティクスだけではわかりません。 そこで、ユーザーの行動をチェックし、簡単に課題を発見できるような分析ツールを導入することになりました。 Microsoft Clarityを選んだ理由 前述の通り、Global KINTO Webは現時点では比較的小規模なWebサイトで、また、サービスサイトではありません。その費用対効果を考えると、できるだけ安価でかつ簡単に導入できるヒートマップツールである必要がありました。 人気ツールUser Heat, ミエルカヒートマップ、mouseflow、User Insightなどのツールを検討しましたが、その中でもClarityを選定した理由は複数あります。 まず、KINTOテクノロジーズがすでに導入しているMicrosoftが提供していること、そして完全に無料であること、また、チームメンバーに権限を付与してチームで運用することもできること。また、セットアップも簡単で、導入までエンジニアの工数がほぼかからないのも魅力でした。 人気ツールの比較表 ツール 機能 導入方法 プライス Microsoft Clarity ・インスタントヒートマップ:ユーザーがどこクリックしたか、どのぐらいスクロールしたか ・セッションのレコーディング可能(←かなり使える) ・レコーディング ・Google Analytics連携 Clarityがが提供しているHTMLタグをウェブサイトに埋め込む 無料 User Heat ・マウスフローヒートマップ ・スクロールヒートマップ ・クリックヒートマップ ・アテンションヒートマップ User Heatがが提供しているHTMLタグをウェブサイトに埋め込む 無料 ミエルカヒートマップ ・3つのヒートマップ機能 ・広告分析機能 ・イベントセグメント機能 ・ABテスト機能 ・IP除外機能 ・カスタマーエクスペリエンス改善チャート ・フリープラン:3,000PV/月 ・有料プランはABテストなど使えるのでオプション性 mouseflow ・基本は上記の機能があるが、ファネルの設定、コンバージョンユーザーの分析など充実 ・レコーディング機能 ・フォームの分析機能(入力時間、送信数、離脱数など細かいみれる) mouseflowのトラッキングコードをエントランスウェブに埋め込む Starterプラン(11,000/月)〜エンタープライズプラン Microsoft Clarityとは? 2020年10月29日リリースされた、Microsoftが提供する無料のヒートマップツールです。公式サイトより下記のとおり紹介されています。 セッション再生やヒートマップなどの機能を使用して、ユーザーの Web サイトとの対話方法を解釈できるようになるユーザー行動分析ツールです。 Microsoft Clarity セットアップ Clarityで新しいProjectを作成します Clarityのトラッキングコードをページ内のheaderの要素に貼り付けます Googleアナリティクスを連携します Dashboard Dash boardはデッドクリック(Dead click)、クイックバック(Quick Back)、イライラしたクリック(Rage clicks)、過剰なスクロール(Excessive scrolling)などの分析といったようにサイトの状況がわかりやすく独自の項目がダッシュボード化されています。 デッドクリック(Dead click) ユーザーがページ内のどこかをクリックまたはタップしたけれど、応答が検出されなかったという意味です。 Dead Clicks ユーザーがどこをクリックしたのかがわかります。また、動画でユーザーの動きを記録しているのでわかりやすいです。 Global KINTO Web の場合、各サービスを紹介するパネルがよくクリックされ、ユーザーがより詳細な情報を求めていることが推測できます。 クイックバック(Quick Back) ユーザーがページを表示した後、前のページに素早く戻ったという意味です。ユーザーがWebにアクセスした際、ターゲットではないページと判断したらすぐに前のページに戻ってしまう、または誤ってクリックしてアクセスしてしまったケースもあります。どの部分が利便性の低いナビゲーションになっているか、また、誤ってクリックされやすいかがわかります。 Quick Back イライラしたクリック(Rage clicks) ユーザーが同じ領域を何度もクリックまたはタップしたという意味です。 Rage Clicks Global KINTO Webの場合、通信速度が遅いなどの原因でリンク集をひたすらクリックしているユーザーが複数人がいました。確認すると、同じOSのユーザーにこの事象が発生していることがわかったので、端末検証に繋がりました。 過剰なスクロール(Excessive scrolling) ユーザーが想定以上にページをスクロールしたという意味です。ユーザーがページ内のコンテンツをしっかり読んでいない割合がわかる指標です。 Excessive scrolling ヒートマップ クリックヒートマップ(Click Heatmap) ユーザーがページ内のどこを何回クリックしたかがわかります。左側のメニューにクリックされている箇所が多い順でランキングしています。 Click maps スクロールヒートマップ(Scroll Heatmap) ユーザーがページをどこまで見てるかがわかります。赤い部分は最も読まれている箇所から、色がオレンジ、緑、青に見られてる割合の少ない順に変わります。 Scroll maps 領域ヒートマップ(Click Area Heatmap) 領域ヒートマップはクリックヒートマップとほぼ同じ機能していますが、広いエリアでクリックされている箇所が確認することができます。ページ内に配置されているコンテンツが読まれてるかはわかります。 Area maps レコーディング ユーザーのリアルな行動が記録されます。マウスのカーソルの位置、ページのスクロール、ページの遷移、クリックの動きを動画から確認できます。 また、端末の情報、地域、クリック数と観覧したページ数、終了のページ情報も左側メニューから確認できます。 ユーザーの一連の行動履歴を動画でリアルに見れるのはClarityの一番の魅力かもしれません。 Recordings overview 最後に Global KINTO Web はまだまだ発展途上で、改善の余地があるWebサイトです。今回、ヒートマップの導入を決めてから、Clarityのクオリティとその導入の簡単さから、約半月(0.5人月)でリリースすることができました。現時点でフル活用できているわけではないですが、今後はこのツールをベースに、よりよいユーザー体験を提供すべく動いていきたいと思います。

A sequel article has been posted 🥳🎉 (June 8, 2023): [Sequel! Dev Container] Creating a cloud development environment with GitHub Codespaces . Introduction Hello. Torii here, from the team[^1][^2] Common Services Development Group that develops payment platforms used by multiple services. Finding your IDE doesn't work even though you created it according to the procedure manual; having to check how different-version SDKs work and install them separately for each product; and so on... I suspect a lot of people reading this article have experienced woes like these when creating a local development environment. Creating a local development environment is one of the more tedious tasks that can befall new product development members. In this article, I want to share an example of how Visual Studio Code (from here on, VS Code)'s Dev Container was used to create a development environment, simplify it, and make it the standard one. What is VS Code's Dev Container? A Dev Container environment is a development environment created using the VS Code Dev Containers extension. You can use it if both VS Code and Docker are available. (Windows / Mac / Linux.) As the following figure shows, launching Dev Container lets you use a Docker container as a full-featured development environment from within VS Code. Mount the source code from the host machine, and the VS Code extension will get installed inside the container. That means there's no need to consider conflicts with the libraries that are already installed. For example, when developing on the host machine, if the specified version of node.js for another project is different, you might need to manage the version of node.js with n package and — depending on the situation — possibly switch versions. Cited from Developing inside a Container The details for the Dev Container environment (the VS Code settings, extensions, libraries to install, services to start, etc.) can be defined in devcontainer.json , Dockerfile , and docker-compose.yml . The Dev Container environment will be built automatically using these settings, making things vastly simpler than installing everything separately. The environment creation procedure document also only goes up to building the Dev Container. There's also no need to consider OS differences when multiple people are doing the development work. Procedure for creating a Dev Container environment In this example, we want to create a new React app using Create React App . Environment used PC: Surface Laptop 4 Windows 10: 21H2 (WSL2) WSL2: Ubuntu 20.04 VS Code: 1.73.0 Prerequisites VS Code is installed. Docker is installed (on WSL2 if using Windows). Docker Desktop for Windows/Mac is installed. 1. Install the Dev Containers extension First, open VS Code in the directory you want to use as the workspace. Next, install the Dev Containers VS Code extension. Remote Development (which includes Dev Containers ) is also okay. 2. Start setup with Reopen in Container Click the icon at the bottom left and select Reopen in Container from the menu at the top of the screen. (Create Dev Container will create the Dev Container in another directory.) 3. Select the settings for the Dev Container environment you want to create In this example, we chose Ubuntu. 4. Select the version of the Docker container image 5. Select the features you want to add In this example, we chose Node.js (via NVM) and yarn , which are required to create a React app. Select the features you want to add and click 🆗 to start building the Dev Container. 6. Dev Container build complete When the build is complete, the VS Code connected to the Dev Container will launch automatically. You'll see that a file .devcontainer/devcontainer.json has been created, and Dev Container is shown in the bottom left. (Previously, .devcontainer/Dockerfile also used to be created.) Open the terminal in VS Code ( ctrl + shift + @ ) and run the following command, and you'll see that the required libraries have been installed. console $ node -v v18.12.1 $ yarn -v 1.22.19 Next, run Create React App . console $ npx create-react-app typesript A prompt will appear, showing that you can go ahead and create it as is. (Creating the React app and confirming that it launches aren't the main topic, so I'll skip them.) How do you like that? If you've ever manually installed node.js , yarn , and create-react-app , I think you'll see how much simpler this way is. Next, let’s build the Dev Container environment that we created in this example. Building an existing Dev Container environment Prerequisites The prerequisites are the same as for creating the environment. VS Code is installed. Docker is installed (on WSL2 if using Windows). Docker Desktop for Windows/Mac is installed. 1. Open the Dev Container workspace on the host machine First, open the workspace you created earlier in VS Code on the host machine. Note: If the Dev Containers extension isn't installed If the Dev Containers extension isn't installed, please install it in the recommended way shown in the following figure. 2. Select Reopen in Container If the Dev Containers extension is already installed, a configuration file for the Dev Container like in the following figure will exist, so you'll be asked if you want to reopen in the Dev Container. Select Reopen in Container , and building the Dev Container will start. 2. Environment creation complete! With that, you're all done building the pre-created Dev Container environment. From now on, you can also launch it by selecting Reopen in Container in the same manner. In Windows, you can also open it directly from the taskbar's VS Code context menu, as shown below. A command like the one below is necessary when completing creation for launching the React app, but we'll discuss the setup for it later. console // node.js package installation $ yarn install You can create the pre-created environment this way in very few steps. Sample devcontainer.json Next, I'll show you an example of my own Dev Container setup. The VS Code settings and extensions define a linter, formatter, and so on. There are also settings for other development support functions, so please do check it out if you're interested. json { // Set the Dev Container's name "name": "test-devcontainer", // Specify the container launch options // --name Specify the name of the Docker container to build // If this isn't specified, generate it randomly "runArgs": ["--name=test-devcontainer"], // Docker container image "image": "mcr.microsoft.com/devcontainers/base:jammy", // VS Code settings "settings": { "stylelint.validate": ["css", "scss"], "scss.validate": false, "css.validate": false, "editor.formatOnSave": true, "editor.defaultFormatter": "esbenp.prettier-vscode", "editor.codeActionsOnSave": { "source.fixAll.eslint": true, "source.fixAll.stylelint": true }, // sticky scroll settings "editor.stickyScroll.enabled": true, "editor.stickyScroll.maxLineCount": 5, "workbench.colorCustomizations": { "editorStickyScroll.background": "#00708D", "editorStickyScrollHover.background": "#59A2B5" }, // Settings to import with absolute path in typescript "typescript.preferences.importModuleSpecifier": "non-relative" }, // VS Code extensions to add "extensions": [ "ms-vscode.live-server", "dbaeumer.vscode-eslint", "stylelint.vscode-stylelint", "Syler.sass-indented", "esbenp.prettier-vscode", "ms-python.python", "streetsidesoftware.code-spell-checker", "naumovs.color-highlight", "burkeholland.simple-react-snippets", "formulahendry.auto-rename-tag", "MariusAlchimavicius.json-to-ts", "dsznajder.es7-react-js-snippets", "styled-components.vscode-styled-components", "Gruntfuggly.todo-tree", "42Crunch.vscode-openapi", "mhutchie.git-graph" ], // Settings (recommended) for users running it in the container "remoteUser": "vscode", // Libraries to install "features": { "ghcr.io/devcontainers/features/node:1": { "version": "lts" }, "ghcr.io/devcontainers/features/python:1": { "version": "3.9" } }, // Commands to run when the Dev Container is created "postCreateCommand": "sh .devcontainer/post-create.sh" } If you didn't run yarn install separately in the pre-created environment above, you can get it done automatically when the environment is created, by defining it with the postCreateCommand option. Personally, I create a separate script and run the sequence of commands required after the container has been created. .devcontainer/post-create.sh # Adding supplementary git bash commands echo 'source /usr/share/bash-completion/completions/git' >> ~/.bashrc # Settings to pass through the yarn global path echo 'export PATH="$HOME/.yarn/bin:$PATH"' >> ~/.bashrc # Installing openapi-generator-cli yarn global add @openapitools/openapi-generator-cli yarn install ``` ## Perceived pros and cons of adopting it The following are what I felt to be pros and cons when doing development in the Dev Container environment. ### Pros - It's easy to simplify the environment creation procedure. - You don't have to worry about the host machine's OS when working with multiple developers. - You don't' need to follow a different procedure for each library and package. - For backend work, it makes heavy use of MySQL and Redis, so it offers even more power. - Environment creation can be declaratively defined and standardized, so it won't vary from person to person. - You can also define VS Code settings and extensions. - You won't run into unexpected bugs due to version differences. - It won't contaminate the local environment, or conflict with other workspaces. ### Cons - It can't meet the needs of people who want to use a different IDE from VS Code. - You can't use your preferred terminal. - It requires fairly high system specs. - It's tricky to use while sharing your screen with Zoom. - Using WSL2 with Windows is rather heavy. - The Mac version has issues with file I/O. - These can apparently be resolved by setting up a named volume for `devcontainer.json`[^3]. ## Conclusion What did you think? I hope you got an idea of how handy Dev Container is. I remember having to pick through a long procedure document to create environments in the past, so I think it’s gotten much easier now. Also, I really got a sense of how useful Dev Container is when we actually invited members from other product development teams to join us as guests for some mob programming, and they were able to get it up and running immediately. For my next trial-and-error experiments, I want to try the following: - Tuning Dev Container's performance, referring to the official article. - Putting Docker on Amazon EC2, and using Dev Container via [ Remote Development using SSH](https://code.visualstudio.com/docs/remote/ssh). - Doing development using IntelliJ IDEA's [Remote Development](https://pleiades.io/help/idea/remote-development-starting-page.html#start_from_IDE). - Creating environments on [GitHub Codespaces ](https://github.co.jp/features/codespaces). [^1]: Other Payment Platform Initiatives Part 1. [[About how we incorporated Domain-Driven Design (DDD) into payment platforms, with a view toward global expansion as well](https://blog.kinto-technologies.com/posts/2022_08_30_start_ddd/).] [^2]: Other Payment Platform Initiatives Part 2. [[About how a team of people who'd all been with the company for less than a year successfully developed a new system through remote mob programming](https://blog.kinto-technologies.com/posts/2022-12-06-RemoteMobProgramming/).] [^3]: [ Official article: Improve container performance](https://code.visualstudio.com/remote/advancedcontainers/improve-performance).
Hello, p2sk from the KINTO Technologies DBRE team here. In the DBRE (Database Reliability Engineering) team, we work cross-functionally to solve challenges such as solving database-related issues and creating agile platforms that foster well-balanced governance within the organization. DBRE is a relatively new concept, so very few companies have a dedicated organization to address. Even among those, that do often focus on different aspects of it and take different approaches from one another. This makes DBRE an exceptionally captivating field that continues to evolve and develop. For some great examples of KINTO Technologies’ DBRE activities, check out (@_awache) 's AWS Summit presentation from this year and Tech Blog article about working toward making the DBRE guardrail concept a reality . In this article, I’m going delve into our database problem solving case files and share the details of our investigation into an intriguing issue. We encountered a peculiar situation where Aurora MySQL returned an "Empty set" in response to a SELECT query, despite the presence of corresponding records. The issue We had an inquiry from a product developer about some strange behavior they were experiencing when certain queries were sent from the jump server to the database. The database they were using was Aurora MySQL 2.07.2 (MySQL 5.7.12), and their MySQL client version was 5.7.38 for Linux (x86_64). Below, you can find an image they shared with us at that time, illustrating the observed behavior. As the image shows, even for a table with some records in it, running the query select * from t1; to retrieve all the records produces the response Empty set . In addition, running another query immediately after that results in ERROR 2013 (HY000): Lost connection to MySQL server during query . Then, that’s followed by ERROR 2006 (HY000): MySQL server has gone away No connection. Trying to reconnect... From then on, the system will be stuck in a loop of Empty set , ERROR 2013 , and ERROR 2006 , as the image below shows. Meanwhile, the query select * from t1 limit 1; returns 1 record as expected. At this point, we had no idea what could be causing the issue, or how we could reproduce it in a different environment. Fortunately, the anomalous behavior was observed in multiple tables, providing us with an opportunity to investigate its reproducibility and explore potential resolutions under various conditions. Investigating the issue Reproducibility Despite the fact that the data (including all records and columns) to be retrieved was identical to the query that triggered the issue, all subsequent queries returned results without any problems: select c1, c2 from t1; -- Specify all columns. SELECT * FROM t1; -- Run the query with the reserved words all capitalized. Select * from t1; -- Run the query with only the first letter capitalized. We also confirmed the following: The problem can be replicated when using the writer instance but not when using the reader one. Even when using the writer instance, the issue is reproduced for certain tables within the same database, but not others. It will not be reproduced if the MySQL client is changed to a client belonging to the 8.0 family There appear to be no particular peculiarities or abnormalities related to the columns in the tables or the data itself. Resolvability Next, we investigated whether changing the data or metadata could resolve the issue. Our findings were as follows: Running “analyze table” on tables that reproduced the issue didn’t resolve it. If we created a new table and imported the same data into it from a dump file, the issue was resolved. Doing the following resolved the issue: create dump files of the tables that reproduce it, then create new tables with the same names using DROP & CREATE, and import the data into them from the dump files. The issue was resolved if we deleted all the records from the tables that reproduced it, then imported the same data into them from a dump file. Isolating the causes in light of Aurora’s architecture In our investigations thus far, the fact that recreating the tables resolved the issue suggested there was a problem with the data, while the fact that switching to an 8.0-family MySQL client resolved it suggested that there wasn’t. So, we checked Aurora’s architecture once again. This official AWS document showed us the following: Aurora’s compute and storage layers are completely separate. The writer and reader instances both reference the same cluster volume. The image cited below shows this in a very easy-to-understand way. — Source: Overview of Amazon Aurora’s architecture In light of this architecture, we created an Aurora clone and used it to check reproducibility, so as to identify whether the issue was related to the compute layer or the storage one. Even when you create a clone, the data doesn’t get copied. Instead, the clone continues to reference the same storage data as the original. As shown in the figure below, new data is only created when data is updated in one of the clusters, but there won’t be any changes in the storage layer unless an update is made. — Source: How Aurora clones are created Connecting to the newly created clone and running the query reproduced the issue, so we concluded that the storage layer probably wasn’t involved. This conclusion was also supported by fact that the issue could be reproduced with the writer instance but not the reader one. Based on this, we inferred that the issue had something to do with Aurora’s compute layer. Thinking it might be related to some kind of data held by the compute layer, we checked the architectural diagrams again. This led us to suspect that the cache management system might be involved. Running the following query to see what the current settings were, we found that the query cache was enabled. select @@session.query_cache_type; Next, we checked to see if the issue was reproduced with the query cache disabled at the session level, as shown below. set session query\_cache\_type = 1; -- Query cache ON. select @@session.query\_cache\_type; -- Check. SELECT * FROM t1; -- Wasn’t reproduced. select * from t1; -- Was reproduced. set session query\_cache\_type = 0; -- Query cache OFF. select @@session.query\_cache\_type; -- Check. SELECT * FROM t1; -- Wasn’t reproduced. select * from t1; -- Wasn’t reproduced (!) This confirmed that disabling the query cache stopped the issue. The query cache has been removed in MySQL 8.0, so this also clears up why the issue wasn’t reproduced with an 8.0-family client. Also, running RESET on the query cache stopped the issue from occurring even when the latter was enabled. Incidentally, if FLUSH QUERY CACHE was run, the issue continued. This suggested that the cache needed to be deleted with RESET. set session query_cache_type = 1; -- Query cache ON. select @@session.query_cache_type; -- Check. RESET QUERY CACHE; -- Reset the query cache. SELECT * FROM t1; -- Wasn’t reproduced. select * from t1; -- Wasn’t reproduced. These results showed that the issue was related to the query cache. Investigating similar examples Having thus narrowed down the cause, we investigated whether any similar cases had been reported, and came across this bug report. As its title suggests, it says that errors occur if 2 versions of the MySQL client try to access each other’s caches. We tried to reproduce the issue based on this report, and succeeded with versions 5.6.35 and 5.7.38. If you’re interested in trying it yourself, the procedure is outlined in the appendix. (Version 5.7.41 is used in the appendix, but the issue will still be reproduced.) We asked the inquirers about whether different versions of the MySQL client might have been used, they told us that the issue had started when they’d created a new jump server. We didn’t know which MySQL client they’d used with their previous jump server so we couldn’t be sure, but the inquirers’ issue matched what was in the bug report. So, we concluded that the issue was very likely happening because select * from t1 queries were being executed and cached by different MySQL clients, leading to an error. Considering countermeasures The easiest way to resolve the issue if it occurs is to run RESET QUERY CACHE , but we also looked into ways to prevent it in the first place. We tried updating Aurora MySQL from version 2.07.2 to a newer one to see if that would resolve it. The issue continued with the latest patch version of the 2.07.x release, version 2.07.9. However, when we also updated to a minor version and tried some 2.11.x ones, the issue stopped with both version 2.11.1 and version 2.11.2. This minor-version update may have included some kind of fix for the query cache. So, it looks like updating Aurora to a 2.11.x version might be a good way to prevent the issue. Summary In this article, I’ve illustrated our DBRE activities with an example from our database problem solving case files in which we investigated a strange issue where Aurora MySQL returned “Empty set” in response to SELECT even though corresponding records existed. The cause was a bug in MySQL that meant that erroneous results were given when different MySQL client versions sent the same query to Aurora MySQL 2.07.x with the query cache enabled. The easiest way to resolve it is to run RESET QUERY CACHE (although you do need to bear in mind that the performance will temporarily drop). We didn’t observe the issue with Aurora 2.11.x, so the best option might be to upgrade Aurora to a newer version. Alternatively, with support for Aurora version 2.x due to end on October 31, 2024, upgrading to Aurora version 3 early might also be a good idea. It’s a pretty rare case in the first place so it might not warrant much attention anyway, but all the same, I do hope this article proves to be a useful reference for some readers. We couldn’t have done the investigation without lots of help from lots of people, so thank you everyone! KINTO テクノロジーズ DBRE チームでは一緒に働いてくれる仲間を絶賛募集中です!カジュアルな面談も歓迎ですので、 少しでも興味を持っていただけた方はお気軽に Twitter DM 等でご連絡ください。併せて、 弊社の採用 Twitter もよろしければフォローお願いします! Appendix: Reproduction procedure We’ve confirmed that the reproduction procedure will work on a jump server whose OS is Amazon Linux 2. It also assumes that a 2.07.x version of Aurora MySQL is used. (We haven’t confirmed whether the issue is reproduced with all patch versions, but have at least confirmed that it is with the latest one, 2.07.9.) First, connect to the jump server and install the MySQL 5.6 client (5.6.35). sudo mkdir -pvm 2755 /usr/local/mysql-clients-56; sudo curl -LO https://dev.mysql.com/get/Downloads/MySQL-5.6/mysql-5.6.35-linux-glibc2.5-x86_64.tar.gz; sudo tar -zxvf mysql-5.6.35-linux-glibc2.5-x86_64.tar.gz -C /usr/local/mysql-clients-56/; cd /usr/local/mysql-clients-56/; sudo mv -v mysql-5.6.35-linux-glibc2.5-x86_64 mysql56; sudo ln -s /usr/local/mysql-clients-56/mysql56/bin/mysql /usr/local/bin/mysql56 Next, install the MySQL 5.7 client (5.7.41). sudo mkdir -pvm 2755 /usr/local/mysql-clients-57; sudo curl -LO https://dev.mysql.com/get/Downloads/MySQL-5.7/mysql-5.7.41-linux-glibc2.12-x86_64.tar.gz; sudo tar -zxvf mysql-5.7.41-linux-glibc2.12-x86_64.tar.gz -C /usr/local/mysql-clients-57/; cd /usr/local/mysql-clients-57/; sudo mv -v mysql-5.7.41-linux-glibc2.12-x86_64 mysql57; sudo ln -s /usr/local/mysql-clients-57/mysql57/bin/mysql /usr/local/bin/mysql57 Connect to the database with MySQL56. mysql56 -h xxx -u xxx -p Create a sample database and a sample table, and INSERT the data. create database d1; use d1; create table t1 (c1 int, c2 int); insert into t1 (c1, c2) values (1, 1); insert into t1 (c1, c2) values (2, 2); insert into t1 (c1, c2) values (3, 3); Enable the query cache at the session level, and set it so that queries will be issued and cached. set session query_cache_type = 1; select * from t1; Next, connect to the same jump server from a different window, then connect to the database with MySQL57. mysql57 -h xxx -u xxx -p Enable the query cache at the session level. use d1; set session query_cache_type = 1; If you run a query that differs from the one from MySQL56 by 1 character, it returns the data successfully. Select * from t1; If you run the same query as the one from MySQL56, it returns Empty set . select * from t1; This procedure enabled us to reproduce the issue. To resolve it, reset the query cache. RESET QUERY CACHE;
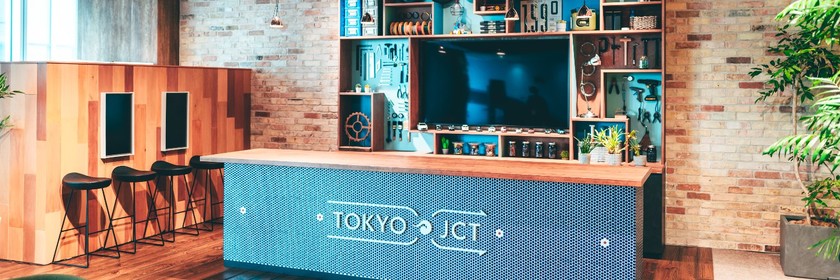
はじめに こんにちは!KINTOテクノロジーズの勉強会事務局スタッフです。 先日、「 KINTOテクノロジーズ MeetUp!~情シスによる情シスのための事例シェア4選~ 」というタイトルで「コーポレートIT領域に特化した、事例発表+座談会形式の勉強会」を開催しました。 開催に先立ち、「勉強会の企画~事務局立ち上げ」までのストーリーを「 はじめての「KINTOテクノロジーズ MeetUp!」が開催されるまで 」という記事でご紹介しました。 今回は、その続編となる「開催に至るまでの、事務局活動のあれこれ」をご紹介していきます。 前回に引き続き、「自社でゼロから勉強会を立ち上げ、推進していきたい!」と考えている方のご参考になれば幸いです。 前回の記事では、主に 勉強会の企画立案 事務局メンバー・登壇者の募集 未検討事項のディスカッションを実施 役割分担と、アジャイルな進行管理を開始した といった内容までを記載していました。 ここからは、「具体的にどのような役割分担があったのか?」「それぞれどのような活動をおこなったのか?」といった内容を掘り下げていきたいと思います。 経営層への事前報告 今回の勉強会は「個人や有志」ではなく「会社の活動」として実施するものとなります。 適切な会社の支持を得るためにも「経営層への報告と、活動に対しての理解やアドバイスをもらう」ことが非常に重要です。 そのため、今回は以下の流れで経営陣への事前報告を実施する事としました。 副社長(兼CIO&CISO)への報告:まずは「開催する事」自体のお伺い+支援願い 社長への報告:目的やKPI、利用設備や予算についてのお伺い もちろん、報告となると「報告のための場のセッティングや事前準備」が必要になります。しかしながら、以下のような形とすることで、比較的にコストをかけずに実施する事ができました。 副社長への報告 実施タイミング:定期実施される自部署の定例報告会の場を利用して報告 報告資料:元々の企画書をほぼそのまま利用。予算についての詳細は、後日補足 社長への報告 実施タイミング:採用チームの定例報告回の場を利用して報告 報告資料:企画書を3枚のスライドに集約し、「概要」「目的」「予算」の3点でシンプルに報告 結果として、いずれの場においても「まずはやってみよう」というポジティブな反応をいただく事ができました。 会場手配 KINTOの室町オフィスでは「KINTO TOKYO Junction(通称:Junction)」という、会社紹介や社外への発信の際に毎回使われる「映え」スポットがあります。 はじめての勉強会を実施するにあたっては、この「映え」スポットを利用しない手はありません。 会場手配 Junctionは「KINTO」の名を冠しているのですが、所有は親会社の「トヨタファイナンシャルサービス」なのです。 正式な利用の際には、親会社の許可が必要となります。とはいえ、申請はメール一本ででき、基本的にOKもらえるものとなっております。 今回の利用にあたっても、特に問題なくOKがでました。 ビル手配 会場はセキュリティゲートのあるビルなので、外部のお客様を迎えるにあたってセキュリティゲートの外側に受付を設ける必要がありました。 これにはビル側に事前に申し入れ、机を置かせてもらうようお願いしました。 こちらも、問題なくOKをいただけました。 また、ビルに許可をいただいた際に、エントランスに行くまでの自動ドアも、定時外(18時以降)になると施錠(内側からは解錠可能。外から入るにはIDカードが必要)されてしまう。ということが発覚。 その対策をビル側に相談したところ、小さい看板の設置OKをいただけました。相談はするものですね。 会場レイアウト 設備利用はOKとなりました、あとは会場をどうレイアウトするか! 当初大型モニタを数台用いて発表することを考えていたのですが、プロジェクターのスクリーンが発見され、プロジェクターをしたい!となりました。 ですが肝心のプロジェクターがなかったのですが、今後の利用も視野に入れた上で急遽調達しました。 (このときのみんなの動きもまた、OneTeamで素晴らしかったです) プロジェクターを主体にして、かつ可能な範囲で可能な限り多くの方に参加いただきたい!としてできたレイアウトはコチラになります。 机や椅子の手配 机や椅子は、Junctionにもともと置かれていたものを利用したのですが、それだけでは足らず。。。 社内で利用できそうな机や椅子をかき集めました。 主には休憩スペースの机と椅子をお借りして、無事必要数の確保ができました。 当日 当日は運営スタッフがみんな能動的に動き、とてもスピーディに設営ができました! また、片付けも素早く、これもOne Teamをとても感じました。みんなすごい! 最後に Junctionで外部のお客さんを招待するのは、会社としてもはじめてのことでした。 その中で、より多くの人に、よりよい状態で見ていただきたい。とみんながOne Teamとなって取り組めました。 勉強会は今後も組織として進めていく予定なので、今回の結果をもとに、より滑らかに楽しんでいただけるようにしていく所存です! 軽食手配 勉強会で交流会を行うことになった 勉強会を開催する流れの中で、交流会も行うこととなりました。 やはり交流会といえば軽食。よし準備だ! 軽食だ! やはり勉強会といえばピザ。今まで参加してきた勉強会で提供される率が一番高かったため、その印象が強く残っております。 初回からインパクトを出すものにしたい!という気持ちはあるのですが、はじめてのことなので無茶はできません。ということで、大人しくピザにしました。カロリーは正義。 そして、ピザといえばコーラ。この2つがあればよいな!と思ってたのですが、他の飲物も用意しろ。とのお達しがあり、その他のアルコール類も用意しました。 どのくらい用意するか? ~ピザ編~ 今まで他の勉強会に参加してる中で量まで意識したことはありません。どのくらい用意すればいいのか。。。 用意しようと考えていたLサイズのピザは12切れで一般的に3~4人前とのこと。 今回、「軽食」という扱いなので1枚で5人前。という扱いにすることしました。 参加してきた勉強会でも、だいたい2切れ程度食べてたな。という個人的経験も考慮し。 最終的に、最大参加者が40人に運営分を10名として50人分で10枚のピザを手配しました。 どのくらい用意するか? ~飲物編~ こちらも個人的経験を元に算出しました。1イベントでだいたい2~3缶を飲んでたな・・・。 ということで1人あたり3本調達することとしました。 内訳としては、アルコール類と炭酸飲料を1:1で用意することとしました。 40人参加で120本の手配となります。 ですが、、、炭酸飲料については、ペットボトルの方が利便性が高い。ということで変更となり、また発注に都合のいい数量で注文したため48本(24本が入った箱を2箱)となりました。 トータルで用意したのは、アルコール60本。炭酸飲料48本の計108本用意しました。 いつまでに手配するか? ピザは前日。飲物は3日前に手配をしました。 すべて無事トラブルなく納品受領できました。 結果はどうなった? ピザ:あまりなし アルコール:8本あまり →52本消費 炭酸飲料:21本あまり →27本消費 当日参加者20名程度で、上記の結果となりました。 この中には当日スタッフの飲食分も含まれております。 ピザに関しては量が足らなかった。と感じております(運営スタッフまでは行き渡らなかったため)。というのも、交流会の形式が「座談会」として、KTCスタッフを囲んでの会となり、話を聞く時間が長くなる会だった=食べる時間が多くなった。と分析しております。 また、飲物についてはアルコールについてはちょうど良かったと思うのですが、炭酸飲料が多すぎた印象です。 「お茶が欲しかった」という声もあり、炭酸飲料の代わりにお茶も用意しておくと良かったと感じました。 最後に はじめての勉強会での軽食提供。ということで、わからないことも多い中でしたが、なんとか大きな不満が出ない形での提供はできたと考えております。 次回実施時には、よりよい形で提供できるようにしたいと考えております! ノベルティ製作 O・MO・TE・NA・SHI 我々KINTOテクノロジーズは2021年4月に設立されたまだ新しい会社です。 そして今回のイベント開催形式はオフライン、つまり会場である弊社まで足を運んでいただく必要があります。 前述の軽食やドリンクもありますが、せっかくなので 皆様に持って帰っていただけるモノ 会社を覚えていただくきっかけになるモノ を準備したいと思いノベルティを製作することにしました。 どう実現するか 事務局メンバーで話し合った結果満場一致で「ノベルティを作ろう!」となり、ノベルティ製作チームが始動しました。 1.何を作るか まず動いたのが「どんなノベルティにするか」です。 もちろん予算の制約もあり見込まれる来場者の方を想定しあーでもないこーでもないを話し合いました  あーでもないこーでもないを語り合った資料の一部 そして今回は「ステッカー」を製作することに決定しました! 教訓: 無限に広がる思いを現実的な落とし所に着地させることが大切 2.どう作るか モノはステッカーに決まりました。ステッカー製作自体は別の社内イベントで作成した実績があり、ノウハウのあるデザイン部門へイベントの主旨、コーポレートエンジニアとは、予想される来場者の属性・興味といった相談をすることで出来上がったのがこちらです! テッテレー! この2つのパターンから今回のイベントにおけるノベルティとして価値を発揮する方を議論し、白ベースのコーポレートカラーバージョンを製作することに決定しました! どうなった そして粛々と発注を進め、決済を進め、納品を待ち・・・ テッテレー!(2回目) 無事イベント開催までに製作完了いたしました! 様々な部署を超えOne Teamとして製作したこのノベルティが今後もたくさんの場所で使っていただき、KINTOテクノロジーズという会社を知ってもらうきっかけになれば大変嬉しく思います。 プロモーションと計測 まとめると この勉強会の成果をどう測るのか、そして勉強会をどうやって告知するのか、ということを考えました。 会社への報告材料と、改善のための指標を集めることを目的に、イベントへの流入とイベントによる影響を計測しつつ、できる限りのプロモーションを行いました。 実際に実施したこと、考えたこと、実施結果を共有します。 背景 まず考えたのは、会社への結果報告です。勉強会の実施結果を会社に報告するにあたり、参加人数などの数字もそうですが、勉強会の効果として「KTCの認知度向上」を謳っていたので、それを示すようなデータを集める必要がありました。 そして勉強会自体は2回目・3回目も実施していきたいと考えていたので、継続的に改善していくための指標は必要だと考えました。 何より、初めて開催する社外向け勉強会なので何人ぐらい参加してくれるのか正直まったく想像がつきませんでした。「参加者0人」を全力で回避するために、できる限りの告知方法を試しました。 最終的には、ざっくり以下の指標を集めることに決めました。 どのチャネルからどのくらい流入があったのか 勉強会の結果、どのくらいKTCの認知度は上がったのか やったこと、考えたこと 欲しい指標を可視化するため、まずは流入の構造をざっくり書き出しました。 イベントへのエントリーはconnpassで受け付けることにしたので、connpassへの流入を計測。そして勉強会・座談会の結果がどのように認知アップに繋がったのかを計測することにしました。 情シスのイベントなので、「情シスSlack」で告知させてもらうことは決めていました。加えてKTCは テックブログ やX(旧Twitter)を運営しているので運営チームに告知を依頼しました。そして全社員に向けて、SNSで拡散・告知の依頼を社内Slackで呼びかけました。 勉強会・座談会の結果としては、Xのハッシュタグを用意してpost件数とインプレッション数を拾うことにしました。そして「KTCのことを知っていましたか?」というアンケートから知らなかった人の割合を測り、その割合を合計インプレッション数に掛け合わせることで、知らなかった人に対するリーチ数を半ば強引に測りにいくことにしました。 最後に、イベント後には自社のXアカウント、コーポレートサイト、テックブログへの流入やフォローがどのように変わったか、イベント前後での推移を計測しようと考えました。 結果 たくさんの人に拡散をご協力いただきまして、累計56人の方から参加申し込みしていただき、定員40名は満席状態。当日実際には31名の方にお越しいただくことができました! connpassに対するチャネルごとの流入は以下の通りです。 イベント当日までのXのpost件数は61件、合計インプレッション数は28608でした。そのうち376アクセスされたので、Xを見てくれた人の1.31%がconnpassに来てくれた計算です。 アンケートの結果、イベント参加者の39%は元々KTCを知らなかったことがわかりました。connpassへの訪問者1356人に当てはめると、その39%=約530人が元々KTCを知らなかったことになるので、それだけの人数にKTCを認知してもらうことに成功しました!!(強引) イベント前後で比較すると、自社で運用しているXアカウントのフォロワーは少し増えました。コーポレートサイトとテックブログのPVやUUも、イベント当日はいつもより少し多いかな、ぐらいでした。ですが、少しでも確実に効果があることがわかったので、2回目以降も引き続き計測&改善を続けていきたいと思います! 告知サイト準備 まとめると イベントを告知する媒体としてconnpassを選択し、イベント情報ページを準備しました。 「どんなイベントが人気なのか?」ということを、ランキング上位のイベントから学び、自分達のイベントに実装しました。 connpass自体は非常に簡単にイベントを作成できるサービスで、ページ作成に苦労はしなかったので、その分ターゲットの設定と、伝えるメッセージに気を配りました。 想い はじめての開催イベントなので、参加者0人は怖すぎる。。今の自分達にできる最高のページを作ることを決めました。 やったこと、考えたこと まずは外部サービス利用のために社内申請をしました。初めて取引する/利用する事業者の場合は担当部署でチェックが必要なのですが、ここは問題なくクリアしました。 そして申請にあたって管理方法を定めました。簡単に管理目的・管理対象・利用目的を定めた上で、システムとアカウントの管理者を定め、具体的なアカウント管理方法を簡単に決めました。 申請が降りて実際にconnpassを触れるようになってからは、まず設定可能なすべての項目を洗い出して確認しました。次回以降のイベント開催時の手引きとして残しておきたかったのと、不可逆な設定項目がないかを確認したかったのが理由です。「参加費なしのオフラインイベント」という範囲で確認した結果、変更不可、もしくは制限のある項目は以下の2つだけでした。 グループ:変更不可 参加内容.参加枠:参加枠は 申込者がいない間だけ 削除可能 ほとんどの項目は変更可能でした。でも開催日時や会場などが変わったら参加者は混乱するので、追加はしても、変更/削除はしないほうが良いと思います。 イベント情報ページの仕様を確認するのと併せて、人気のイベントを分析しました。connpassのイベントランキングを眺めて、自分達のものと同じ属性のイベントのうち「なぜかめっちゃ人気なイベント」を20個ほどピックアップしました。それらを順番に眺めて、大切だと感じる要素を抽出して抽象化し、自分達のイベント情報ページに適用しました。 仕様と考慮事項がわかったので、ここで改めて、基本設計チックな部分を固めました。「イベント情報ページ」という詳細設計の前に、そもそもの勉強会の意図を具体化し、①ターゲットとなるユーザー、②メッセージ、③コミュニケーションの基本ルールを言語化しました。 ①ターゲットとなるユーザー 「勉強会に積極的なコーポレートエンジニア」をターゲットに設定しました。「他社事例を知りたい」「外の情シスと繋がりたい」というニーズを仮設定し、そこに対してイベント情報ページの文言を作成しました。 ②メッセージ 「他の会社の情シスってどんな感じでやってるの?」をざっくばらんに話しましょう!というメッセージを置きました。「勉強会文化を広げたい」というのがKINTOテクノロジーズMeetUp!の主題で、自分達も伝えたいし、他の人たちの話も聞きたい。それを実現するために、座談会という枠組みを設け、内外問わず語り合う場を作りたいと考えました。 ③コミュニケーションの基本ルール 「イベントはあくまで勉強としてのインプットとアウトプットの場とする」ということをルールとして定めました。せっかく来てもらったんだから、事業のこと、採用のこと、KTCの良いところをアピールして訴求したい。。という想いはグッと抑えて、あくまで「情シスによる情シスのための勉強会」というところを徹底しました。 イベントを公開する段になったらテクニカルな話として、定員数を少なめからスタートして、必要になったら引き上げる作戦にしました。 枠がギリギリの方が駆け込み需要が見込めそうなので 申し込みが少なくても恥ずかしくないので(重要) 結果 こんな感じになりました 【第1回】KINTOテクノロジーズ MeetUp! - connpass 人気のページを眺める中で得た学びは、以下のような要素です。 誰に向けたイベントか、参加した結果何を得られるかが明確だと人が来やすい 安心できそうなイベントだと人が来やすい 有名企業、有名人など 過去のイベントの雰囲気がわかる画像や動画があってもいいかも 旬なトピック(ChatGPTなど)は人が集まるようだ 開催日直前にリマインドするための通知メールも活用しました。告知から開催まで期間が空いてしまう場合には、参加者と運営サイド双方のモチベーションを保ち続ける意味合いでも、タイミングを見てリマインドすることをおすすめします。 セッション取りまとめ 概要 当日の段取りを包括的にまとめました。 具体的にはイベント当日のタイムテーブルの作成、座談会の企画と会場レイアウト決め、発表資料の取りまとめ、イベントの進行管理など。 初めてのイベントでしたが、スタッフ全員でプロアクティブに仕事を探しまくった結果、大きなトラブルもなく、楽しくイベントを終えることができました! 重要なポイント 「初めてのイベント」 実施内容/考慮事項 イベント当日のタイムテーブルの作成 座談会の企画と会場レイアウト決め 発表資料の取りまとめ イベントの進行管理 実行結果 大きなトラブルもなく、楽しくイベントを終えることができました。 初めてのイベントで、何が起こるか予測がつかない中で、スタッフ全員アドレナリンMAXで目を光らせていました。誰の役割でもない仕事、タスクにならないタスクを、1人1人が能動的に探し続けたからこそ成功したイベントだと思います! 登壇者による「事例発表資料」の準備 「事例発表」は、今回の勉強会におけるメインコンテンツです。勉強会での登壇経験も人それぞれであっため、大枠の流れを揃えた上で、定期的に合流するポイントを作り、取り残される人が出ないように資料準備を進行しました。 スライドテンプレートの統一 「発表資料の体裁は整えた方が良い」という判断から、利用するテンプレートの統一をおこないました。自社用のスライドテンプレートは存在していたため、こちらはスムーズに合意できました マイルストーンを区切った締め切り設定 ギリギリまで締め切りを設定すると、人により進行のムラが出てしまうため、以下のようなマイルストーンを区切り、全員の資料作成スケジュールを揃えていきました 初回の短期締切:ザックリ「2週間後」を締め切りに設定し、そのタイミングで皆の様子を確認 見せ合いっこ会:「できていない」事を責めず、だけども「資料作成」を促す相互確認会の実施 副社長レビュー:事前に副社長のお墨付きをもらうべく、そこに向けた「完成版」の締切を設定 事前リハーサル:開催の一週間前に「発表者同士でのリハーサル」を実施し、完成度を高める 結果として、最後の「事前リハーサル」においては、皆さんほぼ「資料完成」+「時間枠内に収まる」形での準備を終え、安心して開催当日を迎える事ができるようになりました。 最後に このような形で、事務局のメンバーがプロアクティブに活動してくださった結果、無事に当日の開催を迎えることができました。 これはまさに、私たちがワーキングスタンスとして掲げる「 One Team, One Player 」が体現できたひとつの事例かなと思っています。 ご参加くださった皆さま、運営に関わってくださったすべての皆さま、ありがとうございます! なお、今回の記事以外にも、「運営スタッフ視点でのテックブログ記事」や「登壇者による事例発表の紹介テックブログ記事」が後日公開される予定です。そちらもどうぞよろしくお願い致します!
#iwillblog → #ididblog ということでみなさんこんにちは。モバイルアプリ開発GでiOSを担当している小山です。iOSDC 2023に参加してきたので、遅ればせながらその内容を紹介したいと思います。弊社からは参加した小山とGOSEOからそれぞれ紹介させていただきます。 今年はiOSエンジニア以外の弊社テックブログ運営メンバーも参加しており、運営目線での記事が iOSDC Japan 2023参加レポート(運営目線) にまとめてあるのでぜひご一読ください! また、昨年のiOSDC参加レポートも #iwillblog: iOSDC Japan 2022参加レポート にあります。 Part of KOYAMA 私はiOSDCに初めて現地参加してきました。現地の各社さんのブースで紹介されていた内容や、各セッションを聞いてみて感じた内容をまとめたいと思います。 現地ブース 3日間かけてほとんどのブースを回ることができ、実際に働くiOSエンジニアの仲間の話を多く聞くことができました。やはりiOSエンジニアとしては、LINEさんのコードレビューチャレンジや、DeNAさんの脳内SwiftUIレンダリングが楽しかったですね。特に脳内SwiftUIレンダリングは普段SwiftUIを触っている身としてプライドがあったので意地でも解いてやろうと思って挑戦しましたが、使ったことのないコンポーネントのレンダリングができず、悔しいですが惨敗でした。(その分楽しく学ばせていただきました) 他にも、ZOZOさんのブースではARメイクを楽しませてもらいました。顔のパーツの認識もすぐに実現できるということを目の当たりにして、とても新鮮な気持ちになれました。どうやら真っ赤リップが似合いすぎてしまうようで、新たな発見もありました(?)。 似合いすぎてしまうのでちょっとだけ顔を隠しました また、様々なノベルティを用意してくださるスポンサーが多く、その中でもFindyさんとdipさんが並んで景品くじをやっていたのでこちらも挑戦しに行きました。 しかし結果はこちらも惨敗・・。1日1回のチャレンジ制限の中、特にFindyさんのくじでは2回の挑戦どちらも「大凶」でした。悔しい・・。(前後に大吉を当てている人がたくさんいた) 大凶のくじを2日連続で手に入れるのもレアらしい あれ、私普通にイベントを楽しんでないか? 参加セッション もちろんメインであるセッションも視聴しました。その中で気になったセッションについてコメントしたいと思います。 Appleにおけるプライバシーの全容を把握する @akatsuki174 さんによるプライバシーに関するレポートでした。Appleはカメラアクセスや位置情報など様々な情報に対して、OSが制御をかけてくれます。そのためうっかりおかしな情報にアクセスすることがありません。この厳密さは私がiOS開発のことを好きな理由の一つでもあります。その分、ストア審査などでよくチェックされる項目なので、エンジニアとしてはしっかりキャッチアップしておきたいところです。 セッションの中で特に気になったのが、位置情報に関する許可状態です。 CLLocationManager を使った位置情報の取得では、「常に位置情報を取得」したい場合に段階を踏んで許可してもらう必要があるとのことで、これは初耳でした。 公式ドキュメントには以下のように記載がありました。 You must call this or the requestWhenInUseAuthorization() method before your app can receive location information. To call this method, you must have both NSLocationAlwaysUsageDescription and NSLocationWhenInUseUsageDescription keys in your app’s Info.plist file. なるほどなるほど、常に位置情報を取る( requestAlwaysAuthorization() )ためには、先にアプリの使用中は許可( requestWhenInUseAuthorization() )してもらわないとならないのですね。なんとなく見たことのある機能でしたが、仕組みは初めて知ったためとても学びになりました。 個人的には当日収録でのご登壇だったakatsukiさんが、マネキンの頭部のみ投影されて喋っている姿がおもしろくて好きでした。笑 iPadだけで完結させるiOSアプリ開発の全て こちらはLTの一部の話でしたが、何が何でもiPadのみでiOS開発をするといった内容でした。結論として可能でしたが、GitHubが使えないというのが大きな問題であるとのことで、まさにその通りだと思いました。 しかしMacBookなくともアプリの開発がある程度進められるようになったのは時代ですね。いつでもどこでも開発できるのはエンジニアにとって朗報だと思いました。 身に覚えのないDeveloper Program License違反を通告されてアプリの検索順位を下げられた時の闘い方 LTからもう1本、おもしろかったセッションです。特定の日時だけアクセス数が激増するアプリを作ったところ、Appleから不正を疑われてアプリの検索順位を下げられ現在もバトル中という、何とも不憫な話でした。 アプリの性質上、節分当日に利用数が大きく増えるというのは納得できましたし、Appleが危険視するのもよく理解できました。しかしAppleがなかなか問い合わせに対応してくれないというのは、解決が難しい議題かと思います。こちらは個人開発の話でしたが、企業として作成するアプリでも同様のパターンはありうるため、ありがたく今後の知見とさせていただきました。 まとめ of KOYAMA 以上、小山パートとなります。お祭り感のあるiOSDC、最高でした!今年は三日間終日の参加が難しかったのですが、来年こそは終日参加しようと強く思いました。また、X(Twitter)で見かけるiOS界隈の方々と直接お話しができたり写真を撮っていただけて、そういった点でも満足感の高いイベントでした。 Part of GOSEO 私はiOSDCに初めてオンライン参加しました。開催日前に視聴してみたいと思ったセッションを視聴したフィードバックをまとめてみました。 ノベルティが豪華 他のみんながノベルティゲットしたぜって言っている中、自分はまだかなとウキウキワクワクで待ってました。 登録住所をミスっちゃって、運営様から配送できないと言う連絡がありました。運営の方、ご迷惑をおかけしました。 無事にノベルティゲットした後、ノベルティで頂いた小さなカップは大切に活用させていただいております(出社日限定) 豪華なノベルティボックス 職場で使うのにちょうどいいマグカップ 参加セッション UIのブラックボックスを探る OS提供のUIと比べるとカスタムUIの品質は悪くなる傾向があるけど、特定の条件のもとではカスタムUI化は必要になる時があるというお話を聞いて、カスタムUI作成はエンジニアあるあるなんだと共感しました。 カスタムUI全てが悪いことではなく、HIGを準拠して作成したり、OS提供のUIを分析するとカスタムUIも良くなるというお話も聞いて、今後の実装で心掛けたいと思います。 また、分析するときにフォーカスを当てるべきところの説明もしていて、画面のHIGの要素を分析し、UIの法則性を見つけることが大事である、UIはユーザーにとって当たり前を実装するのが大事である、と言ってました。 ユーザーにとって当たり前の動作や慣れた動作を実装することでアプリはユーザーフレンドリーさが向上して、ユーザーがアプリ使用時に違和感がなくなるということでした。 自分が凄いと一番感じたのは、公開アプリそのもののUIを分析するツールでした。 View Hierachy DebuggerはiOSエンジニアであればよく知られるツールですが、それはローカル内のアプリでしか使えない制約があります。 Fridaを使うとMapsのようなアプリのUI構造の調査もでき、画面上では確認できないUI構造を分析できるよと、ツールの紹介してました。 導入方法も説明付きで優しいなぁーと思い、やってみてぇというモチベが上がりました。 旅行アプリでより正確にパスポートを読み込む技術 ~ MLKit / Vision / CoreNFC ~ MLKitとVisionのSPMへの対応性、実装の簡易性、およびOCRの精度を比較説明をしていました。 実装もOCR精度も同等レベルの判定をしていましたが、SPMの対応のしやすさで、Visionが優っていたみたいでした。その後はどのようにパスポートの文字をVisionを使用して読み込む実装をしていくのか説明がありました。 具体的にはパスポートのNFCを使用して、OCRの読み取り間違いをどう補完したかのお話がありました。また、NFCの実装方法の紹介もあり、すごく内容の濃いセッションでした。 まとめ of GOSEO 以上、GOSEOパートとなります。普段触らない、気づかない知識に触れることができるiOSDC、Greatでした。来年も是が非でも参加したいです。自分の立ち位置とか目指す方向性とか知らないことに気づける素晴らしい機会を得れたイベントでした。 最後に これにて、 #ididblog となります!執筆が遅くなってしまったので、来年はもっと早くアウトプットできるようにしていきたいと思います。 来年のiOSDC 2024まで待ち遠しいですね!
はじめに こんにちは!KINTOテクノロジーズの勉強会事務局スタッフです。 先日、「 KINTOテクノロジーズ MeetUp!~情シスによる情シスのための事例シェア4選~ 」というタイトルで「コーポレートIT領域に特化した、事例発表+座談会形式の勉強会」を開催しました。 開催に先立ち、「勉強会の企画~事務局立ち上げ」までのストーリーを「 はじめての「KINTOテクノロジーズ MeetUp!」が開催されるまで 」という記事でご紹介しました。 今回は、その続編となる「開催に至るまでの、事務局活動のあれこれ」をご紹介していきます。 前回に引き続き、「自社でゼロから勉強会を立ち上げ、推進していきたい!」と考えている方のご参考になれば幸いです。 前回の記事では、主に 勉強会の企画立案 事務局メンバー・登壇者の募集 未検討事項のディスカッションを実施 役割分担と、アジャイルな進行管理を開始した といった内容までを記載していました。 ここからは、「具体的にどのような役割分担があったのか?」「それぞれどのような活動をおこなったのか?」といった内容を掘り下げていきたいと思います。 経営層への事前報告 今回の勉強会は「個人や有志」ではなく「会社の活動」として実施するものとなります。 適切な会社の支持を得るためにも「経営層への報告と、活動に対しての理解やアドバイスをもらう」ことが非常に重要です。 そのため、今回は以下の流れで経営陣への事前報告を実施する事としました。 副社長(兼CIO&CISO)への報告:まずは「開催する事」自体のお伺い+支援願い 社長への報告:目的やKPI、利用設備や予算についてのお伺い もちろん、報告となると「報告のための場のセッティングや事前準備」が必要になります。しかしながら、以下のような形とすることで、比較的にコストをかけずに実施する事ができました。 副社長への報告 実施タイミング:定期実施される自部署の定例報告会の場を利用して報告 報告資料:元々の企画書をほぼそのまま利用。予算についての詳細は、後日補足 社長への報告 実施タイミング:採用チームの定例報告回の場を利用して報告 報告資料:企画書を3枚のスライドに集約し、「概要」「目的」「予算」の3点でシンプルに報告 結果として、いずれの場においても「まずはやってみよう」というポジティブな反応をいただく事ができました。 会場手配 KINTOの室町オフィスでは「KINTO TOKYO Junction(通称:Junction)」という、会社紹介や社外への発信の際に毎回使われる「映え」スポットがあります。 はじめての勉強会を実施するにあたっては、この「映え」スポットを利用しない手はありません。 会場手配 Junctionは「KINTO」の名を冠しているのですが、所有は親会社の「トヨタファイナンシャルサービス」なのです。 正式な利用の際には、親会社の許可が必要となります。とはいえ、申請はメール一本ででき、基本的にOKもらえるものとなっております。 今回の利用にあたっても、特に問題なくOKがでました。 ビル手配 会場はセキュリティゲートのあるビルなので、外部のお客様を迎えるにあたってセキュリティゲートの外側に受付を設ける必要がありました。 これにはビル側に事前に申し入れ、机を置かせてもらうようお願いしました。 こちらも、問題なくOKをいただけました。 また、ビルに許可をいただいた際に、エントランスに行くまでの自動ドアも、定時外(18時以降)になると施錠(内側からは解錠可能。外から入るにはIDカードが必要)されてしまう。ということが発覚。 その対策をビル側に相談したところ、小さい看板の設置OKをいただけました。相談はするものですね。 会場レイアウト 設備利用はOKとなりました、あとは会場をどうレイアウトするか! 当初大型モニタを数台用いて発表することを考えていたのですが、プロジェクターのスクリーンが発見され、プロジェクターをしたい!となりました。 ですが肝心のプロジェクターがなかったのですが、今後の利用も視野に入れた上で急遽調達しました。 (このときのみんなの動きもまた、OneTeamで素晴らしかったです) プロジェクターを主体にして、かつ可能な範囲で可能な限り多くの方に参加いただきたい!としてできたレイアウトはコチラになります。 机や椅子の手配 机や椅子は、Junctionにもともと置かれていたものを利用したのですが、それだけでは足らず。。。 社内で利用できそうな机や椅子をかき集めました。 主には休憩スペースの机と椅子をお借りして、無事必要数の確保ができました。 当日 当日は運営スタッフがみんな能動的に動き、とてもスピーディに設営ができました! また、片付けも素早く、これもOne Teamをとても感じました。みんなすごい! 最後に Junctionで外部のお客さんを招待するのは、会社としてもはじめてのことでした。 その中で、より多くの人に、よりよい状態で見ていただきたい。とみんながOne Teamとなって取り組めました。 勉強会は今後も組織として進めていく予定なので、今回の結果をもとに、より滑らかに楽しんでいただけるようにしていく所存です! 軽食手配 勉強会で交流会を行うことになった 勉強会を開催する流れの中で、交流会も行うこととなりました。 やはり交流会といえば軽食。よし準備だ! 軽食だ! やはり勉強会といえばピザ。今まで参加してきた勉強会で提供される率が一番高かったため、その印象が強く残っております。 初回からインパクトを出すものにしたい!という気持ちはあるのですが、はじめてのことなので無茶はできません。ということで、大人しくピザにしました。カロリーは正義。 そして、ピザといえばコーラ。この2つがあればよいな!と思ってたのですが、他の飲物も用意しろ。とのお達しがあり、その他のアルコール類も用意しました。 どのくらい用意するか? ~ピザ編~ 今まで他の勉強会に参加してる中で量まで意識したことはありません。どのくらい用意すればいいのか。。。 用意しようと考えていたLサイズのピザは12切れで一般的に3~4人前とのこと。 今回、「軽食」という扱いなので1枚で5人前。という扱いにすることしました。 参加してきた勉強会でも、だいたい2切れ程度食べてたな。という個人的経験も考慮し。 最終的に、最大参加者が40人に運営分を10名として50人分で10枚のピザを手配しました。 どのくらい用意するか? ~飲物編~ こちらも個人的経験を元に算出しました。1イベントでだいたい2~3缶を飲んでたな・・・。 ということで1人あたり3本調達することとしました。 内訳としては、アルコール類と炭酸飲料を1:1で用意することとしました。 40人参加で120本の手配となります。 ですが、、、炭酸飲料については、ペットボトルの方が利便性が高い。ということで変更となり、また発注に都合のいい数量で注文したため48本(24本が入った箱を2箱)となりました。 トータルで用意したのは、アルコール60本。炭酸飲料48本の計108本用意しました。 いつまでに手配するか? ピザは前日。飲物は3日前に手配をしました。 すべて無事トラブルなく納品受領できました。 結果はどうなった? ピザ:あまりなし アルコール:8本あまり →52本消費 炭酸飲料:21本あまり →27本消費 当日参加者20名程度で、上記の結果となりました。 この中には当日スタッフの飲食分も含まれております。 ピザに関しては量が足らなかった。と感じております(運営スタッフまでは行き渡らなかったため)。というのも、交流会の形式が「座談会」として、KTCスタッフを囲んでの会となり、話を聞く時間が長くなる会だった=食べる時間が多くなった。と分析しております。 また、飲物についてはアルコールについてはちょうど良かったと思うのですが、炭酸飲料が多すぎた印象です。 「お茶が欲しかった」という声もあり、炭酸飲料の代わりにお茶も用意しておくと良かったと感じました。 最後に はじめての勉強会での軽食提供。ということで、わからないことも多い中でしたが、なんとか大きな不満が出ない形での提供はできたと考えております。 次回実施時には、よりよい形で提供できるようにしたいと考えております! ノベルティ製作 O・MO・TE・NA・SHI 我々KINTOテクノロジーズは2021年4月に設立されたまだ新しい会社です。 そして今回のイベント開催形式はオフライン、つまり会場である弊社まで足を運んでいただく必要があります。 前述の軽食やドリンクもありますが、せっかくなので 皆様に持って帰っていただけるモノ 会社を覚えていただくきっかけになるモノ を準備したいと思いノベルティを製作することにしました。 どう実現するか 事務局メンバーで話し合った結果満場一致で「ノベルティを作ろう!」となり、ノベルティ製作チームが始動しました。 1.何を作るか まず動いたのが「どんなノベルティにするか」です。 もちろん予算の制約もあり見込まれる来場者の方を想定しあーでもないこーでもないを話し合いました  あーでもないこーでもないを語り合った資料の一部 そして今回は「ステッカー」を製作することに決定しました! 教訓: 無限に広がる思いを現実的な落とし所に着地させることが大切 2.どう作るか モノはステッカーに決まりました。ステッカー製作自体は別の社内イベントで作成した実績があり、ノウハウのあるデザイン部門へイベントの主旨、コーポレートエンジニアとは、予想される来場者の属性・興味といった相談をすることで出来上がったのがこちらです! テッテレー! この2つのパターンから今回のイベントにおけるノベルティとして価値を発揮する方を議論し、白ベースのコーポレートカラーバージョンを製作することに決定しました! どうなった そして粛々と発注を進め、決済を進め、納品を待ち・・・ テッテレー!(2回目) 無事イベント開催までに製作完了いたしました! 様々な部署を超えOne Teamとして製作したこのノベルティが今後もたくさんの場所で使っていただき、KINTOテクノロジーズという会社を知ってもらうきっかけになれば大変嬉しく思います。 プロモーションと計測 まとめると この勉強会の成果をどう測るのか、そして勉強会をどうやって告知するのか、ということを考えました。 会社への報告材料と、改善のための指標を集めることを目的に、イベントへの流入とイベントによる影響を計測しつつ、できる限りのプロモーションを行いました。 実際に実施したこと、考えたこと、実施結果を共有します。 背景 まず考えたのは、会社への結果報告です。勉強会の実施結果を会社に報告するにあたり、参加人数などの数字もそうですが、勉強会の効果として「KTCの認知度向上」を謳っていたので、それを示すようなデータを集める必要がありました。 そして勉強会自体は2回目・3回目も実施していきたいと考えていたので、継続的に改善していくための指標は必要だと考えました。 何より、初めて開催する社外向け勉強会なので何人ぐらい参加してくれるのか正直まったく想像がつきませんでした。「参加者0人」を全力で回避するために、できる限りの告知方法を試しました。 最終的には、ざっくり以下の指標を集めることに決めました。 どのチャネルからどのくらい流入があったのか 勉強会の結果、どのくらいKTCの認知度は上がったのか やったこと、考えたこと 欲しい指標を可視化するため、まずは流入の構造をざっくり書き出しました。 イベントへのエントリーはconnpassで受け付けることにしたので、connpassへの流入を計測。そして勉強会・座談会の結果がどのように認知アップに繋がったのかを計測することにしました。 情シスのイベントなので、「情シスSlack」で告知させてもらうことは決めていました。加えてKTCは テックブログ やX(旧Twitter)を運営しているので運営チームに告知を依頼しました。そして全社員に向けて、SNSで拡散・告知の依頼を社内Slackで呼びかけました。 勉強会・座談会の結果としては、Xのハッシュタグを用意してpost件数とインプレッション数を拾うことにしました。そして「KTCのことを知っていましたか?」というアンケートから知らなかった人の割合を測り、その割合を合計インプレッション数に掛け合わせることで、知らなかった人に対するリーチ数を半ば強引に測りにいくことにしました。 最後に、イベント後には自社のXアカウント、コーポレートサイト、テックブログへの流入やフォローがどのように変わったか、イベント前後での推移を計測しようと考えました。 結果 たくさんの人に拡散をご協力いただきまして、累計56人の方から参加申し込みしていただき、定員40名は満席状態。当日実際には31名の方にお越しいただくことができました! connpassに対するチャネルごとの流入は以下の通りです。 イベント当日までのXのpost件数は61件、合計インプレッション数は28608でした。そのうち376アクセスされたので、Xを見てくれた人の1.31%がconnpassに来てくれた計算です。 アンケートの結果、イベント参加者の39%は元々KTCを知らなかったことがわかりました。connpassへの訪問者1356人に当てはめると、その39%=約530人が元々KTCを知らなかったことになるので、それだけの人数にKTCを認知してもらうことに成功しました!!(強引) イベント前後で比較すると、自社で運用しているXアカウントのフォロワーは少し増えました。コーポレートサイトとテックブログのPVやUUも、イベント当日はいつもより少し多いかな、ぐらいでした。ですが、少しでも確実に効果があることがわかったので、2回目以降も引き続き計測&改善を続けていきたいと思います! 告知サイト準備 まとめると イベントを告知する媒体としてconnpassを選択し、イベント情報ページを準備しました。 「どんなイベントが人気なのか?」ということを、ランキング上位のイベントから学び、自分達のイベントに実装しました。 connpass自体は非常に簡単にイベントを作成できるサービスで、ページ作成に苦労はしなかったので、その分ターゲットの設定と、伝えるメッセージに気を配りました。 想い はじめての開催イベントなので、参加者0人は怖すぎる。。今の自分達にできる最高のページを作ることを決めました。 やったこと、考えたこと まずは外部サービス利用のために社内申請をしました。初めて取引する/利用する事業者の場合は担当部署でチェックが必要なのですが、ここは問題なくクリアしました。 そして申請にあたって管理方法を定めました。簡単に管理目的・管理対象・利用目的を定めた上で、システムとアカウントの管理者を定め、具体的なアカウント管理方法を簡単に決めました。 申請が降りて実際にconnpassを触れるようになってからは、まず設定可能なすべての項目を洗い出して確認しました。次回以降のイベント開催時の手引きとして残しておきたかったのと、不可逆な設定項目がないかを確認したかったのが理由です。「参加費なしのオフラインイベント」という範囲で確認した結果、変更不可、もしくは制限のある項目は以下の2つだけでした。 グループ:変更不可 参加内容.参加枠:参加枠は 申込者がいない間だけ 削除可能 ほとんどの項目は変更可能でした。でも開催日時や会場などが変わったら参加者は混乱するので、追加はしても、変更/削除はしないほうが良いと思います。 イベント情報ページの仕様を確認するのと併せて、人気のイベントを分析しました。connpassのイベントランキングを眺めて、自分達のものと同じ属性のイベントのうち「なぜかめっちゃ人気なイベント」を20個ほどピックアップしました。それらを順番に眺めて、大切だと感じる要素を抽出して抽象化し、自分達のイベント情報ページに適用しました。 仕様と考慮事項がわかったので、ここで改めて、基本設計チックな部分を固めました。「イベント情報ページ」という詳細設計の前に、そもそもの勉強会の意図を具体化し、①ターゲットとなるユーザー、②メッセージ、③コミュニケーションの基本ルールを言語化しました。 ①ターゲットとなるユーザー 「勉強会に積極的なコーポレートエンジニア」をターゲットに設定しました。「他社事例を知りたい」「外の情シスと繋がりたい」というニーズを仮設定し、そこに対してイベント情報ページの文言を作成しました。 ②メッセージ 「他の会社の情シスってどんな感じでやってるの?」をざっくばらんに話しましょう!というメッセージを置きました。「勉強会文化を広げたい」というのがKINTOテクノロジーズMeetUp!の主題で、自分達も伝えたいし、他の人たちの話も聞きたい。それを実現するために、座談会という枠組みを設け、内外問わず語り合う場を作りたいと考えました。 ③コミュニケーションの基本ルール 「イベントはあくまで勉強としてのインプットとアウトプットの場とする」ということをルールとして定めました。せっかく来てもらったんだから、事業のこと、採用のこと、KTCの良いところをアピールして訴求したい。。という想いはグッと抑えて、あくまで「情シスによる情シスのための勉強会」というところを徹底しました。 イベントを公開する段になったらテクニカルな話として、定員数を少なめからスタートして、必要になったら引き上げる作戦にしました。 枠がギリギリの方が駆け込み需要が見込めそうなので 申し込みが少なくても恥ずかしくないので(重要) 結果 こんな感じになりました 【第1回】KINTOテクノロジーズ MeetUp! - connpass 人気のページを眺める中で得た学びは、以下のような要素です。 誰に向けたイベントか、参加した結果何を得られるかが明確だと人が来やすい 安心できそうなイベントだと人が来やすい 有名企業、有名人など 過去のイベントの雰囲気がわかる画像や動画があってもいいかも 旬なトピック(ChatGPTなど)は人が集まるようだ 開催日直前にリマインドするための通知メールも活用しました。告知から開催まで期間が空いてしまう場合には、参加者と運営サイド双方のモチベーションを保ち続ける意味合いでも、タイミングを見てリマインドすることをおすすめします。 セッション取りまとめ 概要 当日の段取りを包括的にまとめました。 具体的にはイベント当日のタイムテーブルの作成、座談会の企画と会場レイアウト決め、発表資料の取りまとめ、イベントの進行管理など。 初めてのイベントでしたが、スタッフ全員でプロアクティブに仕事を探しまくった結果、大きなトラブルもなく、楽しくイベントを終えることができました! 重要なポイント 「初めてのイベント」 実施内容/考慮事項 イベント当日のタイムテーブルの作成 座談会の企画と会場レイアウト決め 発表資料の取りまとめ イベントの進行管理 実行結果 大きなトラブルもなく、楽しくイベントを終えることができました。 初めてのイベントで、何が起こるか予測がつかない中で、スタッフ全員アドレナリンMAXで目を光らせていました。誰の役割でもない仕事、タスクにならないタスクを、1人1人が能動的に探し続けたからこそ成功したイベントだと思います! 登壇者による「事例発表資料」の準備 「事例発表」は、今回の勉強会におけるメインコンテンツです。勉強会での登壇経験も人それぞれであっため、大枠の流れを揃えた上で、定期的に合流するポイントを作り、取り残される人が出ないように資料準備を進行しました。 スライドテンプレートの統一 「発表資料の体裁は整えた方が良い」という判断から、利用するテンプレートの統一をおこないました。自社用のスライドテンプレートは存在していたため、こちらはスムーズに合意できました マイルストーンを区切った締め切り設定 ギリギリまで締め切りを設定すると、人により進行のムラが出てしまうため、以下のようなマイルストーンを区切り、全員の資料作成スケジュールを揃えていきました 初回の短期締切:ザックリ「2週間後」を締め切りに設定し、そのタイミングで皆の様子を確認 見せ合いっこ会:「できていない」事を責めず、だけども「資料作成」を促す相互確認会の実施 副社長レビュー:事前に副社長のお墨付きをもらうべく、そこに向けた「完成版」の締切を設定 事前リハーサル:開催の一週間前に「発表者同士でのリハーサル」を実施し、完成度を高める 結果として、最後の「事前リハーサル」においては、皆さんほぼ「資料完成」+「時間枠内に収まる」形での準備を終え、安心して開催当日を迎える事ができるようになりました。 最後に このような形で、事務局のメンバーがプロアクティブに活動してくださった結果、無事に当日の開催を迎えることができました。 これはまさに、私たちがワーキングスタンスとして掲げる「 One Team, One Player 」が体現できたひとつの事例かなと思っています。 ご参加くださった皆さま、運営に関わってくださったすべての皆さま、ありがとうございます! なお、今回の記事以外にも、「運営スタッフ視点でのテックブログ記事」や「登壇者による事例発表の紹介テックブログ記事」が後日公開される予定です。そちらもどうぞよろしくお願い致します!
Introduction Hello, my name is Go Wada, and I am responsible for the payment platform backend in the Shared Service Development Group. The project I am in charge of has been engaged in Scrum-based development using domain-driven design since our team developed the platform. This article uses the experience gained there to give an example of how this was implemented efficiently by a team. What is "Domain-driven Design (DDD)?" DDD is a method of developing software. It is intended to improve software values and problem-solving ability through modeling. For example, we utilize use-case and domain-modeling diagrams to represent models. Moreover, we try to use ubiquitous language or in other words, to allow developers, business members, and everyone involved to engage in a dialog using the same terms. Of course, one of our goals on the technical side is to improve the quality of our code. For example, rather than creating tangled spaghetti code, we put together loosely coupled highly cohesive implementations that are resistant to change. We focus on preserving consolidation, "Tell, don't ask!" style checks, and on being aware of SOLID . *Addendum: "Domain" refers to the domain in which problems are to be addressed with software. Issues for our team Our team faced the following challenges in introducing domain-driven design. We chose DDD as a software design approach but it was more difficult than we had anticipated We learned individually so there were differences in our understanding The team was made up of people working together for the first time Conversely, the team's policies and vision for the future are: To move ahead with efficient development To improve the maintainability of our systems and increase the speed of function development in future development work (or alternatively, to avoid slowing down once we are on track) Development is an opportunity for learning, so we would like to learn well as a team. Group readings of proposals to address these issues There are a range of ways to address these issues, and we decided to confront them by holding group reading sessions where we read books on domain-driven design. Our aims were to: Read about DDD as a team effort Make learning efficient, with a deeper reach (improving our skills as a team) Gain a common awareness and an understanding of each other through the casual conversations that occur at the group readings Align awareness of assumptions to reduce pull-request conversations Create a sense of team unity through discussions and casual conversations at group reading sessions How we implemented group reading sessions We used the following methods to implement group reading sessions: We engaged in circular group readings of "Domain-Driven Design: A Modeling/Implementation Guide," by Koichiro Matsuoka https://little-hands.booth.pm/items/1835632 Everyone participated with the consent of all product members Once a week, people assigned responsibility for each chapter are nominated to make a 30-minute presentation They read their assigned chapter in advance, and create documents summarizing the important points The presentations take about 15 minutes, with discussions lasting approximately the same time Discussions at group readings Although this is written from memory, conversations generally went as follows. Consistency-wise it would be better if we only ever allow correct instances to exist This is how domain services should be (don't make careless mistakes, better to restrict responsibilities) Better to use specification objects as a single method of validation How to view value objects (it might be safer to use elements comprising aggregate routes as VOs) Aren't the presentation and application layers mixed up? The naming got confused What should we do about the architecture (layered architecture, onion architecture, clean architecture, etc.) Starting modeling Although we couldn't wait to get started on coding, modeling is also important, and so we periodically took time within each sprint to go over it with everyone. Team members who are familiar with payment-related systems and operations were appointed as domain experts. Since the payment system itself is implemented within the system, it is more important to be familiar with the details of the system than with the business. The content implemented was roughly as follows. Using miro, we used sticky notes to brainstorm concepts related to payment. Results of brainstorming We organized the resulting concepts and discussed the relevant points as follows. What payment-related actions are required by a payment platform? What chronological order should these actions take? Which are the aggregation routes? How can we organize the concepts to fit effectively? How are other similar systems organized? Image diagram of conceptual organization *We reevaluated this diagram every time we felt something was not right, as well as after brainstorming. Image diagram of brainstorming progress *Deformed image of work progress. We created domain-model and use-case diagrams of the results of our discussions. Domain model Domain model excerpt Of course, the model was not the end of the process, as we made numerous improvements. For example, initially we intended to make the payment aggregation payment card entity a dedicated aggregation. This was because we had an image of the payment card holding the payment company information, and we had decided that since this is an external system it would be easier to handle aggregation separately. However, any given payment generates information that this key value was used to deal with the payment company, which cannot be separated from payment. We reviewed our assessments so that they were strongly consistent, and decided to include them in a single aggregation. Use case diagram *Although we created use-case diagrams, we discarded them as their content overlapped with that of other documents. We created a glossary. During brainstorming and model creation, we noticed that each member used different terms to explain the same thing. That prompted us to create a glossary of appropriate terms that the team could agree on from the multiple terms that we were using. (We defined both Japanese and English terms.) To ensure that we use defined terms, members gently point out (jokingly) each other's mistakes when they use incorrect terminology. Take the example of a system in which a payment platform is to be installed, which requires contracts to be made for each so-called order unit before payment. We decided to call those contracts "Payment directives." This is because we thought that "contract" could be construed as having a range of meanings. Moreover, this glossary is intended to avoid confusion with terms used in other systems and products (outside the defined context). Glossary image Lessons and benefits from carrying out model and group reading sessions Group reading session Held in parallel with our regular work, the group reading sessions provided us with the following lessons and benefits. The amount learned and the precision of our products increases as we can apply the knowledge from these sessions immediately It is suited to Agile development because we soon have an opportunity to apply this knowledge The ability to have a common understanding improves quality because pull requests are viewed from different perspectives You develop an interest that encourages you to read other related material (you develop momentum to learn) You can learn systematically, not just areas related to your own work, making your learning more versatile You can be more active in these group reading sessions than in sessions on unrelated topics Active conversations create an even better team atmosphere that helps to counter the isolation of remote working *These sessions were very active, making timekeepers a necessity. Modeling Taking time to conduct modeling on a regular basis provided us with the following lessons and benefits. Although we tend to focus on implementation, we have gotten into the habit of basing our thinking on the model Looking at things on a model level gives us a feeling for the overall product When we are about to lose our way during implementation, we can go back to the model for clarification Outlook for the future Although we have implemented the practices described above, at the time of writing we have yet to put them into operation. At our current stage in development, we appear to be successful. However, we hope to assess whether these activities had merit and what their challenges were based on feedback we receive from actually using them in practice. Additionally, to a large extent, domain-driven design itself is more of a path for thinking than a deterministic methodology. We hope to acquire more knowledge, including the information acquired through our operations. Summary of what was learned through the practices described here At the group reading sessions, which were held in parallel with our normal operations, we learned that: It is possible to achieve input and output of learning, reflect learning in our products and the growth of our team's members all at the same time Work-based and experiential learning are linked All related personnel can be actively involved, and conversation used to create a sense of unity. The habits we have acquired through modeling showed us: Although we tend to focus on implementation, we learn to base our thinking on the model Looking at things on a model level gives us a feeling for the overall product, making implementation less localized When we are about to lose our way during implementation, we can go back to the model for clarification, making it more difficult to become confused
Hajimemashite! I’m Moji from UXUI team in the Global Development Group. At KINTO Technologies, my main role is product design, which I love because it blends my business knowledge with my design skills. I aim to create user interfaces that are easy to use, aesthetically pleasing, and generate measurable results. My ultimate objective is always to turn complicated problems into simple, user-friendly experiences that users find satisfying. I'm writing my very first article for the TechBlog! which is about the process of redesigning the TechBlog itself. Exciting, isn’t it? Scope and Obstacles In today's digital world, staying relevant requires constant renovation and reinvention. KINTO Technologies made a big change by deciding to redesign its TechBlog in two phases. Each phase had distinct objectives aimed at enhancing user experience and functionality, with a focused attempt to adhere to the KINTO design system. The image below demonstrates the scope of the redesign after consultation with the tech blog team. Redesign Scope Like navigating through an intricate maze, the redesign process brought along its own sets of challenges. One of the main challenges that demanded meticulous planning and execution was to align the newly integrated features with the KINTO design system , which is not static, but rather a dynamic entity that is constantly evolving, and had limited assortment of web patterns for desktop view only. Adding to the complexity was the timeline constraint, coupled with the requirement of redesigning for dual platforms - mobile and desktop views. The following images highlight key problem areas with the current design in both mobile and desktop views. Key problem areas in mobile view Key problem areas in desktop view Phase One: Focused on Usability and Accessibility The beginning of the redesign process primarily dealt with improving TechBlog’s usability and accessibility in both desktop and mobile . The implementation of a search bar was a major feature that facilitates straightforward access to relevant articles and information. This functionality will make it seamless for readers to navigate through an extensive range of blog content. Search bar in mobile view Search bar in desktop view The integration of category tags was another major improvement in this phase. This feature allows readers to sort and scan through technology-related topics effortlessly, enriching the process of content exploration and further enhancing the browsing experience. Category tags in a scrollable carousel format Category tags are affixed to the right-side bar A critical visual change made at this stage was adjusting the size of the blog posts in the homepage. This change, carried out for both desktop and mobile views, helped ensure a harmonious balance between the readability of the content and the overall visual appeal across all devices, thereby elevating the user interface. Displaying the before and after size of the blog posts in desktop view Phase Two: Cementing Functionality and Multilingual Access During the second phase of TechBlog redesign, other meaningful features were integrated, leading to an uplift in overall functionality and user experience. Notably, a language switch was introduced, catering to English and Japanese readers. This feature, despite initial challenges due to space constraints in the top navigation bar (mobile view), was eventually included in a manner that gave readers an effortless switching between language options. Language switch in mobile view Language switch in desktop view This phase of the redesign also involved adjusting the index placement on the article page for mobile view, ensuring streamlined navigation within lengthier blogs. Index placement for mobile view Additionally, social media buttons were replaced, promoting easy sharing and driving more user engagement in desktop view. Sharing buttons placement for desktop view To guide users who might stumble upon non-existent or removed pages, a 404 page was also designed as part of this phase. Additionally, a direct link to the recruitment section of KINTO Technologies was nestled at the end of each article, serving as a warm invitation to tech-savvy readers to explore potential career opportunities. Mobile view Desktop view Furthermore, during this phase, a feature was incorporated allowing articles to be searched by the writers' names. Two formats were designed for this purpose: The single author format that accommodates multiple writers under one profile, with clickable names to sort articles written by them. The multiple authors format that gives each writer a dedicated profile in addition to being able to sort articles by their respective names. The second format was less prioritized, so the development team proceeded with the first format, ensuring enhanced user experience with a more streamlined author profile approach. Mobile view Mobile view Desktop view Desktop view Objectives The cardinal objective steering this redesign was a commitment to enriching the user experience. Every tweak, addition, and adjustment were aimed at facilitating easy navigation, broadening access to relevant content, and enhancing the overall user interface. illustrating the before and after redesign in both mobile and desktop views The KINTO design system played a key role. While relying on this system, adaptations were also made. Steps were taken to build some components from scratch and tweak some other components locally within the file to meet the precise requirements. This approach balanced adherence to the dynamic design system with the unique functionality needs of the Tech Blog. The following images demonstrate how the footer component , originally designed for the Tech Blog use case, can be applied to various projects after being added to the KINTO design system . Mobile view of the footer component example Desktop view of the footer component example Anticipated outcomes Here's a glimpse of some major expectations: The introduction of integrated search bar and category tags should enable effortless navigation through articles, taking away the hassle and significantly improving the reader's content discovery process. The inclusion of a multilingual feature aims to dissolve language boundaries and make the articles comprehensible to a diversity of readers, particularly those who are English or Japanese speakers. The aesthetic charm and practical utility of the blog posts are anticipated to flourish with the design amendments. Enhanced features such as social media sharing buttons, devised 404 page, and adjusted article post sizes are expected to notably boost user engagement. We foresee that adding a link to potential career opportunities at the end of every article will serve as an effective bridge connecting our tech-inclined readers and KINTO Technologies' recruitment space. This two-phase redesign is currently in implementation and aims to strike a balance between aesthetic appeal, enhanced functionality, and increased usability. Upon completion, a usability testing process might be adopted to gather feedback from readers and ensure the redesign has achieved its set goals. Next Steps The journey of redesigning marked the beginning of a continuous improvement process. The local components tweaked and designed for the TechBlog redesign will now be evaluated for potential inclusion in the KINTO design system. Once confirmed, they'll be made available for use across other projects. This opens up a new world of opportunities, extending this redesign's positive impact beyond the blog and into future integrations. I’m excited to see how this redesign continues to shape the platform's future developments as KINTO Technologies continues to evolve in the fast-paced digital world. References KINTO Technologies - TechBlog KINTO Technologie - Corporation KINTO Technologies - Recruit Nielsen Norman - Usability Testing
Introduction My name is Kinoshita, and I am from the my route Development Group. Normally, I do advanced development for Proof of Concepts, spanning mobile, front-end, and back-end development. I was given the opportunity to take the Licensed Scrum Master Training, which I passed successfully, granting me certification as an LSM. This is an account of my journey to gaining this certification. What is LSM? The LSM is a certification from Scrum Inc. awarded to those who take the Scrum Inc. certified Scrum Master training course and pass the exam. There are multiple Scrum Master certification bodies, with each granting different titles for the same certification. Title Certification Body URL Fee License Renewal Fee LSM, Licensed Scrum Master Scrum Inc https://scruminc.jp/ 200,000 JPY (tax excl.) $50 / year CSM, Certified Scrum Master Scrum Alliance https://www.scrumalliance.org/ 300,000 JPY (tax incl.) $100 / year PSM, Professional Scrum Master Scrum.org https://www.scrum.org/ $150 N/A [Reference: https://www.ryuzee.com/faq/0034/] LSM is a two-day course comprised of lectures and workshops. Completing the course qualifies you to take the examination. The certification must be renewed every year, for which a $50 fee must be paid and the examination passed each time. As such, you have an opportunity every year to consider whether you want to maintain the certification. Reasons for Obtaining Certification KINTO Technologies is aiming to be a cutting-edge online business organization. To that end, it is currently working to change those factors within the Japanese manufacturing industry that hinder progress in terms of culture and the environment, while also tearing away vendor locks, making improvements to legacy systems, systematizing business flows, and other digital transformation (DX) activities. As the company proceeds down this path, there have been a greater number of opportunities for it to choose Agile software development as its methodology. In fact, even the group that I belong to has been choosing to use Agile. And, in reflection of that fact, my manager recommended to me that I take the Scrum Master Training. As in many small-scale development teams, the my route team that I belong to also only has a small number of team members, and, so, it is the case that the Product Owner and Scrum Master roles are fulfilled by the same person. After the recommendation, I talked with a number of friends and colleagues who were both developers and Scrum masters and I began to become more interested in taking the training. I talked again with my superior and, based on the following, decided to take the training. It was not vital that I become a Scrum Master and there would be no issues if I didn't get the certification; however, given that it was not something I had learned systematically up until that point, it seemed like a good opportunity to educate myself; In pushing forward with Scrum and Agile, it might be possible for me to build a Scum personal network; For example, at seminars, I might be able to exchange information on how to utilize Scrum and Agile with people from companies who are facing similar organizational issues as our company; and As a developer, learning what other Scrum Masters think and feel about issues has many benefits in terms of knowing how to respond to these issues. Reasons for Selecting LSM Given that my goal was not to simply gain certification, PSM was not an option for me. Early on, I learned from someone in my company about the well-known CSM certification; however, I was then recommended by another colleague to look at LSM, through which I might be about to build a Scrum community network. Also, I saw that TRI-AD (currently, Woven Planet Holdings, Inc.) of the Toyota Group had adopted it and that it had proven a good match for the company. This increased confidence in LSM within the company and was the reason why I ultimately went with that particular certification. Prior Knowledge With regards to my prior knowledge of what being a Scrum Master comprises, I had read SCRUM BOOT CAMP THE BOOK and the Scrum Guide . In terms of actual experience, while I hadn't worked in any organization that had formally adopted Scrum, I had worked in teams that had loosely incorporated Agile. Contents of Training The training was held online over Zoom. It basically comprised of workshops with participants split up into teams, and lectures. The day before the training, I received an e-mail including the following content: Scrum Guide Glossary Text Zoom Worksheets for Each Team I received a URL for an online white board tool called MURAL . I was able to download completed worksheets in PDF format. The content of the actual course was in-depth academic study into Scrum Master, including its history, what you should do with it, and what actions you need to take to achieve that. With regard to organizing members, team-building exercises were held immediately before the training began where I got to know the other members I would be working with for the first time. I took the training together with a number of colleagues from my company, but a lot of care was put in to not pair people up with other people from the same companies or similar industries. In my team, I was paired with people from completely different industry backgrounds. Because of this, I was made aware of different views and exposed to different knowledge sets that I would not be able to experience in my daily work duties. Progress through the training took the form of moving from classroom type learning to workshops with completion of each learning step, whereby questions were posed to which the goal was to demonstrate understanding of the content by answering said question or putting into practice what we learned. There is a lot of content to learn, and, personally speaking, I felt that the lectures were often longer than the workshops. However, if I hadn't paid attention to the content of the lectures, I wouldn't have been able to do anything in the workshops, so it was important that I maintained my concentration levels for the whole two days. Examination I became eligible to take the certification examination immediately after completing the training course. Although there was no time limit on answering questions, I felt that there were many questions which really tested your depth of understanding in the sense that if you did not understand the content of the training or the texts or Scrum Guide, you would not be able to answer them. For those who are not so experienced in Agile and Scrum, the examination might prove quite tough. However, it does seem as though you can retake the examination free of charge up to one extra time (I passed on my first attempt, so this is just what I heard about retaking the examination during the pre-examination description.) Therefore, there are multiple opportunities to pass. Summary/Thoughts The team mentors and members were cheerful and approachable, with a warm atmosphere present throughout the workshops. Being able to interact in the workshops with people from industries I do not normally come into contact with was really refreshing and a real plus point of the whole experience. However, seeing as how the training was held remotely, there was little interaction, and the speed and depth at which we could open up to one another was drastically reduced compared to meeting in person. Also, one of the people I took the training with seemed a little distant on the first day, never really opening up to the others. Upon listening the interactions of the other team members, they suddenly declared "I'm so jealous". I guess there might be an element of luck involved in whether the team building exercises go well, based on the personality and skill of the members and trainers. (That same person began speaking a lot more on the second day. Clearly, for them, ice-breakers are extremely important. After that, they seemed to settle down much more.) As for the training itself, it was an in-depth academic study of the role of a Scrum Master. The training did not teach how to resolve issues found in organizations that are unable to incorporate Scrum, and so, it was not a silver bullet that would help me fix all the issues I encounter in my daily work duties. It is the responsibility of the individual to find out how best to apply what they learned in the training to their team, organization, or job. For this reason, companies who are able to incorporate everything taught on the course into their organizations and make effective use of that knowledge are rare. Therefore, it is important that each company sees for themselves which aspects are best suited to their setup. If possible, I think it would be great if there were some opportunity to meet with and share knowledge with the people from outside of your company who you took the workshop with or those who have taken the training in the past. I think that would help people broaden their knowledge base and make the training even more effective. Thoughts on how to make use of the training within my company When I talked with some of the other people I did the workshops with, I realized that many of them also found it difficult to make use of Scrum within their organization and that they were facing similar issues to our company. Based on those conversations, I think that the following three patterns are fairly common: If you know what you want to build, Waterfall is more suitable than Scrum If you haven't decided exactly what you want to build and are going to build as you go, Scrum is suitable If there is a free atmosphere in which multidisciplinary teams can be formed as part of efforts to improve a given service, Scrum is suitable In order to make maximum use of the content of the training in your company, you need to ensure there is an environment in which that learning can be applied in the way you imagine. However, doing this from the get-go is easier said than done. I would like to conclude by saying that by making incremental efforts through occasionally correcting the product increments at which the definition of complete breaks down, and searching for ways on how to connect the small individual scrum teams dispersed throughout the company as part of efforts toward Scrum of Scrum , I think it will be possible to make improvements to the current situation.
Introduction Hello. My name is Kairi Watanabe and I work in front-end development at KINTO technologies. As a member of the KINTO development group, I normally work on the development of KINTO ONE services for use in Japan using frameworks such as React.js. The KINTO development group is made up of engineers and accepts multiple new members each month. However, it can be difficult for us to understand the business domain in its entirety when working with a system that is so large in scale. For this reason, we hold orientation training targeting mid-career hires every month in order to support new members and enable them to start playing an active role as soon as possible. In this blog post, I will talk about why having orientation training targeting mid-career highs is important and also about some of the content of actual orientations held in the past. Announcements of in-group orientations Reasons for implementing orientation training So that mid-career hires can play an active a role in the company as soon as possible, it is vital that they become accustomed to the work environment at an early stage and that in-team inter-personal relationships are built through daily communication. There are probably some people who think, unlike with new graduates, orientation training is unnecessary as they already have some actual work experience. However, it is not necessarily the case that mid-career hires will always immediately adapt to changes in their work environment. I think that some hires may not understand how the new workplace functions relative to their previous one, or may not understand specialist terminology specific to the industry or the company. In those cases, I think some might feel anxious or lacking in motivation, even though they have only just joined the company. Before we implemented orientation training in our team, we sometimes would have members who would sit at their desks at a loss, not knowing what to do until they were assigned a specific task. It can also be a burden for senior employees to have to keep using spare moments in their day to provide education to these hires at every step. To help tackle this issue, the KINTO development group believes that holding specially designed orientation training can really help eliminate the anxiety and confusion felt by mid-career hires and thus have a positive impact on their subsequent ability to perform their duties. In order for mid-career hires to settle into the company as quickly as possible, we have designed and implemented orientation training aimed at achieving the following three goals: To deepen understanding of KINTO services To ensure awareness of their specific role and company values To develop a fondness in the hires for the working environment and workplace Four-Stage Approach to Creating Orientation Training I would now like to talk about the four stages of orientation training that we have held thus far. Each session lasts around 60 minutes, with a senior employee taking the role of lecturer. Introduction to Product Team (Welcome to the KINTO development group!) In this orientation training, we talk about which teams within the group do which types of work, using a correlation chart with the faces of employees for reference. We hear from a lot of people that they feel uneasy when they first enter the workplace after joining the company because they cannot match people's faces with their names. This is the first type of orientation we do. By letting the new-hires know who is who in the team and who the product members are, they are better prepared to know who to ask if they are unsure about anything in their work duties. Description of services and work-duties (Hands-on experience of the service flow!) This type of orientation involves experiencing the flow of KINTO ONE's services through hands-on learning with example scenarios. By role-playing various types of people the new-hires may encounter as part of their duties and having them operate the online display accordingly, they can get to know the various stakeholders they will encounter in their work duties in future. Also, by using diagrams to introduce stakeholders and other matters like terminology, even those people not directly involved in the automobile industry can gain a deeper understanding. Overview description of system (Understanding the systems and technologies the group uses) In this type of orientation training, we take a bird's eye view of what goes on behind the scenes of the system our group uses. By introducing the new-hires at this early stage to the structural elements, functions, and interactions of the system in its entirety, we believe it is possible to clarify in the new-hires their own responsibilities and areas of specialization, thereby facilitating their introduction to the project. We also run a Q&A regarding the tech stack during this orientation stage. Welcome lunch (Get to know senior employees and the company culture) This is actually the most important stage of the orientation in my view. By allowing the new-hires to speak openly with other senior employees, they are able to get a real sense of the atmosphere within the company. The goal of this stage of the orientation is to drop the formal content for a while and to make the new-hires feel at home within the group. The company has a number of foodies who love to share information on good lunch spots around the office using the Slack channel 😋 (Expect the conversation to get pretty lively if a place with tatami or a sunken kotatsu is chosen! Haha!) What we have learned from implementing orientation training The monthly orientations help us improve knowledge and uncover issues people are facing. No fixed structure to orientation training Just like with normal development work, orientation training needs to be designed and implemented. Because the mid-career hires are often of different backgrounds and ages, we need to break down, explain, and discuss the content together with the members. In order to help those hires who are not particularly familiar with automobiles gain a greater understanding of the content, we use charts featuring the various stakeholders involved in the service provision as part of our explanations and ask questions back to the hires to help ensure they have not misunderstood the explanations. Once the entire orientation is complete, we ask the new-hires to answer a questionnaire used to measure their degree of understanding of the content and of its effectiveness. This knowledge is then utilized to provide better orientation training in future. One of the most interesting things about the orientation is that it can be customized each month. Improving connections between new-hires I think that those mid-career hires who feel a little uneasy just after joining the company can find support in other members who joined at the same time as them. Because new members go through the training and hands-on experiences together, you often also see them going through the same process of trial and error together in their actual duties. For that reason, we created a Slack channel for use by new hires and the persons running the orientation training as part of efforts to facilitate communication with their fellow new-hires in a way that is approachable. We actually hear from a lot of these hires that they find it easier to express themselves in smaller groups than in Slack channels with lots of other people in it. Allowing the orientation training to be an opportunity to improve the relationships between new-hires is one of the greatest rewards of hosting such training. Improving understanding of the work of senior employees (persons in charge) Orientation comprises lecture type sessions hosted by senior employees. When we are preparing documents for the orientation, we invite feedback from people in other groups and do some hand-on work ourselves to try and uncover any elements we might have been unaware of previously. For that reason, it is necessary to periodically update the documents. People have a tendency to think that orientation training is only for new-hires, but it is also something that can be very meaningful for senior employees. To this end, we also share the aforementioned questionnaires with the senior employees. Summary The most worthwhile effect of orientation training in an organization for engineers is to get rid of any feelings of anxiety in new members and to increase knowledge of their duties in a short and concentrated period. This hopefully will then enable them to begin contributing to the project as early as possible and begin providing value to users. Mid-career hires tend not to have many opportunities to receive detailed guidance. The tendency is for them to look things up for themselves if they don't understand something. Obviously, learning for yourself how to resolve a problem is best, but I think that by creating a system to support new-hires, we will be able to build a team in which communication is smooth and encouraged. Moving forward, I would like to continue to update the orientation training using questionnaires and other tools such that we can better support mid-career hires. Also, by having a large number of group members involved in the orientation, I believe we can create a more multi-faceted form of communication and higher quality and more customized types of training. I would love to hear from others about the types of interesting orientation training sessions going on in their companies.
はじめに こんにちは、KINTOテクノロジーズの森野です。2023/6/29(木)~30日(金)に、同僚と二人で愛媛県松山市で開催されたサイバーセキュリティシンポジウム道後2023に参加してきました。開催趣旨は、コロナウイルスと共存する社会の進展に伴い、デジタル化が加速する中で、サイバー攻撃への対策が重要になっていることを認識し、「地域SECUNITYの力でサイバー攻撃と戦う」をテーマに、政策動向や技術動向、攻撃事例などについて議論を深めることを目的としたものです。私たちは、講演や他の参加者から多くの刺激や学びを得ることができました。 松山空港に到着すると、愛媛県のイメージアップキャラクターであるみきゃんがお出迎えしてくれました。みかんジュースタワーやみかんジュースの出る蛇口もありました。 シンポジウムでは、多くの興味深い講演や発表がありましたが、私が印象に残ったものをいくつかご紹介したいと思います。(講演や発表の一覧は こちら からご確認ください。) 我が国のサイバーセキュリティ政策 まず、基調講演では、山内智生氏(総務省サイバーセキュリティ統括官室サイバーセキュリティ統括官)が「我が国のサイバーセキュリティ政策」について講演されました。山内氏は、「誰も取り残さない」というテーマのもと、自由、公正かつ安全なサイバー空間の確保につながる国としての取り組みを説明され、重要インフラのサイバーセキュリティに係る行動計画の改定や、サイバーセキュリティ月間のターゲットの変更、政府機関におけるクラウド利用の改善などを紹介されました。「誰も取り残さない」というテーマが非常に素晴らしいなと感じました。 セキュニティ(セキュリティ+コミュニティ)、そして生成AI 次に、ナイトセッションですが、私は濱本常義氏(株式会社エネルギア・コミュニケーションズ ITインテグレーション部)とまっちゃだいふく氏(株式会社ラック テクノロジーリスクコンサルティング部)のお二人による「セキュニティ(セキュリティ+コミュニティ)、そして生成AI」の講演を拝聴しました。濱本氏は、セキュリティとコミュニティを組み合わせた造語であるセキュニティについて説明しました。セキュニティとは、セキュリティに関心を持つ人々がオンラインやオフラインで交流し、知識や経験を共有し、協力し、学び合うことで、セキュリティの向上に貢献するコミュニティのことだと理解しました。続いて、生成AIに関する知見を共有して頂きました。発表資料は こちら から参照可能です。セキュリティの観点ではログから不審なアクテビティを検出するなどの活用に期待を持った一方、巧妙なフィッシングメールの生成等への悪用を懸念しました。 学生研究賞受賞研究発表会 最後に、二日目の学生研究賞受賞研究発表会では、優秀な学生達が自分の研究成果を発表しました。シンポジウムの参加者が、最も良いと感じた発表に投票する仕組みで、私は、「TRPGを参考とした個人向けサイバー演習のKPレス手法の提案」という発表に投票しました。この発表は、藤本恵莉華さん(長崎県立大学大学院 地域創生研究科)が行ったもので、個人向けのサイバー演習シナリオとして、TRPG(テーブルトークロールプレイングゲーム)を参考にしたKPレス(キーパーレス)の演習手法を提案されていました。キーパーレスとは、TRPGでゲームマスターの役割を担う人がいない状態のことを指します。セキュリティ担当者として従業員の情報セキュリティ教育について日ごろから関心があるため興味を引かれました。年代がばれてしまいますが、私が小学生高学年から中学生の頃、 ゲームブック が非常に流行りました。その手法を取り入れた演習だと理解しました。 まとめ 以上が、サイバーセキュリティシンポジウム道後2023の講演や発表の一部です。他にも多くの有益な講演や発表がありました。このシンポジウムは、サイバーセキュリティに関する最新の知見を学ぶだけでなく、同じ分野に興味や関心を持つ人々と交流することができる貴重な機会でした。主催者やスポンサー、参加者の皆さんに感謝します。
Introduction I'm Chris, Front End Engineer for KINTO Technologies. I am part of the Global Development Division and, as is usual for an multinational team, we communicate primarily in English, whether for casual chats or for technical conversations. My team develops interfaces for local services and back-office systems for various countries. When developing multiple projects at the same time, improving the efficiency of the development work is crucial. Today I would like to talk about the front-end perspective. Problems to Solve KINTO services have already been deployed in more than 20 countries worldwide and while business structures, development systems and business practices differ from country to country, one of the challenges we face is achieving consistent UI/UX on a global scale. To solve this problem, we are developing a design system specifically for KINTO services, which is the background to this article. Since implementing a design usually involves front-end development of HTML/CSS/JS, communication between designers and engineers is essential to ensuring work proceeds smoothly. If multiple designers work on a design without coordination, the style of the design will end up disjointed and developers may need to create unique components for each project. Having many projects in this state presents three major disadvantages for a company. Because each project requires its own development work, costs increase dramatically in proportion to the number of uncoordinated projects If future designs or the person in charge of development changes, the style and the design approach may also change, making maintenance difficult Even for users who aren't aware of the internal development process, uncoordinated design can result in an inconsistent experience and make using the product stressful Approaches An Easy Way for Designers and Engineers to Review Designs One way that designers can tackle the issue mentioned above is to prepare design guidelines that define the approach for the various components and to design UI/UX with these guidelines in mind. However, simply looking at guidelines for things such as color, font or prohibited items will not directly reduce the development time, so it is also important to think about what engineers can do. On the development side, one approach is developing components in cooperation with the designers that can be reused anywhere and insert them into every project. As a first step, I thought it would be beneficial to have somewhere to review these components all in one place, so I would like to introduce the "Storybook" tool. Developing Components Using Storybook Storybook is an open-source tool for developing and documenting components individually. Using this tool makes it possible to see at a glance which components can be reused. There are installation guides for each JS framework on the official site, but since the Global Development Team uses Vue.js, we followed this guide to set up the environment. Developing and Managing Components as Story Units One feature of Storybook is the grouping of similar components as a unit called a "Story." For example, a component that we call a "button" may be used in a variety of different ways on a website (a primary button that prompts user action, a secondary button used for other purposes, a smaller button that is used for only limited purposes, a long button etc.). These various buttons can be grouped together using a file called xxxx.stories.ts . (If you prefer to use JavaScript, use xxxx.stories.js .) In addition, when actually using a component, Props may be passed on. Accordingly, you can use a feature known as "Controls" to pass on all kinds of Props. For buttons, for instance, we set the "disabled" attribute to prevent them from being clicked, but if we add the corresponding Control to the Story file, the value in the UI changes and we can check to see how the component changes. Documenting Components If you follow the guide on the official site to install Storybook, the @storybook/addon-essentials library is included automatically. As its name suggests, this is a library that contains add-ons that you might need. One of these add-ons is @storybook/addon-docs , which gives each Story its own documentation. After clicking on each Story, the Docs tab should appear in the UI. Storybook automatically creates documentation using information taken from pre-written Story files, but if you would like to create your own documentation, you can set a file created from the Story file as a parameter and this will be reflected in the documentation (in the example below, a markdown file has been set as the parameter). import ButtonDocument from '@/docs/ButtonDoc.mdx' export default { title: 'Components/Buttons', parameters: { docs: { page: ButtonDocument, }, }, } Adjusting the Storybook UI to Reflect Company Identity Although using Storybook to render lots of reusable components and documentation is helpful, if all sites looked like they used Storybook design, it would be difficult to get a sense of a company's identity — so we set to work on the layout as a whole. Specifically, we replaced the logo with our company's logo and fonts, then adjusted font size and colors. As is the case for implementing documentation, @storybook/theming must also be installed to make these changes. Since this is included in @storybook/addon-essentials , you can start by creating a manager.js file in the .storybook directory and specifying a specific theme. For reference, our company uses the following settings. import { addons } from '@storybook/addons' import { create } from '@storybook/theming' addons.setConfig({ theme: create({ // This is a base setting included in Storybook: you can pick between "light" and "dark" base: 'light', brandTitle: 'XXXX XXXX', brandUrl: 'xxxxxxxxxxxx', brandImage: 'Image path', brandTarget: '_blank', appBorderRadius: 10, textColor: '#2C353B', textInverseColor: '#FFFFFF', barTextColor: '#2C353B', barSelectedColor: '#00708D', }) }) The company's identity is much clearer now, but there are further adjustments that can be made to customize the appearance of our site by using CSS directly. If you create a file called manager-head.html in the .storybook directory mentioned earlier, CSS code written in this file will be reflected in the Storybook UI (you will need to restart the development environment). As an example, below is the UI after adjusting it for our company. You can now render commonly used components such as buttons and a variety of input methods. Afterwards, you can prepare an environment that coworkers can view, allowing involved parties to review it. Next Steps Using Storybook, we developed each component and made them available for designers and developers around the world to use as reference. But this measure is just the first step. We are already working on various things in-house, but we have listed a few below that we would like to be able to do in the future. Publish Case Studies Using Multiple Components Together Rather Than Individual Components There are templates available that use multiple components together. For example, a log-in form is composed of an email address and password field, a checkbox for remembering log-in status and a "Login" button. However, being able to review these components together in Storybook would help development proceed much faster. In the future, we would also like to be able to review page units. Publish Component Libraries If there are components that you want to include in your own projects, for example, you currently need to copy the required source code from the Storybook repository. In addition to the possibility of copy errors, if you want to change component specifications in the future, you would need to modify the source code of every project that has already been completed. By writing private libraries and installing them in every project, components can be easily reused. The benefit of this approach is that when new components are completed or the specifications of existing components are changed, these changes can be reflected simply by updating the version using a package manager (of course, this does require thorough enforcement of a version management process). Final Thoughts about Storybook The introduction of this tool is just one step towards the development of a universal design system, but many of the benefits of using Storybook in the development process were apparent the very first time we used it. Developing components individually makes it possible to separate them from dynamic elements and focus on adjusting their appearance Using Stories makes it possible to reproduce actual use cases The person in charge of each project can use this tool as a reference when developing interfaces We hope to continue introducing Storybook throughout the company to promote efficient interface development.
Hello, this is Awache ( @_awache ), a Database Reliability Engineer (DBRE) at KINTO Technologies (KTC). In this blog post, I would like to talk about the Database guardrail concept that I want to implement at KTC. What are guardrails? "Guardrails" is a term that is often used in Cloud Center of Excellence (CCoE) activities. In a nutshell, guardrails are "solutions for restricting or detecting only realms that are off-limits, while ensuring as much user freedom as possible." Based on the characteristics of the role of dealing with the realms of a database, where governance must be emphasized, DB engineers sometimes act as "gatekeepers" which hinders the agility of corporate activities. Therefore, I am thinking about incorporating this "guardrail" concept into DBRE's activities to achieve both agility and governance controls. Types of guardrails Guardrails can be categorized into the three types below. Category Role Overview Preventive Guardrails Restrictive Applies controls that render the operations in question impossible Detective Guardrails Detective Mechanisms that discover and detect when an unwanted operation is carried out Corrective Guardrails Corrective A mechanism that automatically makes corrections when unwanted settings are configured Preventive guardrails  Detective guardrails  Corrective guardrails  The guardrail concept Applying strong restrictions using preventive guardrails starting from the initial introductory stages may lead to opposition and fatigue among on-site engineers because they will be unable to do what they have previously been able to do, as well as what they want to do. Conversely, I think that if automatic repairs are performed using corrective guardrails, we may lose opportunities to improve engineers' skills in considering what settings were inappropriate and how to fix them. That is why I believe that we are now in the phase of consolidating the foundations for ensuring as much freedom as possible for users and implementing governance controls. On top of that, I think it is preferable to introduce "detective guardrails." Currently at KTC, we have introduced a 3-stage DEV/STG/PROD system, so even if the risk detection cycle is shifted to a daily basis using detective guardrails, in many cases they will be recognized before being applied to production. Inappropriate settings are periodically detected by detective guardrails, and the on-site engineers who receive them correct and apply them. If continuously repeating this cycle leads to a rise in service levels, the value of this mechanism will also go up. Of course, we do not stop at providing detective guardrails; it is also important to keep updating the rules that are detected there according to the situation on the ground. We need to further develop this mechanism itself together with KTC by working with on-site engineers to provide guardrails that match the actual situation at KTC. Strong backing by executive sponsors If we do not make headway with the idea of "responding to things detected by guardrails according to the error level," we will only increase the number of false alarms. I also consider it an anti-pattern to allow for this rule to not correspond to the circumstances of individual services. Therefore, the important thing should be "to incorporate only the rules that should be observed at a minimum as long as we provide services as KTC." This mechanism is pointless if we cannot spread the word and get all of KTC's engineers to collectively understand this single point: if an alert is raised by a guardrail, we will respond according to the error level without defining overly detailed rules. Therefore, the person pushing this forward for us is our executive sponsor, who is supporting our activities. It is desirable that the executive sponsor be someone with a role that sets the direction of the company, such as someone at the management level or a CXO. At first, no matter how careful we were, the essential point of enforcing rules on on-site engineers would not change. So the fact that company management has committed to this activity via the executive sponsor should act as one of the reasons and motivations for them to cooperate. Demarcation points for responsibilities As a cross-organizational organization, KTC's DBRE does not operate the service directly. Therefore, it is necessary to clarify where the DBRE's responsibilities begin and end and where the on-site engineers' responsibilities begin and end. I have thought about using a framework called DMAIC for this. Regarding DMAIC, I think that it is laid out in a very easy-to-understand way in this video— "What is DMAIC: Define, Measure, Analyze, Improve, Control. Winning patterns for business flow improvement projects (Lean Six Sigma)" —so please take a look. Below is a rough description of who is responsible for what and what should be done, in terms of this 5-step procedure. Definition Description Operation Final Responsibility Define Define the scope and content of what to measure/evaluate Documentation Scripting DBRE Measure Performing measurements/evaluations and collecting the results Running scripts DBRE Analyze Analyzing/reporting results Increasing visibility of the entire organization DBRE Improve Improving flaws/drafting improvement plans Implementing smooth solutions to problems Product Control Checking outcomes and aiming to control them Maintaining a healthy state as a service Product  While this diagram clarifies each role, it also shows who holds final responsibility while people work with each other in consultations and improvements in all of these steps. For example, I would like to add that this does not mean that DBRE does not in any way support efforts geared toward on-site improvements and controls. How to construct guardrails So far, I have described the concept at length up to the construction of guardrails, but from here on I will illustrate specific efforts. [Define] Defining error levels Defining the error level first is the most important thing. The error level is the value that this guardrail provides to KTC. No matter how much the DBRE thinks something "must" be done, if it does not meet the defined error level, it will be relegated to a Notice or be out of scope. I can be accountable to the on-site engineers by personally ensuring that the rules that have been set are checked against their definitions, and I can control my desire to "mark everything as critical." I have set the specific definitions as follows. Level Definition Response speed Critical Things that may directly lead to security incidents Critical anomalies that go unnoticed Immediate response Error Incidents related to service reliability or security may occur Problems in the database design that may have negative impacts within about 1 year Response implemented within 2 to 3 business days Warning Issues that, by themselves, do not directly lead to service reliability or security incidents Issues that include security risks but have limited impact Problems in the database design that may have negative impacts within about 2 years Implement planned response Notice Things that operate normally but are important to take note of Respond as needed [Define] Specific content arrangement Next, we will consider creating guidelines among the defined rules, but if we try to look at the entire database from the outset, we will fail. Therefore, in the first step, I have set the scope of the guardrail as "the extent to which that one can generally handle things on one's own." "The extent to which that one can generally handle things on one's own" means the extent to which things can be done without deep domain knowledge of the service currently running, such as setting up a database cluster (KTC uses Amazon Aurora MySQL for the main DB), configuring DB connection users, and setting schema, table, and column definitions. On the other hand, the areas without intervention by guardrails at this stage are schema design, data structure, and Queries, etc. In particular, the point here is that "workarounds when a Slow Query occurs" is not set as a guardrail. Slow Query can be a very important metric, but it is difficult to address without deep service-level domain knowledge. If a large number of them occur at this stage, it is difficult to know where to start and how to continue to address them reliably and in a timely fashion according to the error level. Regarding Slow Queries, I would like to think step by step, by visualizing Slow Queries so as to enable anyone to check the situation, then defining the SLO as the one to address them, and try out individual proposals from the DBRE. Image of realms checked using guardrails  [Define] Setting guidelines/implementing scripting After deciding upon the defined error levels and the range of interventions, I will apply them to the guidelines. Thus, I can automatically detect what has been agreed upon. Here are some of the guidelines I created. Item to check Error Level Reason Setting database backups is effective If backups are not set, it will result in an Error Backups are an effective measure against the risk of data loss due to natural disasters, system failures, or external attacks The backup retention period is long enough If the backup retention period is less than 7, it will result in a Notice . A certain period of time is needed to recover from a serious loss. There is no general definition of how much time is enough. Therefore, I have set the defaults for AWS's automatic snapshot feature. Audit Log output is valid If the Audit Log settings have not been configured, it will result in Critical status Leaving a log in the Database of who did something, what was done, and when it was done will enable a proper response to data losses and data leaks Slow Query Log output is valid If Slow Query settings are not configured, it will result in Critical status If the Slow Query settings are not valid, it may not be possible to identify Queries that cause service disruptions There is no object that uses utf8(utf8mb3) as the character set for Schema, Table and Column content If there is no object that uses utf8(utf8mb3) as the character set for Schema, Table and Column content, it will result in a Warning There will be strings that cannot be stored in utf8(utf8mb3) It is also mentioned that they will be excluded from MySQL support in the near future. There are Primary Keys in all tables If tables without Primary Keys are used, it will result in a Warning Primary Keys are necessary for uniquely identifying what the main body of that scheme is for and structurally identifying the records There are no Schema, Table or Column names consisting only of strings that are reserved words. If there is a name composed only of reserved words, it will result in a Warning We are planning to render names consisting only of reserved words as unusable in the future or to require that they must always be enclosed in backquotes (`). See 9.3 Keywords and Reserved Words for a list of reserved words These are within the range that can be acquired from information from AWS's API and Information Schema (some mysql Schema and Performance Schema).  Script this information after acquiring it. For example, if you want to check if "there is no object that uses utf8(utf8mb3) as the character set for Schema, Table and Column content," you can obtain that information by executing the following query. SELECT SCHEMA_NAME, CONCAT('schema''s default character set: ', DEFAULT_CHARACTER_SET_NAME) FROM information_schema.SCHEMATA WHERE SCHEMA_NAME NOT IN ('information_schema', 'mysql', 'performance_schema', 'sys', 'tmp') AND DEFAULT_CHARACTER_SET_NAME in ('utf8', 'utf8mb3') UNION SELECT CONCAT(TABLE_SCHEMA, ".", TABLE_NAME, ".", COLUMN_NAME), CONCAT('column''s default character set: ', CHARACTER_SET_NAME) as WARNING FROM information_schema.COLUMNS WHERE TABLE_SCHEMA NOT IN ('information_schema', 'mysql', 'performance_schema', 'sys', 'tmp') AND CHARACTER_SET_NAME in ('utf8', 'utf8mb3') ; Other steps (Measure/Analyze/Improve/Control) I will build a platform that periodically executes a scripted information acquisition query to meet the guidelines, such as the above query, and sends an alert if the result is determined to be inappropriate, which functions as a guardrail. Then I think that, for the time being, my activities as DBRE will be centered on returning to this cycle of preparing a dashboard to increase the visibility of the obtained results and having engineers on site respond. The good thing about this guardrail mechanism is, for example, when it becomes necessary within KTC to set a rule that "among the Slow Queries that take 1 second or more, the percentage of queries from the front-end will go from 99 percent per month to 0 percent," if that rule is added, it alone can be applied to all services managed by KTC. Conversely, it is also possible to remove unnecessary rules all at once. This is my concept of scalable database guardrails. Summary What do you think? In this blog post, I introduced the DBRE guardrails, which I consider as one axis around which we can perform scaling as KTC's DBRE and create a continuous value provision. Although it is still in the construction stage, it does not use database technology as has been done up to now, and we are on the verge of creating a DBRE organization that takes into consideration how to apply this technology effectively at KTC and even how to link it to our business values. In that sense, we are now in a challenging time, and we are expending into a wide range of things, from application engineering to cloud engineering. We want to build up these things step by step and continue to output them to everyone, so please continue to support us! Also, if you are interested in this activity or would like to hear more about it, please feel free to contact me via Twitter DM .
Introduction I am Aoi Nakanishi , lead engineer of KINTO FACTORY at KINTO Technologies. The KINTO FACTORY project is redesigning the system with a view to service growth of supported vehicle models and products, as well as nationwide expansion. This project also incorporates with modern technologies and development workflows. In this article, I will describe the schema-first development we are working on at KINTO FACTORY. What is schema-first development? This method, which involves defining a schema file, generating code using a code generator, and developing an API, solves the following problems. When trying to combine, it doesn't work due to type difference. The documents are outdated and the code is correct. Client implementation is duplicated for each language. 1. When trying to combine, it doesn't work due to type difference. Since the schema is defined as an interface with the front end, back end, various microservices and external services, etc., discrepancies in data structures are less likely to occur. 2. The documents are outdated and the code is correct. By using a generator to output documents, it is possible to avoid situations where the contents of the documents and the code tend to diverge as operations continue. 3. Client implementation is duplicated for each language. Code is automatically generated from the defined schema file regardless of the development language the client is using on the web app or mobile app, etc., so it is possible to avoid unnecessary development work when implementing the same function in different languages, for example. Other Many people feel that the barrier to implementation is high if there is no one in the team with experience doing so. However, schema-first development provides a range of benefits for developers such as value validation, automatic code generation for mock servers, git version control, etc. KINTO FACTORY system configuration KINTO FACTORY uses the microservice architecture shown below. GraphQL from browser REST API from third-party system gRPC (Protocol Buffers) between each microservice These are the kinds of configurations it uses to communicate. Interface Description Language (IDL) In general, each API design is defined using the following IDL (Interface Description Language). Interface IDL GraphQL GraphQL Schema https://graphql.org/learn/schema/ REST API Swagger Spec https://swagger.io/specification/ gRPC Protocol Buffers https://developers.google.com/protocol-buffers Learning multiple IDLs is expensive and inefficient. Schema conversion tools I thought, if each IDL can define names and types and generate code, surely we can convert between schemas? I looked into it and summarized the findings in the table below. Before conversion/After conversion GraphQL Schema Swagger Spec Protocol Buffers GraphQL Schema - ? ? Swagger Spec openapi-to-graphql - openapi2proto Protocol Buffers go-proto-gql protoc-gen-openapiv2 - There is not much information on tools that convert based on GraphQL Schema. Tools to convert based on Swagger Spec have not been maintained for a long time. Tools to convert based on Protocol Buffers have more options and information than the ones mentioned above. Based on the above findings, we chose to define using Protocol Buffers and convert to another Schema. Source file (.proto) Preparation 1 Get the files necessary to define the Rest API from https://github.com/googleapis/googleapis google/api/annotations.proto google/api/http.proto google/api/httpbody.proto Preparation 2 Get the proto definition file required to define the GraphQL Schema from https://github.com/danielvladco/go-proto-gql protobuf/graphql.proto Definition file (example.proto) The following definition file was created for this article using an article from the Tech Blog as an example. syntax = "proto3"; package com.kinto_technologies.blog; option go_package = "blog.kinto-technologies.com"; import "google/api/annotations.proto"; // Load file acquired in Preparation 1 import "protobuf/graphql.proto"; // Import file acquired in Preparation 2 // Article message Article { // Title string title = 1; // Author string author = 2; // Content string content = 3; } // Request message Request { uint64 id = 1; } // Result message Result { uint64 id = 1; } // Tech Blog Service service TechBlog { // Post Article rpc PostArticle(Article) returns (Result) { option (google.api.http) = { post: "/post" }; option (danielvladco.protobuf.graphql.rpc) = { type: MUTATION }; } // Get Article rpc GetArticle(Request) returns (Article) { option (google.api.http) = { get: "/get/{id}" }; option (danielvladco.protobuf.graphql.rpc) = { type: QUERY }; } } Convert .from proto to .graphql Install go-proto-gql Clone repository git clone https://github.com/danielvladco/go-proto-gql.git cd go-proto-gql Install Protoc plugins cd ./protoc-gen-gql go install Convert from .proto to .graphql protoc --gql_out=paths=source_relative:. -I=. example.proto Output file (.graphql) """ Tech Blog Service """ directive @TechBlog on FIELD_DEFINITION """ Article """ type Article { """ Title """ title: String """ Author """ author: String """ Content """ content: String } """ Article """ input ArticleInput { """ Title """ title: String """ Author """ author: String """ Content """ content: String } type Mutation { """ Post Article """ techBlogPostArticle(in: ArticleInput): Result } type Query { """ Get Article """ techBlogGetArticle(in: RequestInput): Article } """ Request """ input RequestInput { id: Int } """ Result """ type Result { id: Int } Convert from .proto to .swagger.json Install protobuf brew install protobuf Install protocol-gen-openapiv2 go install github.com/grpc-ecosystem/grpc-gateway/v2/protoc-gen-openapiv2@latest Convert from .proto to .swagger.json protoc -I . --openapiv2_out=allow_merge=true,merge_file_name=./example:. example.proto Output file (.swagger.json) { "swagger":"2.0", "info":{ "title":"example.proto", "version":"version not set" }, "tags":[ { "name":"TechBlog" } ], "consumes":[ "application/json" ], "produces":[ "application/json" ], "paths":{ "/get/{id}":{ "get":{ "summary":"Get Article", "operationId":"TechBlog_GetArticle", "responses":{ "200":{ "description":"A successful response.", "schema":{ "$ref":"#/definitions/blogArticle" } }, "default":{ "description":"An unexpected error response.", "schema":{ "$ref":"#/definitions/rpcStatus" } } }, "parameters":[ { "name":"id", "in":"path", "required":true, "type":"string", "format":"uint64" } ], "tags":[ "TechBlog" ] } }, "/post":{ "post":{ "summary":"Post Article", "operationId":"TechBlog_PostArticle", "responses":{ "200":{ "description":"A successful response.", "schema":{ "$ref":"#/definitions/blogResult" } }, "default":{ "description":"An unexpected error response.", "schema":{ "$ref":"#/definitions/rpcStatus" } } }, "parameters":[ { "name":"title", "description":"Title", "in":"query", "required":false, "type":"string" }, { "name":"author", "description":"Author", "in":"query", "required":false, "type":"string" }, { "name":"content", "description":"Content", "in":"query", "required":false, "type":"string" } ], "tags":[ "TechBlog" ] } } }, "definitions":{ "blogArticle":{ "type":"object", "properties":{ "title":{ "type":"string", "title":"Title" }, "Author":{ "type":"string", "title":"Author" }, "content":{ "type":"string", "title":"Content" } }, "title":"Article" }, "blogResult":{ "type":"object", "properties":{ "id":{ "type":"string", "format":"uint64" } }, "title":"Result" }, "protobufAny":{ "type":"object", "properties":{ "@type":{ "type":"string" } }, "additionalProperties":{ } }, "rpcStatus":{ "type":"object", "properties":{ "code":{ "type":"integer", "format":"int32" }, "message":{ "type":"string" }, "details":{ "type":"array", "items":{ "$ref":"#/definitions/protobufAny" } } } } } } Summary In this article we introduced schema-first development and tools for converting schema definitions as a way of minimizing multiple schema definitions. We hope that it will be helpful for those who want to resolve the confusion of multiple definition languages, especially those who are considering converting Protocol Buffers definitions to GraphQL Schema and Swagger Spec. I hope to publish other articles on document generation, automatic generation of validation processing and automatic code generation, etc. Follow us! KINTO Technologies is now on Twitter. Please follow us to keep up with the latest information. https://twitter.com/KintoTech_Dev We are hiring! KINTO Technologies is looking for people to work with us to create the future of mobility together. We also conduct informal interviews, so please feel free to contact us if you are interested. https://www.kinto-technologies.com/recruit/
Introductory Remarks and Self-Introduction My name is Ikeda, and I'm in charge of front-end development at KINTO Technologies. Recently, I've been involved in the development and operation of KINTO ONE and the launch of new services and projects. Introductory Remarks Recently, various JS frameworks are emerging, such as React, Vue.js, AngularJS, Preact and Ember. Svelte and Solid are two that have been gaining momentum lately. (And personally, I would like to see Mithril.js grow more. You can find more information about it here: https://mithril.js.org ). With this in mind, I would like to introduce the KINTO corporate site, the KINTO Technologies corporate site, and my impressions of using Svelte —which is also used in other ongoing products— and some code, including a simple SSG. What is the SSG (static site generator) introduced in this article? From a front-end perspective, a request is run every time you access an element, such as API GET to obtain, say, a list of blog articles and then API GET to view an article in detail. What an SSG (static site generator) does is basically create all the relevant API GET content during the build process. As an advantage, in the above example, API communication does not occur when transitioning from the blog list screen to the detailed screen, so the transition is very smooth. There are various other architectures, such as SPA, ISR, and SSR. What is Svelte? Svelte is a framework with an extremely small build size, and as I'll explain later, reading and writing is extremely easy. Also, JS frameworks are nearly equal to virtual DOM, but Svelte does not include a virtual DOM because things like changes to DOM are also described in Vanilla JS during compiling. It doesn't build a virtual DOM or anything else needed for re-rendering; it simply replaces the real DOM when the state of the DOM changes. Please see below for more details: JS framework is based on the concept of write less code https://svelte.jp/blog/write-less-code Product Introduction KINTO Corporate Site https://corp.kinto-jp.com/ KINTO's corporate site is created in a SvelteKit (SSG) on [S3 + CloudFront] configuration. After coding, when it is merged into a certain branch, the build task is executed via GitHub Actions, reflected in S3, and distributed with CloudFront. *SvelteKit is an application framework that uses Svelte. It's similar to Next.js using React. See here for details: https://kit.svelte.dev/ KINTO Technologies Corporate Site https://www.kinto-technologies.com/ KINTO Technologies corporate site uses Svelte (SPA) on [S3 + CloudFront]. While KINTO's corporate site uses the SSG method, KINTO Technologies' corporate site uses the SPA method. This corporate site did not have much content at the stage when the repository was set up, plus the SvelteKit beta version had not yet been released, so Svelte (SPA) was adopted. However, the amount of content is increasing, which begs the question of whether SG is really enough. With that in mind, we're now eagerly awaiting the change to SvelteKit. What Makes Svelte Different The biggest difference isn't the library, it's the compiler . Whether it's Vue or React, the size of a library file will take up the build size as it is, so build size will inevitably increase. This is a perfect framework for me, because as far as I'm concerned, fast loading speed = justice . And of course, there are plenty of devices and plug-ins that can be used to improve the loading speed and execution speed of other frameworks as well. Where I Got Stuck When Actually Implementing It There were really very few places where I got stuck. A simple increment can be written in a small number of lines, like this: <script> // define cout let count = 0; // onclickで使用する関数 function handleClick() { count += 1; } </script> <button on:click={handleClick}> Clicked {count} {count === 1 ? 'time' : 'times'} </button> If there's anything, it's because this is only a beta version and there are still destructive changes being made, so it's necessary to pick up information each time this happens. Svelte's unique syntax is easy to understand, so I think it's difficult to get stuck even if you're seeing it for the first time. There's also another unique syntax called Await blocks . Take a look at the component that fetches each time you click below. You can write 'await' as is in HTML, and reading is a cinch. <script> let promise = getRandomNumber(); async function getRandomNumber() { const URL = "xxx" const res = await fetch(URL); const text = await res.text(); if (res.ok) { return text; } else { throw new Error(text); } } function handleClick() { promise = getRandomNumber(); } </script> {#await promise} <p>...waiting</p> {:then data} <p>{data}</p> {:catch error} <p style="color: red">{error.message}</p> {/await} For readers who think, "Is it really that easy? I'm not convinced." Don't knock it until you've tried it. Why not give it a try for yourself? Try It Out! Practice https://kit.svelte.jp/ We'll reference the SvelteKit official site while we make it. First, let's make a SvelteKit project in the appropriate directory: sh:terminal npm init svelte static-site-sveltekit Next, you'll be given a choice, so select Skeleton project and any other options as you wish. It's convenient that there's a CLI. When selecting, it should generally look something like this: The following is adopted in this article: eslint + JavaScript with JSDoc comments + prettier + Playwright Generating a Static Site This time, I'm going to try the so-called Jamstack, so I'd like to include some sort of communication. I'll try to obtain an article about Svelte from dev.to . *This article does not cover styling, as it increases the volume. First, let's make the page with the list of articles. <script context="module"> export async function load() { let articles try { articles = await fetch(`https://dev.to/api/articles?tag=svelte&per_page=5&page=1`); articles = await articles.json(); console.log(articles) } catch (e) { console.log(e) } return { props: { articles } } } </script> <script> export let articles const PostArticles = articles </script> <svelte:head> <title>Blog</title> </svelte:head> <div> <h1>Svelte devto Articles</h1> {#each PostArticles as article} <div> <header> <h2>{article.title}</h2> <h4>Tags: {article.tags}</h4> </header> <p> {article.description} </p> <a href={`/blog/${article.id}`}>MORE</a> </div> {/each} {#if PostArticles.length === 0} <div>No Articles</div> {/if} </div> With async await , you can obtain the article by fetching the dev.to API, storing it in articles, assigning it to PostArticles and rendering it with Svelte's 'each' syntax. You can export what is written using context="module" . In other words, it can be called even within the same component. Then pass it to the DOM in the next script section and parse it. It's very clear. The good thing about Svelte is that the sections are clear, so it's easy for the writer and very simple to follow. People say that Vue is easy and React is simple , but I think Svelte is both easy and simple . I digress, but let's make a detailed article next. <script context="module"> export async function load({ fetch, params }) { let article try { article = await fetch(`https://dev.to/api/articles/${params.slug}`); article = await article.json(); console.log(article) } catch (e) { console.log(e) } return { props: { article } } } </script> <script> export let article const post = article </script> <svelte:head> <title>{article.title}</title> </svelte:head> <div> <div> <h1>{post.title}</h1> <section> {@html post.body_html} </section> </div> </div> That's it. Params contains various kinds of information, so you just need to get that information, pass it and render it. That's all there is to it. Let's Build! I've written most of the code. So finally, let's build. As it is, there's no instruction to static generate inside svete.config.js . https://kit.svelte.jp/docs/adapters As mentioned in the above, let's use @sveltejs/adapter-static . Let's start by installing it. sh:terminal yarn add @sveltejs/adapter-static@next -D Next, rewrite svelte.config.js. import adapter from '@sveltejs/adapter-static'; /** @type {import('@sveltejs/kit').Config} */ const config = { kit: If { // prerender is not entered, an error will occur prerender: { default: true }, adapter: adapter({ pages: 'build', assets: 'build', fallback: null }) } } export default config; Now, yarn build || npm run build The created article was stored in the build directory. Let's see if we can actually obtain the article. yarn preview || npm run preview We had no problems seeing it, right? Now, all you need to do is store the article according to the project, such as S3, hosting service, or rental server. Impressions Once you've tried Svelte out for yourself and seen the code with your own eyes, I'm confident you'll get a sense of what makes it special. You can create an application with less code thanks to Svelte's write less code concept. So, how about it? Did that come across? Although it's still in development as a beta version, I think you can tell this is a JS framework with a lot to offer. Have a good Svelte life, everyone.
はじめに こんにちは! KINTO テクノロジーズのプラットフォームGでCloud Infrastructure Team(Osaka Tech Lab)に所属している井木です。同じ大阪にいるチームメンバーの若手ホープがCloudFront Functionの障害対応について執筆すると聞いたので、事前知識としてのCloudfrontエッジ関数ついて記載しようと思います! まずは、CloudFrontについて CloudFrontはコンテンツ配信サービス(CDN)であり、コンテンツの配信をよりユーザに近い地点で行うために、世界各地にCDNの拠点を配置してコンテンツのキャッシュを行っております。ユーザ側は一番近いCDNの拠点にアクセスすることにより低レイテンシーでコンテンツへのアクセスが可能になります。また、エッジロケーションには2つあり、ユーザに近いエッジロケーションとオリジン(コンテンツ)に近いリージョンエッジキャッシュ(リージョナルエッジロケーション)が存在します。 エッジ関数とは? エッジ関数とは、そのエッジロケーションでトラフィックを処理しているエッジサーバー上で動く関数のことを指します。 エッジ関数を利用すると、リクエスト時やレスポンス時に関数を実行することができ、弊社においては主に下記の機能を実装して動かしております。 レスポンスのURLをリダイレクト ヘッダーの追加 リクエストパラメータに応じた画像のリサイズ エッジ関数が動作するタイミング エッジ関数が動かせるタイミングは以下の4つになります。 ビューワーリクエスト ビューワーレスポンス オリジンリクエスト オリジンレスポンス ビューワーはすべての通信に対して処理が走るため、共通の処理を行いたい場合に、オリジンはキャッシュがなかった場合に処理が走るため、オリジンに渡したい情報の制御やキャッシュされるデータのリサイズなどキャッシュされるデータを加工したい時などに利用します。 エッジ関数の種類 エッジ関数には2種類あり、CloudFront FunctionとLambda@Edgeが存在します。 CloudFront Function ユーザに近いエッジロケーションで動くエッジ関数です。 レイテンシーの影響を受けやすい CDN のカスタマイズを大規模に実行できます。 シンプルな処理(ヘッダー操作やリダイレクトなど)に向いており、Lambda@Edgeより費用は1/6未満。 ユーザ側の一番近いエッジロケーションで動作するため、ビューワーリクエストとビューワーレスポンスに対応してますが、オリジンリクエスト、オリジンレスポンスには対応できません。 Lambda@Edge オリジン側に近いリージョンエッジキャッシュで動くエッジ関数です。 CloudFront Functionでは対応できない処理がかかる関数や、AWS SDKを含むその他AWSサービスを利用したりファイルシステムへのアクセス等可能です。 Lambda@EdgeはAWS Lambdaの拡張機能でコンソール上での見え方は一緒ですが、ユーザが設定する環境変数が利用できないなどの機能制限があり、注意が必要です。 また、Lambda@Edgeの関数自体はバージニアリージョンに存在しますが、実際は各リージョンエッジキャッシュで動くために、対応するリージョンにレプリカを配置して動作します。そのためLambdaの同時実行数や各サービスへのアクセスリミットなどについては対応するリージョンにて加算されるため注意が必要です。(日本であれば東京リージョン) ビューワーリクエスト、ビューワーレスポンス、オリジンリクエスト、オリジンレスポンスすべてに対応してます。 CLoudFront FUnctionとLambda@Edgeの違い CloudFront Functions Lambda@Edge プログラミング言語 JavaScript Node.js / Python イベントソース ビューワーリクエスト ビューワーレスポンス ビューワーリクエスト ビューワーレスポンス オリジンリクエスト オリジンレスポンス Scale リクエスト数: 毎秒 10,000,000 件以上 リクエスト数: 1 リージョンあたり毎秒 10,000 件まで 関数の持続時間 1ms未満 ビューワー : 5秒 オリジン: 30秒 最大メモリ 2 MB 128 ~ 3,008 MB 関数コードと含まれるライブラリの最大サイズ 10KB ビューワー : 1MB オリジン: 5MB ネットワークアクセス いいえ はい ファイルシステムへのアクセス いいえ はい リクエスト本文へのアクセス いいえ はい 位置情報とデバイスデータへのアクセス はい ビューワーリクエスト : いいえ ビューワーレスポンス: はい オリジンリクエスト : はい オリジンレスポンス: はい 引用: CloudFront Functions と Lambda@Edge の選択 KINTO Technologiesにおけるエッジ関数の使い分け KINTO Technologiesにおいて、まだ十分に使い分けているわけではないですが、大量にアクセスされるような環境でのビューワーリクエスト/ビューワーレスポンスに関してはコスト及び、Lambdaの同時実行数に影響があるためCloudFront Functionを推奨しております。 それ以外に関しては、CloudFront FunctionはLambda@Edgeに比べて制限が厳しいため、日々のAWSコストを減らすより、Lambda@Edgeを利用することで開発や運用にかかるコストを削減する方法を選択しております。 さいごに 今回は、CloudFrontエッジ関数(CloudFront Function、Lambda@Edge)について記載いたしました。エッジ関数は特性を理解して利用することにより、システムの幅が広がりUXの向上になるものだと思っております。ただし、制限が厳しいため間違えるとエラーが発生する原因となり逆の効果となります。 このタイミングで再度理解していただき、開発に役立てていただければと思います。 CloudFront Functionの障害対応の記事も記載されるのでぜひ見てください! また、プラットフォームG(Osaka Tech Lab)で一緒に働いていただけるメンバーを募集してます! KINTOテクノロジーズ株式会社 プラットフォームG採用TOP wantedly
はじめに みなさまこんにちは!グローバル開発部兼テックブログ運用チームの森です。 KINTOテクノロジーズは現在東京・名古屋・大阪にそれぞれ拠点があり、東京は室町 (日本橋)・神保町の2つのオフィスに分かれています。私の所属するグローバル開発部は神保町オフィスにて日々働いております💪 今回は神保町オフィスにて2度ほど開催された情報共有会、その名も 神保町ISM (Information Sharing Meeting) の様子をお伝えします 🥳 ※余談ですが、神保町ISM(イズム)と思っていたメンバーもいたようで、それもそれで神保町らしさを作っていくという意味で良いなと思いました。 開催の背景 2022年の6月に神保町オフィスが開所して早1年、所属グループや新入社員も増えて、なんと約100名の大所帯になりました。 しかし、いまだに「他のチーム・グループが何をしているのかわからない」「どんな人がいるのかわからない」といった声をよく聞きます。 そこで、 他の拠点(Osaka tech lab)で行われているような情報共有会 を神保町でも開催してみては?という想いで、テックブログ運営チームで神保町所属のメンバーを中心に、完全なる勢いで企画してみました! 第1回 神保町ISM 2023年6月23日開催!第1回はとりあえず小さく始めてみよう!ということで30分開催で、Agendaも以下のようなシンプルな形式にしました。 Opening (5分) Ask me anything* (20分) Closing : アンケート案内 (5分) Ask Me Anythingとは? Ask Me Anythingとは「○○だけど、何か聞きたいことある?」のような意味で、AMAと略されます。主にソーシャルメディアを中心に、ホストやゲストに対して何でも質問できるような企画です。その名の通り、その人の経歴や、今の仕事、プライベートまで何でも聞くことができます。Webで調べるといろんなところで開催されているのでぜひご参照ください😄 参考: What is AMA? Understanding the Basics of Ask Me Anything AMAを企画に入れたので、質問を受ける人の選定から始めました。第1回は当時のグローバル開発部グループマネージャーにお願いしましたが、都合のつく日が1日しかなかったので、準備から案内、開催までを約2週間で実行に移しました。 突貫で実施した割に、約30名ほどに参加いただき、それなりに良い感想をいただくことができました🎉 以下、参加者の声です。 普段あまり会話する機会のない人と、仕事とは別に経歴や趣味など、様々な内容をお聞きできる場があるのはいいと思いました 資料でもあまり残っていないKINTO黎明期のお話が伺えて大変興味深かった。いろんなメンバーのお話をもっと伺ってみたい。 [第1回 事後アンケート] 次回も参加したいか? 一方で、AMAは一人の人に質問して話を聞くのがメインなので、参加者全員が参加している感はありませんでした。運営チーム内では振り返りを行い、「ワイワイ感」を創出するにはどうしたらよいか?を次回の課題として運営チームで模索しました。 どうやって振り返ってどうやって企画したかという点も、いろいろと工夫があるのですがそれはまた別の機会にご紹介させてください。 第1回の様子 第2回 神保町ISM そんなこんなで企画された第2回神保町ISMは2023年8月25日に1時間に延長して開催しました。 Agendaは以下の通りです。 Opening(5分) Talk with neighbours(25分)🆕❗ Ask Me Anything(25分) Closing(5分) AMAはとても好評だったので据え置きとして、今回はWoven Payment Solution開発Gの亀井さんに登壇をお願いしました。 皆さんに「ワイワイ」参加していただけるように運営チームが考えた企画は Talk with neighbours です。 かっこよく英語で言ってみましたが、4~5人のチームにわかれてフリートークをするコーナーです。 初めて顔を合わせる人達でフリートークするにはネタが必要なので、サイコロ(通称:ころすけ)でトークのネタを提供する方式を採用しました。 サイコロ?🎲 フリートーク?🗣️ そう、平成を生き抜かれた方々には馴染みもあるでしょう、あの番組を参考にさせていただきました。笑 企画中は、チームを分けて「はいどうぞ」で急にお話できるものだろうか?と心配していたのですが、そんな心配は不要なくらい、各チームが自然に話しはじめたのが印象的でした。 トークの話題が尽きた際にはころすけを転がして新しいテーマでお話しました✨ チームにわかれてワイワイガヤガヤ。伝わりますか? AMAは後半30分で行いましたが、Woven Payment Solution開発Gは普段KINTOとは離れて業務をされていることもあり、前回よりも多くの人から質問が出ました。「もっと話を聞きたかった!」などの声もあったのですが、情報共有会での時間は限られているので、ぜひこの場以外でも気軽に交流いただけたらと思います😄✨ [第2回 事後アンケート] 次回も参加したいか? 今回も前回と同じくらいで約30名のメンバーに参加いただき、「部署横断で人と話せてよかった」「同じオフィスで働く人を知ることができるのはとてもいい機会だと思う」「普段かかわりのない社員の方と交流ができ次回も参加できたらなと思いました!」など好評で、「次回も参加したい」の数は前回を上回ることができました✨ まとめ これまで2回開催してきた神保町ISMですが、総じて感じたのはやはり部署をまたいだ交流を皆さん求めているのだな、ということです。一見、業務には関係がなさそうに思える会ですが、こういった場での会話から「そういえばあの人これに詳しかったな、アドバイスもらえるかな」といった風に実業務にも生きてくる気がします。 まずは2回開催しましたが、改善点もたくさんあります。今後も定期的な開催を継続し所属メンバー同士の交流を深めつつ、神保町オフィス全体を活気づけられたら、と考えています 🎉
はじめまして!人事採用チームで組織開発担当です。 2023年1月に入社後、最初に手がけた全社イベントがとっても心温まる場になったので記事にさせていただくことになりました。記事は2023年2月開催の様子です。 KTC #thanks Days  実施したイベント名です。社内ではKINTOテクノロジーズのことをKTCと呼んでいます。 ■イベント概要 ・開催期間:2/13〜2/15 ・場 所:室町、神保町、名古屋、大阪の各拠点 ・内 容:各拠点に設置された「fleeお菓子bar」でプレゼントしたいお菓子をカップに詰め、日頃の感謝を一言添えたthanksカードを添えて社員同士で渡し合いました。 詰め詰めしたお菓子はこんな感じ 可愛い。。。 なぜやったのか? 理由は2つ。「コミュニケーションの活性化」と「カルチャー形成」です。 入社後いろいろな方と話して分かったのですが、役職、役割、年齢、性別問わず、もっとコミュニケーションを取れたら良いのにな〜という声が多くありました。このイベントをきっかけに、日頃言えていなかったり伝えそびれていた感謝を伝え合い、コミュニケーションを深める機会、そして今後の機会に繋げてほしいなと考えました。 ●感謝にフォーカスした理由 どんなコミュニケーション施策にしようかリサーチしたところ、感謝し合う効果の大きさが分かりました。 ・相手への感謝、優しさ、興味が生まれる ・相手への長所や良いところに着目するようになる ・コミュニケーションが活発になる ・生産性も向上する(あるデータでは幸福な気持ちだと+12%、不幸な気持ちだと-10%の生産性になる結果も) ・幸せホルモン「オキシトシン」が出てHappyになる などなど。普通の会話よりも、感謝をし合うコミュニケーションはさらに質が高いことが分かりました。 ●#thanksチャンネルの存在 さらに、KTCにはSlackに「#thanks」という素晴らしいチャンネルが自然発生しており、日々さまざまな「thanks」が投稿されていました。 しかし投稿者は全体の1割程度でしたので、KTC #thanks DAYSをきっかけにチャンネル利用率を高めたいなと。日頃から感謝を伝え合うカルチャー形成のきっかけに、このイベントを繋げていきたいと考えました。 実際の様子 お菓子Barにはたくさんの方が連日集う大盛況!各拠点、追加でお菓子を3度も仕入れるという嬉しい結果となりました!みなさん、選んでいる時から楽しそうだったのが印象的でした。 Slackチャンネルはどうだったかというと・・・ 可愛いpostが連続する中、こんな投稿も・・・ ・・・??? 「り・が・と・う」を#thanksチャンネルにpostをし、残りの「あ」を卒業メンバーに 手渡すして送り出すという何とも素敵な演出も登場しました!素敵! チャンネル促進の結果 実際に利用者は増えたのかというと、 <3日間の成果> #thanks登録者数 117%up #thanks投稿数 119post リアクション総数 2,000over 投稿者数:332%up(1月合計19名▶︎3日間合計 63名) というこちらも素晴らしい結果になりました!! 最後に 全拠点合同で実施をしてみた結果、数字としてもたくさんのリアクションが発生しましたし、3日間の様子から多くの方に喜んでもらえることができたと感じています。 また、KTCは全社員の約25%が海外国籍の方なのですが、感謝に言葉の壁はなく、文字が読めなくてもなぜか気持ちは伝わる、通じ合えるのだな〜と感じました。聞き取ることすらできない言葉もあったけど、感謝されていると分かる場面が何度もあったのですが、その度に「最高な企画をありがとう!」と毎回脳内変換させていただき、私の自己肯定感は爆上がりでした。 <実はこのPOP、全社員の国の言葉でありがとうと書かれています。> 感謝って当たり前に大事だと思っていますが、いざ意識して、言葉に、行動に移すとこんなにも素晴らしく尊いものだと気づく機会になりました。感謝の気持ちは国境を越える。相手の行動に目を向け、感謝の気持ちをもち、伝える。意識せずとも普通にできる、そんなKTCを目指し、組織の力になっていきたいと思います。 こんな素晴らしい企画を入社して担当させてくれて、本当に감사합니다!
皆様こんにちは、グローバル開発部兼テックブログチームの森です。普段はグローバル開発部にてWebのPdMを務めています。そんな私ですが、2023年9月1日~3日にかけて開催された iOSDC Japan 2023 へ社内の数名と参加してきました! 興味深いセッションの内容は参加していたiOSエンジニアが書いてくれると思うので、私は運営目線での感想をレポートします😎 (#iwillblog プレッシャーを与えますw) https://iosdc.jp/2023/ 参加のきっかけ iOSエンジニアではない私がなぜiOSDCに参加したのか? 実は最近、テックブログチームでは社外向け勉強会の運営をサポートしたり、社内イベントを企画したりしています。 最近ではコーポレートIT主催の KINTOテクノロジーズMeetup! や、DBREチームの DBRE Summit 2023 などの運営をサポートしました。 まだまだ駆け出しのチームなので、企画中やイベント中にも「どうやったら参加者にもっと楽しんでもらえるだろう?」「どうやったらうまくファシリテーションできるだろう?」といった悩みだらけです🤔 そこで、「iOSDCはどうやらめちゃくちゃ盛り上がるらしい」との噂を聞きつけ、カンファレンスの企画案やその盛り上げ術を学ぶべく、3日間に渡って潜入してまいりました!! 2022年のiOSDCレポートは弊社のiOSエンジニア達がレポートしてくれていますのでこちらもぜひご覧ください👍 https://blog.kinto-technologies.com/posts/2022-10-13-iosdc2022_participation_report/ 受付 会場に入ったらまず受付をして、ネームカードをもらいます。 このカードには入退場管理用のQRとNFCが入っています。QRは会場の入退場管理に使い、NFCはアプリで名札をコレクションすることができるのです。 このアイデアいいな。メモメモ📝 https://blog.iosdc.jp/2023/09/01/name-card-nfc-tag-exchange-2023/ 実は私、2日目にまんまとこのカードを忘れてしまったのですがその際も「名札忘れですね~」とスムーズに新しいカードをいただくことができました。こういうところまで考えられているのだな。メモメモ📝 セッション セッションは大きめのお部屋2つ、小さめのお部屋2つの合計4つのブースに分けて開催されていました。それぞれ聞きたいセッションに参加する形です。 🔻 会場全体図: 2階で各トークを拝聴。1階はスポンサーとコミュニケーション用のブース。飲み物等いただけます。 当日のタイムテーブル をイベント前から見ていたのですが、どのトークをどのタイミングでどのお部屋でやってもらうか、めちゃくちゃ調整されたんだろうな、と感動。4つのお部屋同時進行で、セッション内容によって時間も違うし、登壇者が出席できる日も違うだろうに。この調整力は身に着けたいです。 各セッションのタイトルと登壇者名は「世界の果てまでイッテQ!」のナレーションなどで有名な声優の 立木文彦さん が録音で読み上げてくださりました。聞いてる側も登壇者もテンション上がります🥳 オンライン配信 オフライン参加のチケットを購入すると、オンライン視聴もできました。(オンライン視聴のみのチケットもありました。) オンラインはニコニコ生放送です。私は現地参加できなかったセッションをオンラインで視聴していたのですが、驚きなのがラグがほとんどなかったこと!デバイスや環境にもよると思いますが、5秒もないのではないでしょうか?オフライン参加組とリアルタイムでSlack Chatできました。 会場転換中の配信画面では、スポンサーさんのCMはもちろん、準備期間中のスタッフさん達の様子が流れていたのも印象的でした。8月のイベントから、我々もハイブリッド配信を始めたので、次回の休憩中はこういうの配信するとおもしろいかもなぁ、と思って見ておりました。 LTセッション 参加する前から5分のLTが6-7本あるスケジュールが気になってました。 私も普段社内のイベントやミーティングをファシリテーションするので、このAgenda実現するの!?って思っていたのですが、できるんですねぇ~😂 まず、時間通りに登壇を終了させることが一番難しいと思っていました。ここの工夫がすごい…!5分のリミットが近づくと音楽で焦らせて ペンライト を振るように指示が出ます。登壇者を応援しつつ、登壇時間を厳守させるというなんとも良いアイデアでした。あと、振ってる側も楽しい…!(昨年とはまた違った演出だった様子) 登壇者の推しカラーで応援します。 それぞれ5分を滞りなく進めるため、Q&Aの時間は設けずに後で別のブースで話しかけられるような仕組みでした。登壇者の入れ替えは発表資料の準備のみです。この間もちろんオーディエンスは次の登壇者の"推しカラー"を聞いてペンライトの準備をしておきます。それだけだともちろん時間あまるので、ブースの紹介であったり、登壇者の裏話などをお話いただいて、待ち時間を長く感じさせない素晴らしい司会技術でした👏 演出はもちろんなんですが、このLTセッション、コンテンツとしても非常におもしろかったです。5分で必ず切られるのが前提なので、登壇者の方それぞれ工夫されてまとめていらしたのが印象的でした。 おそらく登壇者の中には言いたいことを全部言えずに終了を迎えた方もいらしたと思いますが、登壇者の皆さんさすがのタイムマネジメントスキルで、オーディエンス側としてはあまりそれを感じなかったです👏 プレゼンや登壇を経験されると多分みんな感じると思うんですが、短く自分の言いたいことまとめるのってすっごく難しい😭 自分もおしゃべりなのでつい長いことお話しがちです。その中で起承転結つけて、かつ、少しユーモアも交えながら…なんてめちゃくちゃ良いアウトプットの場ですよね! また、短い時間のプレゼンはタイムマネジメントスキルが磨かれます。残り時間を見ながらその場で「この部分はカット」などを瞬時に判断して、言いたいことを伝えながらまとめられていて、「きっとファシリテーションなんかもお上手なんだろうな」と感じました。 テックブログチームとしては社員のアウトプット力向上も目指しているので、ぜひ社内でもこういう場を取り入れてみたいです😎✨ ペンライト楽しんでいるテックブログメンバー 自分がやりたいこと=みんな楽しいのかも…!? iOSDCに参加してみた単純な感想ですが、総じてエンジニアでなくても参加してすごく意義のあるカンファレンスでした。 もちろん技術周りの詳しいところはわからないですが、非エンジニアでも自社プロダクトをより良いものにしたいという想いは同じです。 運営を学ぶ目的で参加しましたが、PdM視点からも「エンジニアさんってこういうことを考えているんだな」「こういう考えを私達のプロダクトに入れたらもっとよくなるかも!」と感じましたし、本来の目的だった運営目線では、それはもう非常に参考になるカンファレンスでした🤩 懇親会中、幸運にも実行委員長の 長谷川さん とお話する機会がありました。イベント全体の企画であったり、盛り上がるための工夫などをお伺いしたところ 「自分がやりたいことを具現化しているだけなんだよね」 とおっしゃっていました。これ、真理だなと。イベント終わった今も自分にめっちゃ刺さってます。 参加するまでは「どうやったらみんなが楽しんでくれるだろう?」という悩みを抱えていたのですが、「自分がおもしろいと思ったことをやってみたら、意外とみんなも楽しいのでは?」という新しい発想になりました。 もちろんそれが刺さるか刺さらないかはあると思いますが、この新たな視点を得て、今後もいろいろなイベントを企画・運営していきたいという熱が沸き上がりました🔥🔥🔥 KINTOテクノロジーズでは今後も外部向けのイベント開催を企画してまいります。案内は 弊社Connpass などを通じて随時行いますので、ご興味あればぜひご参加ください✨
こんにちは。 KINTO テクノロジーズの DBRE チーム所属のhoshinoです。 前職ではWeb制作会社でインフラ、バックエンドエンジニアとして働いていましたが、DBに興味がありその中でも DBRE の活動に魅力を感じたため2023年8月からKINTOテクノロジーズ DBRE にジョインさせていただくことになりました。 DBRE(Database Reliability Engineering)チームでは、横断組織としてデータベースに関する課題解決や、組織のアジリティとガバナンスのバランスを取るためのプラットフォーム開発などを行なっております。DBRE は比較的新しい概念で、DBRE という組織がある会社も少なく、あったとしても取り組んでいる内容や考え方が異なるような、発展途上の非常に面白い領域です。 弊社における DBRE の取り組み例としては、あわっち( @_awache )による DBRE ガードレール構想の実現に向けた取り組みについて というテックブログや今年の AWS Summit の登壇内容 、p2sk( @_p2sk_ )による DBRE Summit 2023の登壇内容 を是非ご覧ください。 今回の記事は、2023年8月24日に開催した DBRE Summit 2023をレポートしたいと思います! DBRE Summit 2023 とは DBRE の最新のトピックとプラクティスを学び、また DBRE ネットワーキングを目的としたイベントです。 connpass による事前申し込みではオンラインとオフライン合計で186名の方々が申し込みをしてくださり、当日も多くの方々にご参加いただけました。 登壇者の皆様、参加者の皆様、お忙しい中 DBRE Summit を一緒に盛り上げていただきありがとうございました! DBREを役割ではなく、文化にしたリンケージの取り組み 合同会社 Have Fun Tech 代表社員、株式会社 Linkage CTO、DBRE ユーザー会 DBREJP 共同運営 曽根 壮大(そね たけとも) / そーだい @soudai1025 さん @ speakerdeck DBRE は役割ではなくデータベースを中心とした運用の哲学であり普段のプロダクト開発の営みの中でデータベースをメンテナンスする文化です。 データベースを管理できる英雄が現れてしまうと、逆にその人に依存することになってしまう懸念点も出てきます。 そうならないよう安定したサービス運用のために英雄がいらない平和な世界を目指す必要があり、そのために、会社として風土を作っていく必要があります。 個人の適性や熱意は必要だけどそれだけでは文化にならないため、まずは風土を整えていくことが重要です。 また、設計はデータベースの安全や運用に直結しているため、開発者が DBRE を実践していく文化が必要です。 Database Reliability Engineering は哲学であり、運用のスタイルで職人芸ではなく仕組みで問題を解決していくために、対処ではなく予防をする先に DBRE があります。 始めるに遅いことはない今から始めましょう! <感想> DBRE を実践していく上で自分たちでどうにかしようとするのではなく、周りを巻き込んで行くことがとても重要なことだと実感しました。 DBRE = 哲学であり文化!会社そのものの風土を作っていくために、積極的に横断的なコミュニケーションを取っていきたいです! メルカリのDBREの今とクエリリプレイツールの比較 株式会社メルカリ DBRE 三谷智史 @mita2 さん メルカリの DBRE は設立して1年程、それまではSREがデータベースを担当していました。 メルカリのデータベースの概要としては、元々はMonolith APIとDBだけでしたが現在はMonolith + MicroServiceに分離されました。 DBRE の主な業務としては各マイクロサービ所有のDB支援としてDeveloperのお悩み解決としてDBの各相談を受けたり、生産性を高めるツールの調査を行っています。 MicroService DB支援を始めるに当たって、プロアクティブに活動したいが課題が見えづらい、DBRE チームの認知がされていない等の課題が存在していました。 対応策として Developer Surveyを実施、DBRE にどんなことを期待するかを選択方式でアンケートを実施 DBRE News Letterを半年に一回発行、DBRE チームからの積極的な発信 効果として徐々に会社内で認知されており、依頼が多くなってきています。 その他の DBRE 業務としては、Monolith DBの運用業務としてDBA業務やモダン化への挑戦を行っています。 本番のクエリをミラーするリプレイツールの選定を目的として、調査観点を設定し、調査を行いました。 リプレイツールとは 本番のクエリやトラフィックを別の環境に対して再現するツールで、移行やバージョンアップ時の影響調査に利用します。 比較したツール Percona query Playback ログベースで使用できてシンプルに使いやすいツール MySQL-query-replayer (MQR) MQRは大規模なリプレイにフォーカスされていてツールを作成したtomboさんのロマンを感じるツール <感想> 組織にどのような課題があるかをDeveloper Surveyでの調査や DBRE News Letterなど積極的に DBRE からの発信をしているという印象でした。 また、リプレイツールに関して調査観点やどのように調査を行っているかを聞けてとても参考になりました。 KINTO テクノロジーズでの DBRE 活動のご紹介 KINTO テクノロジーズ DBRE 廣瀬 真輝 @_p2sk_ さん。 @ speakerdeck 会社全体を横断する組織(プラットフォームG)の中に DBRE が所属しています。 DBRE のRoleとしましては、2つに分類を行っています。 Database Business Office 開発組織や各ステークホルダーからの要求に基づいて課題解決を行ったり、DBRE が提供するplatformの活用を推進する役割 Cloud Platform Engineering ガバナンスに準拠しながらクラウドの効果的な利活用を促進するために、DBに関連する標準やplatformを提供する役割 DBRE の活動内容の決め方としましては4本柱を定義し組織の現状を踏まえ具体的な活動を決定しています。 実際の活動 DBクラスタの情報を収集する仕組み DBシークレットローテーション 検証:Aurora zero-ETL integrations with Redshift (preview) KINTOテクノロジーズの DBRE ではDatabaseのReliabilityを向上をさせるためにプラットフォーム構築を行っています。 その手段としてEngineeringで解決する道を選択しました。 Cloudを適切に活用しAgilityを確保しつつDatabaseのSecurityとGovernanceを守る platformへの昇華させ企業全体に展開することでビジネスにいい影響を与え続ける Database Reliability Engineering というアプローチで進めています。 <感想> DBRE の役割を明確に示し、それを元に組織としての仕組みづくりを行うことで、データベースの信頼性向上とビジネスへの貢献を同時に追求していてとても素晴らしいと感じました。 今後 DBRE として定義された4本柱を元により良い仕組みづくりに貢献していきたいと思います! OracleDBを用いたDBREの実現 〜 オイシックス・ラ・大地でやってみた〜 オイシックス・ラ・大地株式会社 DBRE / DBRE ユーザー会 DBREJP 共同運営 原 智子 @tomomo1015 さん @ speakerdeck SRE/DBRE が実現する可視化の中でもコストの可視化があまり触れられていなかったため、会社のインフラ全体のコスト管理を行っています。 アプローチとしては請求書リストからシステムの実態と課題を把握することを行っています。 また、費用対効果を評価することで事業の利益率向上に貢献しています。 全体のインフラ費用のなかでもDBのコスト割合は高い、DBはコストをかけてまでシステムにとって重要なものではあるが、あぐらをかいて放置してはいけません。 DBのコストダウンのために、開発環境等のDBを利用していない日は基本停止や一番コスト対効果があるアプローチを考案しています。 商用DBを利用する上でライセンス形態とその金額を知っていることは DBRE を体現する上でとても重要です。 ライセンスの棚卸しを行い会社が契約しているライセンスの妥当性を把握しましょう。 今と未来をどうすれば信頼性向上ができるか、成長できるか、楽しくできるか、それを考えていくために時間を使いましょう。 コストを可視化することによって色々見えてくるものあるため、是非コストを可視化するところから事業貢献や信頼性向上へのアプローチをしてみてください。 <感想> 普段聞けないコスト面での可視化のお話を聞けてとても面白かったです。 お話にもありましたが、DBはインフラ費用の中でも割合が高くシステムの中でも重要な部分なので可視化し費用対効果を評価するのがとても重要と感じました。 コスト面も含め今後 DBRE として課題解決をしていけたらなと参考になりました。 ANDPADでのテーブル定義変更のレビュー自動化とガイドライン作成の取り組み 株式会社アンドパッド DBRE 福間 雄基 @fkm_y さん @ speakerdeck プロダクトチームがテーブル定義を変更する場合、DBRE がレビューする運用になっており、そのなかでいくつかの課題が発生しました。そのため、スケール可能なレビュー効率化の仕組みを作ることが必要と感じました。 調査として DBRE から開発者へのレビューコメントの分類を行い、対応できそうなものから小さく段階的にリリースしていくことにしました。早期に成果を得ながら進めていくためにこのアプローチを採用しました。 導線作成の自動化 データベース利用規約は既に作成されていましたが、必要になるまであまり読まれていないなかったと仮説を立て必要なタイミングで表示される導線を作成、利用規約への導線を作るコストのみで閲覧数が増加し、レビュー時の指摘頻度が減少しました。 テーブル定義レビューの自動化 機械的にチェックできる項目は自動でレビューしてくれる仕組みを作成、DBRE のレビューコストが削減されました。 仕組みをつくることによってレビュー効率化だけでなくレビューできていなかったプロダクトにも横展開できたため、 DBRE としてテーブル定義レビューの自動化ができました。 <感想> 導線作成やテーブル定義レビューの自動化を行うことで、適切なタイミングで使用することができ、とても効率化されていて素晴らしいと感じました。 このような仕組みを僕自身も今後作っていけたらなと、とても参考になりました。 株式会社アンドパッド DBRE 久保 路 @amamanamam さん @ speakerdeck あらゆるチームのテーブル定義変更の本番実施が一律的でより質が高くなるような行動方針を作った話 課題としてテーブル定義変更時の検証の質がチームで異なるため検証が不十分のままマイグレーション実施されてしまいサービス影響や障害の恐れがあります。 そのためヒアリングを行い原因を分析。検証の質を担保するための明確なガイドラインを作成しました。 作成したガイドラインの概要 本番実行までにやること一覧を作成 PRに載せてほしいことを作成 リリースタイミング検討フローを作成 導入した結果、検証結果の内容が網羅的かつ統一的なものになりました。 <感想> 課題を明確に洗い出し、課題を元に品質向上のためのガイドライン、プロセスを整理することで、 チーム全体の認識が高まり信頼性を高められていて素晴らしいと感じました。 DBRE としてチーム全体がその課題に共感し、協力して対処する動機づけになるようにガイドラインを整理していきたいです。 パネルディスカッション 「DBRE のこれから」 曽根 壮大(そね たけとも) / そーだい @soudai1025 さん 三谷智史 @mita2 さん 原 智子 @tomomo1015 さん DBRE をはじめるにあたってなにから始めたら良いか? ゴール設定を先に決めそれを元に何をすればよいかを決めていくことが良いかもしれないです。 なにが課題なのかを洗い出して、文化をつくっていくことが大事です。 データベースの標準化などが最初にやるテーマとしては良いかもしれないです。 DBRE を実践していくにあたって DBRE ならではのスキルって何がありますか? 組織を横断して活動を行っていくためコミュニケーションスキルが重要です。 プレッシャーがかかるときに前向きに対応できるパーソナリティーが必要です。 信頼を築ける能力が必要です。 キャリアとしての DBRE の魅力はなんですか? DBの専門性を高められます。 DBは移り変わりが激しくないため、一度身につけた知識や経験を長く活用できます。 DBだけではなくアプリケーション等の視野が広がります。 今後みなさんが取り組んでいきたいこと DBRE としてコミュニティー活動を行っていきたいです。 DBRE としての成功体験を増やしていきたいです。 DBRE がなりたい職種になるように願っています。 <感想> DBRE を実践していくうえで必要なスキルがDBの知識だけではないことに少し驚きました。 DBRE としてDBの知識はもちろん必要ですが、組織を横断した文化を作っていくにはコミュニーケーションスキルや前向きに対応できるパーソナリティー文化を作っていくことがとても重要だと実感しました。 僕自身もDBRE がなりたい職種になるよう願っています! まとめ いかがでしたでしょうか? DBRE 自体まだまだ発展途上で導入している企業が少ない取り組みのひとつです。 その中でさまざまな企業の DBRE 活動をDBRE Summitを通して知ることができとても有意義な時間になりました。 僕自身バックエンドエンジニアから DBRE にジョインして間もない為、DBスペシャリストというわけではありませんが、DBへの改善タスクや横断した文化を作っていくエンジニアリングも重要な DBRE 活動であると、DBRE Summitを通して認識することができました。 https://youtube.com/live/C2b93fgn05c