
KINTOテクノロジーズ の技術ブログ
全1132件
Contents Introduction Target Audience Repository Setup Skeleton Batch Guide DB and CSV Batch Guide Continuous Integration Conclusion Introduction Hello, I'm Miyashita, an engineer from KINTO Technologies' Common Service Development Group[^1][^2][^3][^4][^5]. While developing batch processes with Spring Boot 3, I encountered several challenges with Spring Batch's class structure and annotations. The transition to Spring Boot 3 presented additional complexities, particularly with multi-database configurations and error handling. A particular challenge was the lack of Japanese documentation for Spring Boot 3. While referring to the official documentation, I had trouble finding configurations that matched my requirements and encountered issues with multi-database setup and error handling. This led to a cycle of trial and error, making me acutely aware of the challenges in building a batch process from scratch. In this article, I've compiled information to help others facing similar challenges implement Spring Batch more smoothly: Spring Boot 3 Batch Skeleton Immediate deployment through GitHub clone and run Ready for business logic implementation Pre-configured for production use Common Batch Processing Use Cases In addition to the skeleton, I'll introduce sample code for batch processing utilizing a multi-database configuration: Batch process for exporting DB records to CSV Batch process for importing CSV data to DB I hope this article helps make Spring Batch implementation and development easier. Target Audience This guide is designed for developers who are: ✓ New to Spring Batch 5 framework implementation ✓ Returning to Spring Batch after a hiatus ✓ Migrating from Spring Boot 2 Batch due to end of support ✓ Experienced with Java main method batches but need Spring Batch ✓ Seeking rapid batch development solutions Repository Setup https://github.com/kinto-technologies/SpringBoot3BatchStarter/ This is my repository. Please clone it and import it into your IDE. For GUI-based operations, use GitHub Desktop, Repository Structure The repository is structured as follows: . ├── gradlew # Gradle wrapper for build automation ├── settings.gradle ├── compose.yaml # Docker Compose configuration ├── init-scripts # Database initialization │ ├── 1-create-table.sql │ └── 2-insert-data.sql ├── dbAndCsvBatch # DB/CSV processing implementation │ ├── build.gradle │ └── src │ ├── main │ └── test └── skeletonBatch # Basic batch implementation ├── build.gradle └── src ├── main └── test Skeleton Batch Guide https://github.com/kinto-technologies/SpringBoot3BatchStarter/tree/main/skeletonBatch This is a skeleton code that becomes a complete batch process just by adding business logic. It consists of only the necessary code components. Core Concepts: Jobs and Steps Spring Batch is built on two fundamental concepts: Jobs and Steps. Jobs A Job represents the complete batch process: Contains one or multiple Steps Manages batch execution flow Supports sequential and parallel processing graph TD A[Job] --> B[Step 1] A --> C[Step 2] A --> D[Step 3] style A fill:#f9f,stroke:#333,stroke-width:4px Job Capabilities Capability Implementation Example Sequential Chain multiple jobs Daily data processing pipeline Error Handling Define recovery actions Automated error notifications Concurrent Run multiple jobs simultaneously Parallel data processing Parallel Multiple instances of same job Large dataset processing Step A Step represents a processing unit within a job. One job can register multiple steps, and step behavior can be designed flexibly like jobs. Implementation Method Steps can be implemented using either Chunk or Tasklet processing. 1. Chunk Processing This is a method for efficiently processing large volumes of data. graph LR A[Reader] -->|100 items at once| B[Processor] B -->|One by one| C[Writer] C -->|100 items at once| D[DB/File] Implementation Characteristics Processing is divided into three phases: Reader: Reads data in fixed quantities Example: Reading 100 lines at a time from CSV file using FlatFileItemReader Processor: Processes data one item at a time Example: Converting date formats using CustomProcessor Writer: Outputs data in bulk Example: Bulk INSERT to DB using JdbcBatchItemWriter Transactions are committed by chunk size (e.g., 100 items). This means that even if an error occurs midway, the successfully completed chunks are committed. 2. Tasklet Processing This is a method for executing simple, single-unit processes. Characteristics Simple implementation Easy to understand processing flow Straightforward debugging Choosing Between Implementation Methods Aspect Chunk Tasklet Data Volume Suitable for large volumes Suitable for small volumes Processing Complexity Suitable for complex processing Suitable for simple processing Management Cost Higher Lower Debugging Somewhat complex Easy Transaction By chunk By process unit Summary Job is the management unit for the entire batch process Step is the execution unit for specific processes Chunk is suitable for efficient processing of large data volumes Tasklet is optimal for simple processing Choose between Chunk and Tasklet based on processing requirements :::message Key Point For simple batches that don't require complex processing, choose Tasklet without hesitation. This skeleton batch also adopts Tasklet processing. ::: :::message alert Note In official documentation and many web articles, chunk processing is explained as the basic approach of Spring Batch, which often leads beginners to mistakenly think they must use chunks. This frequently results in implementing with chunks first, then realizing later that Tasklet would have been more appropriate, causing rework. ::: YAML Configuration and Spring Batch Management Tables Let's first explain the basic configuration needed to run Spring Batch in batch-dedicated mode. YAML Configuration https://github.com/kinto-technologies/SpringBoot3BatchStarter/blob/main/skeletonBatch/src/main/resources/application.yml This configuration allows the Spring Boot application to run in serverless mode. While typical Spring Boot applications maintain their process by starting servers like Tomcat, this is unnecessary for batch processing. With this configuration, the process terminates when batch processing completes. Spring Batch Management Tables Spring Batch requires management tables in a database to record execution results. However, managing databases and tables can be cumbersome. Moreover, you might need to run batches in environments without databases. In such cases, using H2 in-memory database is recommended. When the process ends: Memory is released Database and tables are cleared Next execution starts with a fresh state H2 is automatically configured if no database settings are specified in application.yml :::message Benefits of Persistent Storage While using H2 is convenient for development, using a persistent database allows you to: Maintain execution history Resume from interruptions Track batch execution status ::: Job Class Guide https://github.com/kinto-technologies/SpringBoot3BatchStarter/blob/main/skeletonBatch/src/main/java/com/example/batch/job/SampleJob.java#L16-L41 This is the core class for registering and executing Jobs in Spring Batch. Class Definition Key Points @Configuration Recognized as a Spring Batch configuration class Indicates that this class provides Spring configuration Required annotation for Job definition classes @Bean Applied to methods that generate objects managed by Spring Framework In this case, allows Spring to manage the Job created by createSampleJob The Job instance is used during batch execution :::message alert Important Note By default, the method name is used as the Bean name. If you copy this class to create a new Job, using the same method name will cause an error. To avoid this, specify a unique name like @Bean("jobName") . This is a common pitfall to watch out for. ::: Dependency Class Roles JobRepository : Manages job execution state PlatformTransactionManager : Maintains database consistency SampleLogic : Handles actual business processing Processing Flow Output job registration start log Create Step (define processing unit) Create Job and register Step Output job registration completion log Transaction Management Normal completion: Database changes are confirmed when all processing succeeds Abnormal termination: Database changes are rolled back when errors occur This ensures the reliability of batch processing operations. Logic Class Guide https://github.com/kinto-technologies/SpringBoot3BatchStarter/blob/main/skeletonBatch/src/main/java/com/example/batch/logic/SampleLogic.java#L13-L35 This class defines the actual processing content of the batch. Class Definition Key Points @Component Makes this class manageable by Spring Allows usage with @Autowired in other classes Tasklet Interface Interface representing Spring Batch processing unit Implement actual processing in the execute method Processing Flow Output batch processing start log Call SampleService's process method Output completion log on normal termination Log exception and re-throw on error occurrence Output batch processing end log Error Handling Normal completion: Return RepeatStatus.FINISHED to complete batch Abnormal termination: Catch exception, log it, and notify upper layer :::message Implementation Point While this class delegates processing to SampleService, you can implement simple processing directly in the execute method. ::: Service Class Guide https://github.com/kinto-technologies/SpringBoot3BatchStarter/blob/main/skeletonBatch/src/main/java/com/example/batch/service/SampleService.java#L8-L23 This class is for implementing actual business logic. Class Definition Key Points @Service Recognized as a Spring Framework service class Indicates this class implements business logic process Method Method for implementing batch business processing Includes start and completion log output :::message Implementation Point This class is completely independent from Spring Batch classes and interfaces. This means: Focus purely on business logic implementation Easy to write JUnit tests Easily reusable in other projects ::: Customization Options You can modify: Class name Method name Arguments and return values Business logic implementation (e.g., data validation, transformation, external system integration) This concludes our explanation of the main skeleton batch classes. This loosely coupled design makes the batch easy to maintain and test. Running the Batch Running from IDE Start the BatchApp class. It works like a regular Spring Boot application with no special startup arguments required. Running via Gradle from Terminal Execute the following command: ./gradlew :skeletonBatch:bootRun Running by Generating and Executing JAR File Gradle's default task is configured to generate a JAR file. Execute as follows: cd skeletonBatch ../gradlew java -jar build/libs/batch-skeleton*.jar Checking Execution Logs Let's examine the Spring Batch execution flow through the logs. 1. Job Registration Check ----------- Registering job: sample ----------- ----------- Job registered successfully: sample-job ----------- During Spring Boot startup, the batch job 'sample-job' was successfully registered. 2. Batch Processing Execution Started BatchApp in 0.456 seconds (process running for 0.616) Running default command line with: [] Job: [SimpleJob: [name=sample-job]] launched with the following parameters: [{}] Executing step: [processing-step] ----------- START ----------- Batch Processing ----------- --- Starting batch process --- --- Batch process completed --- Processing completed successfully ----------- END ----------- Batch Processing ----------- Step: [processing-step] executed in 3ms Job: [SimpleJob: [name=sample-job]] completed with the following parameters: [{}] and the following status: [COMPLETED] in 9ms Important Points from Logs: 'sample-job' executed and 'processing-step' started START and END markers clearly show processing boundaries Step completed successfully and job finished with COMPLETED status Application terminated normally Skeleton Batch Summary Advantages Complete batch process by just adding business logic Integration with schedulers like cron using generated JAR file High maintainability through simple structure :::message Development Support Spring Batch development often faces issues like: Missing annotations Configuration mistakes Complex error messages This skeleton helps you avoid these problems and focus on implementing business logic. ::: This skeleton code aims to contribute to more efficient batch development. DB and CSV Batch Guide https://github.com/kinto-technologies/SpringBoot3BatchStarter/tree/main/dbAndCsvBatch Overview This project includes two batch processes: DB to CSV Export Exports database records to CSV format Customizable extraction conditions via startup arguments Works with default settings CSV to DB Import Bulk imports CSV data into database Requires CSV file, so run export batch first Local Database Setup This batch uses a MySQL local database. Follow these steps for setup: Start MySQL Container docker compose up -d :::message If Docker is not installed, download and install it from the Docker official website . ::: Verify Setup Connect to MySQL container and check sample data: docker exec -it mysql-container mysql -u sampleuser -psamplepassword sampledb Run sample query: mysql> SELECT * FROM member WHERE delete_flag = 0 AND type IN (1, 2, 3) ORDER BY type ASC; mysql> exit Bye Entity Class Auto-generation After cloning the GitHub repository, you might encounter a "Entity class not found" error. This occurs because jOOQ needs to auto-generate Entity classes. Running Auto-generation Either command will generate Entity classes: # Execute default task cd dbAndCsvBatch/ ../gradlew # Or directly execute jOOQ generation ../gradlew generateJooq The build.gradle is configured for immediate use without additional settings. Default task execution includes: Cleanup of build results Java code formatting (Google Java Format) Entity class auto-generation (jOOQ plugin) Compilation Static analysis and testing (JUnit, coverage, SpotBugs) Executable JAR generation Generated Entity Classes Check generated Entity classes with: tree dbAndCsvBatch/build/generated-src # If tree command is not installed: ls -R dbAndCsvBatch/build/generated-src Example output: dbAndCsvBatch/build/generated-src/jooq └── main └── com └── example └── batch └── jooq ├── DefaultCatalog.java ├── Keys.java ├── Sampledb.java ├── Tables.java └── tables ├── Member.java └── records └── MemberRecord.java :::message alert Since jOOQ plugin auto-generates code from database schema during build, managing it with Git can cause conflicts when schema changes. Therefore, generated code should not be included in Git management. ::: Handling "Class Not Found" Errors Your IDE might report Entity classes not found. Resolve this by either: Add generated-src/jooq to IDE's build path Copy classes from generated-src/jooq to dbAndCsvBatch/src/main/java Production Environment Setup https://github.com/kinto-technologies/SpringBoot3BatchStarter/blob/main/dbAndCsvBatch/build.gradle#L101-L124 :::message Change connection settings to your DEV/STG database Or add your production CREATE TABLE statements to Docker Compose initialization SQL ::: jooq gradle plugin website Multi-database Configuration This batch uses a dual database configuration: H2 (In-memory Database) Used for Spring Batch management tables Resets when process ends Ideal for development and testing MySQL (Business Logic Database) Used for actual business data processing Runs in Docker container Configuration File (application-local.yml) Spring Boot's configuration file defines two databases under spring.datasource. https://github.com/kinto-technologies/SpringBoot3BatchStarter/blob/main/dbAndCsvBatch/src/main/resources/application-local.yml The configuration file includes: Two database settings Profile suffixes (local and server) Runtime profile selection capability The server profile is intended for your production MySQL server settings. Data Source Configuration Class https://github.com/kinto-technologies/SpringBoot3BatchStarter/blob/main/dbAndCsvBatch/src/main/java/com/example/batch/config/DataSourceConfig.java#L11-L37 Key Annotations @Configuration Marks class as Spring configuration Spring manages beans defined here @ConfigurationProperties Maps YAML settings to class properties Example: maps 'spring.datasource.mysqlmain' @BatchDataSource Specifies data source for Spring Batch tables Applied to H2 database @Primary Designates default data source Applied to MySQL data source Job Class Guide https://github.com/kinto-technologies/SpringBoot3BatchStarter/blob/main/dbAndCsvBatch/src/main/java/com/example/batch/job/DbToCsvJob.java#L31-L39 New Features Added Automatic Run ID Increment .incrementer(new RunIdIncrementer()) Automatically increments job execution number (run.id) Used for execution history management :::message While this sample uses H2 (in-memory DB) making the run ID transient, this is a standard implementation pattern when using persistent databases. ::: Listener Integration .listener(listener) Add processing before and after job execution Useful for logging, email notifications, etc. Logic Class Guide https://github.com/kinto-technologies/SpringBoot3BatchStarter/blob/main/dbAndCsvBatch/src/main/java/com/example/batch/logic/DbToCsvLogic.java#L18-L49 This example demonstrates basic logging implementation, but you can add custom processing like error handling and notifications. Parameter Configuration @Value("${batch.types:2,3,4}") private String typesConfig; Uses 2,3,4 as default values even without application.yml Can be overridden by passing --batch.types=1,2 at runtime Error Handling contribution.setExitStatus(ExitStatus.FAILED); Explicitly sets failure status on error Automatically sets COMPLETED status on normal completion Repository Class and jOOQ Guide About jOOQ jooq is a library that allows writing SQL as Java code: Express SQL syntax directly in Java code Auto-generate Entity classes from table definitions Type-safe SQL operations Select Processing https://github.com/kinto-technologies/SpringBoot3BatchStarter/blob/main/dbAndCsvBatch/src/main/java/com/example/batch/repository/MemberRepository.java#L18-L25 Key Features SQL-like Syntax Direct expression of SQL in Java code Leverage existing SQL knowledge Auto-generated Class Usage MEMBER: Represents table definition (column names, etc.) MemberRecord: For record mapping Bulk Insert Processing https://github.com/kinto-technologies/SpringBoot3BatchStarter/blob/main/dbAndCsvBatch/src/main/java/com/example/batch/repository/MemberRepository.java#L54-L69 Bulk Insert Features Registers multiple records at once instead of one-by-one Common in batch processing to reduce database load :::message While not used in this batch, example code for insert, update, and delete operations is included. You can quickly adapt the repository class by replacing table and column names to match your business environment. ::: Repository Class Summary Use jOOQ's Gradle plugin to auto-generate entities from database schema Auto-generated classes enable type-safe SQL writing in Java Easy to handle schema changes - just regenerate classes :::message Spring Batch supports multiple database operation methods: Hibernate (JPA) Powerful database abstraction Easy Spring Boot integration May have overhead with large datasets MyBatis Ideal for direct SQL management Strong dynamic query support May reduce maintainability Spring JdbcTemplate Lightweight database operations Good for simple queries Can be verbose ::: :::message alert Note Choose the appropriate method based on: Project requirements Team skill set Direct SQL execution if needed ::: DB to CSV Batch Execution Guide Run the DB to CSV batch following similar steps as the skeleton batch. Running via Gradle ./gradlew :dbAndCsvBatch:bootRun Running JAR File cd dbAndCsvBatch/ ../gradlew java -jar build/libs/batch-dbAndCsv*.jar Running without arguments produces this error: org.springframework.beans.factory.BeanCreationException: Error creating bean with name 'jobLauncherApplicationRunner' defined in class path resource [org/springframework/boot/autoconfigure/batch/BatchAutoConfiguration.class]: Job name must be specified in case of multiple jobs at com.example.batch.DbAndCsvBatchApp.main(DbAndCsvBatchApp.java:16) Caused by: java.lang.IllegalArgumentException: Job name must be specified in case of multiple jobs Why This Error Occurs Unlike the skeleton batch with a single job, this project contains multiple jobs: CSV to DB: Importing CSV data into database DB to CSV: Exporting database data to CSV The framework cannot determine which job to execute without explicit specification. Running with Arguments Specify the job name and environment in startup arguments: --spring.batch.job.name=DB_TO_CSV --spring.profiles.active=local --spring.batch.job.name=DB_TO_CSV: Specifies which job to run --spring.profiles.active=local: Activates local environment settings Example Commands # Using Gradle ./gradlew :dbAndCsvBatch:bootRun --args="--spring.batch.job.name=DB_TO_CSV --spring.profiles.active=local" # Using JAR directly cd dbAndCsvBatch/ java -jar build/libs/batch-dbAndCsv*.jar --spring.batch.job.name=DB_TO_CSV --spring.profiles.active=local Examining the Logs Let's check the execution logs: 1. Initial Startup Log ##### KEY:"sun.java.command", VALUE:"com.example.batch.DbAndCsvBatchApp --spring.batch.job.name=DB_TO_CSV --spring.profiles.active=local" ##### Spring Batch ##### - Job: DB_TO_CSV, Profile: local This confirms our startup arguments were correctly received. 2. Job Start Log ----------- JOB [Job Name:DB_TO_CSV] START! ----------- Executing step: [DB_TO_CSV-step] Fetching members with types = [1, 2, 3] Shows BatchNotificationListener's beforeJob method execution and configured types. 3. Database Operation Log -> with bind values : select `sampledb`.`member`.`id`, `sampledb`.`member`.`type`, `sampledb`.`member`.`name`, `sampledb`.`member`.`email`, `sampledb`.`member`.`phone`, `sampledb`.`member`.`address`, `sampledb`.`member`.`delete_flag`, `sampledb`.`member`.`created_at`, `sampledb`.`member`.`updated_at` from `sampledb`.`member` where (`sampledb`.`member`.`delete_flag` = 0 and `sampledb`.`member`.`type` in (1, 2, 3)) order by `sampledb`.`member`.`type` Version : Database version is supported by dialect MYSQL: 9.1.0 Fetched result : +----+----+----------+----------------------+----------+-----------------------------+-----------+-------------------+-------------------+ : | id|type|name |email |phone |address |delete_flag|created_at |updated_at | : +----+----+----------+----------------------+----------+-----------------------------+-----------+-------------------+-------------------+ : | 1| 1|John Doe |john.doe@example.com |1234567890|123 Main St, City, Country | 0|2024-12-07T09:46:07|2024-12-07T09:46:07| : | 2| 1|Jane Smith|jane.smith@example.com|0987654321|456 Oak St, Town, Country | 0|2024-12-07T09:46:07|2024-12-07T09:46:07| : | 26| 1|John Doe |john.doe@example.com |1234567890|123 Main St, City, Country | 0|2024-12-09T05:36:37|2024-12-09T05:36:37| : | 27| 1|Jane Smith|jane.smith@example.com|0987654321|456 Oak St, Town, Country | 0|2024-12-09T05:36:37|2024-12-09T05:36:37| : | 3| 2|ABC Corp |contact@abccorp.com |5678901234|789 Pine St, Village, Country| 0|2024-12-07T09:46:07|2024-12-07T09:46:07| : +----+----+----------+----------------------+----------+-----------------------------+-----------+-------------------+-------------------+ Fetched row(s) : 5 (or more) Batch process completed successfully. Step: [DB_TO_CSV-step] executed in 193ms Job: [SimpleJob: [name=DB_TO_CSV]] completed with the following parameters: [{'run.id':'{value=1, type=class java.lang.Long, identifying=true}'}] and the following status: [COMPLETED] in 212ms ----------- JOB [Job Name:DB_TO_CSV] FINISHED! status:[COMPLETED] ----------- https://github.com/kinto-technologies/SpringBoot3BatchStarter/blob/main/dbAndCsvBatch/src/main/resources/logback.xml#L21-L22 jOOQ's query and result logging is enabled in logback.xml for easier debugging. Generated CSV Check "id","type","name","email","phone","address","deleteFlag","createdAt","updatedAt" "1","1","John Doe","john.doe@example.com","1234567890","123 Main St, City, Country","0","2024-12-11T06:05:26","2024-12-11T06:05:26" "2","1","Jane Smith","jane.smith@example.com","0987654321","456 Oak St, Town, Country","0","2024-12-11T06:05:26","2024-12-11T06:05:26" "3","2","ABC Corp","contact@abccorp.com","5678901234","789 Pine St, Village, Country","0","2024-12-11T06:05:26","2024-12-11T06:05:26" "5","3","Alice Premium","alice.premium@example.com","4561237890","987 Maple St, City, Country","0","2024-12-11T06:05:26","2024-12-11T06:05:26" "6","3","Charlie Davis","charlie.davis@example.com","1112223333",,"0","2024-12-11T06:05:26","2024-12-11T06:05:26" The CSV file is generated using the OpenCSV library. opencsv website Testing Runtime Argument Override Let's try customizing the types parameter at runtime: --spring.batch.job.name=DB_TO_CSV --batch.types=4,5 --spring.profiles.active=local Log Output -> with bind values : select `sampledb`.`member`.`id`, `sampledb`.`member`.`type`, `sampledb`.`member`.`name`, `sampledb`.`member`.`email`, `sampledb`.`member`.`phone`, `sampledb`.`member`.`address`, `sampledb`.`member`.`delete_flag`, `sampledb`.`member`.`created_at`, `sampledb`.`member`.`updated_at` from `sampledb`.`member` where (`sampledb`.`member`.`delete_flag` = 0 and `sampledb`.`member`.`type` in (4, 5)) order by `sampledb`.`member`.`type` This confirms that the configuration file values were successfully overridden by command line arguments. CSV to DB Batch Execution Run the batch with the specified job name: --spring.batch.job.name=CSV_TO_DB --spring.profiles.active=local Log Output insert into `sampledb`.`member` (`name`, `email`, `phone`, `address`, `type`) values ('Premium Corp', 'premium@corporate.com', '8889997777', '555 High St, City, Country', 4), ('Elite Ltd', 'elite@elitecorp.com', '4445556666', '777 Sky Ave, Town, Country', 4), ('Guest User1', 'guest1@example.com', '', 'Guest Address 1, City, Country', 5), ('Guest User2', 'guest2@example.com', '9998887777', '', 5) Affected row(s) : 4 This confirms successful bulk insertion of records. Continuous Integration This project implements CI (Continuous Integration) using GitHub Actions. Quality management is efficiently handled through automated processing triggered by code pushes or pull requests. Main Workflow MySQL Setup Launch MySQL using Docker Compose Verify required tables JDK 21 Setup Install Java 21 Configure build environment jOOQ Class Generation Auto-generate entity classes from database schema Build and Test Execute Gradle build Run quality checks: JUnit tests Jacoco coverage SpotBugs analysis This workflow enables: Immediate detection of compilation errors Quick identification of JUnit test failures Rapid response to issues Consistent code quality maintenance Dynamic Badge Updates When the build and tests succeed, a dynamic badge is displayed on the GitHub README, indicating the status of the project. Code Coverage Visualization This project uses Codecov to measure and visualize test coverage. Coverage reports are automatically generated during pull requests, and the coverage rate can be checked via this badge: graph LR D[👩💻 Developer] -->|Push/PR| G[🐙 GitHub] G -->|Trigger| GHA[⚡ GitHub Actions] GHA -->|Build and Test Results| R[📄 README.md] GHA -->|Coverage Report| C[☁️ Codecov] C -->|Coverage Badge| R style G fill:#f4f4f4,stroke:#171515 style C fill:#f01f7a style R fill:#e6e6e6 This enables: Visual tracking of test coverage Quick detection of coverage changes Enhanced transparency in quality management Detailed coverage reports are available on the Codecov dashboard. Conclusion We hope you found this guide helpful! This project provides: Skeleton code foundation for efficient Spring Batch development Common use cases like "DB to CSV" and "CSV to DB" Flexible customization through database settings and CSV layouts We hope this skeleton helps streamline your batch development by allowing you to focus on business logic implementation. If you found this article helpful and got your Spring Batch up and running quickly, we would appreciate a ⭐ on our GitHub repository! Thanks for reading! [^1]: Post by Common Service Development Group Member 1 [ Implementing Domain-Driven Design (DDD) in Payment Platform with Global Expansion in Mind ] [^2]: Post by Common Service Development Group Member 2 [ Success Story: New System Development through Remote Mob Programming by Team Members with Less Than One Year Experience ] [^3]: Post by Common Service Development Group Member 3 [ Improving Deploy Traceability Across Multiple Environments Using JIRA and GitHub Actions ] [^4]: Post by Common Service Development Group Member 4 [ Development Environment Setup Using VSCode Dev Container ] [^5]: Post by Common Service Development Group Member 5 [ Guide to Setting Up S3 Local Development Environment Using MinIO (AWS SDK for Java 2.x) ]

はじめに VSCodeとCopilotの組み合わせが最高に楽しいです。楽しすぎて本業を忘れてしまいそうです。 本日はそんな楽しすぎる開発体験をみなさんにもぜひ知って欲しいという思いで記事を書きます。 この記事は KINTOテクノロジーズアドベントカレンダー2024 の25日目の記事です🎅🎄 今回の内容 去年辺りから熱くなったAI界隈ですが、今年もAIの話題が尽きない一年でしたね! KTCでは積極的にAIを取り入れて開発生産性低減の道を探っています。 今回はVSCode x Copilotの組み合わせでできることを紹介します。 でも、AIってなんか微妙なコードしか出してこないし、自分で書いた方が早いから使わないよね、という方もいるかもしれません。 僕も初めはそうでしたが、先日開催されたGitHub Universeで発表されたCopilot Chat/Editsを見て、AIとの共同作業が楽しくなるかもしれないと感じました。 と言うことで、今回は実際にCopilot Chat/Editsを使って、AIと共同でプログラミングをする中で、普段使いで有効だと思うTipsを紹介します。 https://reg.githubuniverse.com/flow/github/universe24/attendee-portal/page/livestream?tab.day=20241029 なんでFlutter? モバイル開発をする上で、iOSもAndroidも各OSの標準IDEを使って開発をするのが主流です。 しかし、今回はGitHub Copilotを使ってプログラミングするという観点で、VSCodeを使って開発することを前提とします。 そう考えると、モバイル開発で公式にVSCodeをサポートしているのはFlutterがメジャーです。 先日 FlutterKaigi にも参加し得るモノが多かったので、今回はFlutterを使ってAIとの共同作業をすることにします。ちなみに、FlutterKaigiのアプリ、本当に些細なIssueですが、僕もコントリビュートしました😀 実際に何ができるのか? GitHub Universeで発表された機能はPreview機能が多く、使用できる機能は限られていますが、すでにリリースされているCopilot Chat/Editsを使いこなすだけでも、AIとの共同作業が楽しくなり、開発者体験の向上が実感できました。 エンジニアの皆さんがAIを使ってコーディングするというと、ノーコードでアプリを作るとか、コードを自動生成するとか、そういったイメージがあるかもしれません。確かに、コードを自動生成する事は可能ですが、それはAIのほんの一部の機能でしかないです。 また、複雑な機能を持つコードを一度の指示で動作保証できるほどのコードを生成することは(指示出しが)難しいです。 この記事で紹介するのは、テストコードの作成、コードの整形・分割、リファクタリングなど、普段皆さんがコーディングでやっていることをAIとの共同作業を通じて行い、コードの品質を向上させることができるCopilot Chat/EditsのTipsになります。 それでは、ここからTipsの紹介です。 コードの要約 Copilot Chatの機能を使うと、コードの要約を簡単に作成できます。これを使えば、オンボーディング時のコード理解が早まります。 コメント記載 BEFORE AFTER コードにコメントを追加する際、Copilot Editsを使うと、Copilotが直接ファイルにコメントを追加してくれます。これにより、コードの理解が深まります。 また、すでにあるコメントを修正する際も、Copilotが適切なコメントを修正してくれます。 例えば上のクラスのaddメソッドに対して、バリデーションを追加した場合以下の様に指示するとコメントを更新してくれます。 BEFORE AFTER テストコードの作成 copilot editsのテキスト入力欄の上に現在のファイル以外に参照できるファイルを増やす事ができるので、テストコードを書いてもらうときは、 テスト用のファイルを作成し、そのファイルを開いたまま、参照ファイルに対象ファイルを追加すれば、テストコードを書いてくれます。 コードの整形・分割 Flutter等の宣言型UIを採用している言語でUIを作成しているとどうしてもネストが深くなってしまう問題が頻発します。 :::details 整形前のコード class SomethingPage extends StatelessWidget { const SomethingPage({super.key}); @override Widget build(BuildContext context) { return Scaffold( appBar: AppBar( title: const Text('Something Page'), ), body: Center( child: Container( padding: const EdgeInsets.all(16.0), color: Colors.blueAccent, child: Column( mainAxisAlignment: MainAxisAlignment.center, children: [ Container( padding: const EdgeInsets.all(8.0), color: Colors.redAccent, child: Row( mainAxisAlignment: MainAxisAlignment.center, children: [ Container( padding: const EdgeInsets.all(4.0), color: Colors.greenAccent, child: Column( mainAxisAlignment: MainAxisAlignment.center, children: [ Container( padding: const EdgeInsets.all(2.0), color: Colors.yellowAccent, child: const Text('Deeply Nested Widget 1'), ), Container( padding: const EdgeInsets.all(2.0), color: Colors.purpleAccent, child: const Text('Deeply Nested Widget 2'), ), ], ), ), ], ), ), ], ), ), ), ); } } ::: こういった問題もCopilot Editsを使うと、コードを見やすい単位で分割、整形してくれます。 :::details 整形後のコード class SomethingPage extends StatelessWidget { const SomethingPage({super.key}); @override Widget build(BuildContext context) { return Scaffold( appBar: AppBar( title: const Text('Something Page'), ), body: Center( child: Container( padding: const EdgeInsets.all(16.0), color: Colors.blueAccent, child: const NestedContainer(), ), ), ); } } class NestedContainer extends StatelessWidget { const NestedContainer({super.key}); @override Widget build(BuildContext context) { return Column( mainAxisAlignment: MainAxisAlignment.center, children: const [ InnerContainer(), ], ); } } class InnerContainer extends StatelessWidget { const InnerContainer({super.key}); @override Widget build(BuildContext context) { return Container( padding: const EdgeInsets.all(8.0), color: Colors.redAccent, child: Row( mainAxisAlignment: MainAxisAlignment.center, children: const [ DeeplyNestedContainer(), ], ), ); } } class DeeplyNestedContainer extends StatelessWidget { const DeeplyNestedContainer({super.key}); @override Widget build(BuildContext context) { return Container( padding: const EdgeInsets.all(4.0), color: Colors.greenAccent, child: Column( mainAxisAlignment: MainAxisAlignment.center, children: const [ DeeplyNestedWidget1(), DeeplyNestedWidget2(), ], ), ); } } class DeeplyNestedWidget1 extends StatelessWidget { const DeeplyNestedWidget1({super.key}); @override Widget build(BuildContext context) { return Container( padding: const EdgeInsets.all(2.0), color: Colors.yellowAccent, child: const Text('Deeply Nested Widget 1'), ); } } class DeeplyNestedWidget2 extends StatelessWidget { const DeeplyNestedWidget2({super.key}); @override Widget build(BuildContext context) { return Container( padding: const EdgeInsets.all(2.0), color: Colors.purpleAccent, child: const Text('Deeply Nested Widget 2'), ); } } ::: リファクタリング 歴史あるコードでよく見かける、依存度が複雑に絡み合ってしまったメソッドも、Copilot Editsを使うことで、SOLID原則に基づいたリファクタリングが可能です。 :::details 依存度が複雑なメソッドを持つクラス class SomethingLogic { Future<void> performComplexOperation() async { // Fetch data from remote server final response = await http.get(Uri.parse('https://example.com/data')); if (response.statusCode != 200) { throw Exception('Failed to load data'); } final data = jsonDecode(response.body); // Save data to local database final database = openDatabase( join(await getDatabasesPath(), 'app_database.db'), onCreate: (db, version) { return db.execute( 'CREATE TABLE data(id INTEGER PRIMARY KEY, value TEXT)', ); }, version: 1, ); final db = await database; await db.insert( 'data', {'id': data['id'], 'value': data['value']}, conflictAlgorithm: ConflictAlgorithm.replace, ); // Save data to shared preferences final prefs = await SharedPreferences.getInstance(); await prefs.setString('data', jsonEncode(data)); // Perform some complex logic if (data['value'] == 'special') { // ...existing code... print('Special value found!'); // ...existing code... } else { // ...existing code... print('Regular value found.'); // ...existing code... } } } :::: :::details SOLID原則に基づいたリファクタリングをしてもらったコード class DataFetcher { final http.Client client; DataFetcher(this.client); Future<Map<String, dynamic>> fetchData(String url) async { final response = await client.get(Uri.parse(url)); if (response.statusCode != 200) { throw Exception('Failed to load data'); } return jsonDecode(response.body); } } class DatabaseHelper { Future<Database> getDatabase() async { return openDatabase( join(await getDatabasesPath(), 'app_database.db'), onCreate: (db, version) { return db.execute( 'CREATE TABLE data(id INTEGER PRIMARY KEY, value TEXT)', ); }, version: 1, ); } Future<void> saveData(Database db, Map<String, dynamic> data) async { await db.insert( 'data', {'id': data['id'], 'value': data['value']}, conflictAlgorithm: ConflictAlgorithm.replace, ); } } class SharedPreferencesHelper { Future<void> saveData(Map<String, dynamic> data) async { final prefs = await SharedPreferences.getInstance(); await prefs.setString('data', jsonEncode(data)); } } class SomethingLogic { final DataFetcher dataFetcher; final DatabaseHelper databaseHelper; final SharedPreferencesHelper sharedPreferencesHelper; SomethingLogic(this.dataFetcher, this.databaseHelper, this.sharedPreferencesHelper); Future<void> performComplexOperation() async { final data = await dataFetcher.fetchData('https://example.com/data'); final db = await databaseHelper.getDatabase(); await databaseHelper.saveData(db, data); await sharedPreferencesHelper.saveData(data); if (data['value'] == 'special') { // ...existing code... print('Special value found!'); // ...existing code... } else { // ...existing code... print('Regular value found.'); // ...existing code... } } } :::: ここまでのリファクタリングを自分でやると、時間がかかりますが、Copilot Editsを使うことで、短時間でリファクタリングが可能です。 だいぶ見やすいコードになったので、ここから自身の経験をもとに、さらにリファクタリングを行う事も可能です。 その他 これ以外にも、基本的なSuggestionsの機能が強力で、普段であれば実装に困った際はブラウザとIDEを行き来していましたが、ほとんどの困りごとをCopilotとの相談で解決できるので、開発への集中が途切れなくなりました。これは地味に大きいです。 指示だしのコツ AIとの共同作業は、新しい発見がたくさんありますが、AIに対する指示だしが重要な要素だなと感じました。 僕の周りにもAIが使いづらく感じているエンジニアは多くいますが、AIに対して具体的な指示を出すことに慣れると、AIとの共同作業が楽しくなると思います。 僕が感じた指示だしのコツは シンプルな内容 具体的な内容 どのファイル 何をする どのようにする 一度に複数の指示を出さない 特に、指示を出す側がしっかりとしたプログラミング原則や設計思想を理解していることが重要だと感じます。 まとめ 今回はVSCode x Copilotの組み合わせによって、AIとできることを紹介しました。 Copilot Chat/Editsを使うことで、コードの要約、コメント記載、テストコードの作成、コードの整形・分割、リファクタリングが簡単にできる事が少しでも伝えられたら幸いです。 エンジニア界隈ではAIに対して賛否両論あり、 僕の周りのエンジニアもまだまだAIに対して抵抗がある人が多いです。 世間の流れは確実にAIに向かっていて、今後もAIは進化し、どんどんできることが増えていくことが予想されます。 僕らエンジニアはどうAIを使っていくかを考える時代になったのかなと感じでいます。 この記事が少しでもAIとの共同作業に対して興味を持っていただけたら幸いです。
KINTOテクノロジーズの景山です! 年末恒例ですが、2024年の振り返りと2025年の展望について書こうと思います。 2024年の振り返り 振り返ると、1年前とくらべて、やるべきことが増えました。 それにともなって、社員も増え、組織も拡大しました。 一方で、組織が拡大しても、内製開発組織としてのメリットを失わないように手をうってきたつもりです。 今年は本格的に販売店のデジタルトランスフォーメーションのサポート(販売店DXプロジェクト)が立ち上がりました。 すでに見積もり関連で販売店の工数を削減するツールや、お客様管理アプリの提供が始まっています。 また、AIを活用したプロダクト開発も順調に進んでいます。 AIやクラウド利用が進むにあたり、セキュリティもガバナンスする範囲が広がっています。 クラウドセキュリティの専門部隊の設置や、AIプロジェクトのセキュリティについても取り組んできました。 社内のAI活用への取り組みも強化してきました。 社内コミュニケーションツールのSlackとAIを組み合わせた仕組みは社内で一般化してきています。 非エンジニア社員からは生成AIを活用して、アプリケーション開発をしてしまうような例も出てきました。 さらにグループ会社や販売店への生成AI研修もはじめました。 重要施策の進捗 重要施策として、 昨年のアドベントカレンダー では下記3つを高めていく、と書きました。 技術力 開発生産性 リリーススピード まず、技術力については、トヨタ自動車およびグループ会社へのテック支援が増えました。 ITベンダー各社からも評価されるユースケースを作ることもできました。 とくに、テックブログは、多くの読者に支持され、なんと年間12万ユニークユーザーを達成しました。 多くの人が執筆に参加してくれるようになり、その結果、社外からの反響も大きくなっています。 つぎに、開発生産性については、Findy Team+で定量的に自分たちの生産性を把握し、個々の工程の生産性向上に資する取り組みが広がっています。また生成AIを活かした仕組みの導入、例えば、GitHub Copilotの活用など社員の開発生産性向上の意識も高まり、ビジネス企画からリリースまでの全体スループットをあげる取り組みなどいくつもの新しいイニシアティブがスタートしています。 また、リリーススピードについては、おもに要件定義までの工程の圧縮をはかってきました。要件定義工程を開発側がリードすることで実現可能かつ開発工数が少ない方法でプロダクト開発を行う方向にビジネス側をリードする、ということができはじめています。 まだまだ試行錯誤の段階でもありますが、このスピードに関する意識を社内でもっともっと浸透させたいと思います。 2025年の展望 では来年はどうするかというと、下記2つの「ファースト」に注力したいと考えています。 AIファースト リリースファースト(最短リリース) AIファースト AIファースト は文字通りなのですが、次のような動きを強めていきます。 すべてのプロダクトにAIをインテグレートしていく AIプロダクトを多く開発する 販売店、トヨタグループのAI活用を推進するドライバーになる これまでの社員みなさんの取り組みのおかげで、今年はこれらを推し進める下地が十分にできました。 来年は多くのアウトプットを出していけるはずと期待しています。 これからはAIを使わなくてもできるものでも、AIをあえて使って開発してみよう、というマインドが重要だと思います。そうした中で我々がAIファーストを実現するためのアイディアやコラボレーションが生まれてくることを期待しています。 リリースファースト リリースファースト(最短リリース) は、われわれが開発するプロダクトをいかに最短でリリースするか、知恵と技術を使ってここにこだわっていきたいと思っています。 ビジネスオーナーやプロダクトごとに最短リリースするためにやるべきことは異なります。 今年は一部のプロジェクトやチームでの要件定義工程及び、実装工程の生産性向上がメインでした。 来年は特定の工程の生産性向上にとどまることなく、各プロダクトチームが自分たちのプロダクトをステークホルダーも巻き込みどこをどうしたらリリース期間を短くし、最短リリースを実現できるのかを考えてほしいと思っています。 MVP(最小価値製品)の考え方を全面的に取り入れる必要もあると思っています。 当社の全プロダクトが同じやりかたで実現できるとは思っていません。 自分たちでプロダクトの価値について深く考え、最短リリースを実現することが内製開発部隊の強みであり、これが最大の事業貢献だと思っています。 来年は徹底的にこれを突き詰めていきます。 ユーザーファーストと組織インテンシティ またAIファーストとリリースファーストを支える基礎として、来年は改めて「ユーザーファースト」と「組織インテンシティ」にも注力していきます。 ユーザーファースト ではサービスを使うユーザーだけでなく、ビジネスパートナーやその向こう側にいる顧客としっかり向き合うことを徹底していきたいと思っています。 ユーザーや顧客にとっての価値が何なのかを能動的に見つけられることは、われわれ内製開発の価値を高めることに繋がります。 そのためにはユーザーリサーチなどの方法論も武器として身に付ける必要もあります。 インテンシティ は サッカー用語 です。 優れた能力をもつメンバーが多く集まっていることはKINTOテクノロジーズの強みですが、内製開発部隊としてより高い成果を実現するためにはチームや組織のレベルをもう一段、二段と高めていく必要があります。 KTCをインテンシティの高い組織にするため、ひとりひとりがどのような心がけや行動をすべきか考え抜いてもらいたいと思います。 全力投球 次の段階に進むため2025年のテーマには入れなかった技術力と発信力の向上は社内に定着し、あたりまえになってきていると感じています。これからも各自が意識して、継続的に取り組んでいってほしいKTCの永遠のテーマです。 これらも含めて、来年も手を抜かないで全力投球していきます。 KINTOテクノロジーズ 取締役副社長 景山 均
Happy Christmas🎄 Hello! I am Watanabe from the KINTO ONE Development Group, where I work as a front-end engineer specializing in product development with Next.js and TypeScript. I also contributed to the development and launch of our Tech Blog as part of the Tech Blog Management team. On the final day of our Advent Calendar, I’ll be sharing insights into the design choices and front-end development process behind the Tech Blog. Assembling the Tech Blog Team The Tech Blog management team was originally formed by four volunteers, led by Nakanishi-san, with the aim of fostering a culture of output within the company. We discussed the operation system and blog specifications with the awareness of visualizing the remaining tasks, and I recall how quickly decisions were made. Among the many roles on the Tech Blog, I was responsible for the overall design and front-end implementation. During weekly meetings, ideas from our discussions were incorporated into prototypes and shared with the team. Prototypes motivates the team, so as the implementation manager, I approached development while focusing on visible progress. Building the Tech Blog with Next.js The front-end framework (library) we use is Next.js. I chose Next.js because I'm most familiar with it. From the concept stage, I envisioned storing blog posts as Markdown files and generating a static site using a Static Site Generator, which seemed like a great fit. The static content is generated at build time from the project, and the deliverables are then hosted. Next.js also publishes examples on GitHub that combine various libraries. One of these was blog-starter , which provided a template for the blog, so it was easy to get started, which is another reason I chose Next.js. Based on the above, I categorized the steps needed to create our Tech Blog into the following three development stages: Design Selection Screen Implementation (article list page, article detail pages) Preparing Markdown Tools Design Selection I took on the responsibility for the design, but since I had no prior experience with blog design, I began by researching case studies from other companies. Taking the features and findings obtained from other companies' case studies into account, our team organized the UI elements and information necessary for the Tech Blog. Documentation of features and findings During our design research, we focused on four components—header, cards, list, and footer—with the goal of creating a simple and easy-to-understand design. Since I had decided to take responsibility for the implementation as well, I created the design with easy coding and scalability in mind. Component Classification When the design was nearly finished, I consulted with the site design department and received their feedback. Screen Implementation Since the screen template was provided by blog-starter, we adopted Tailwind CSS as our CSS framework to focus on coding styles. Tailwind CSS uses well-defined, standard class names, making it easy to recognize the styles they represent. Its utility-first approach makes style adjustments intuitive, ultimately lowering development costs. Several of our in-house front-end engineers have contributed to enhancing the tech blog and fixing bugs. I believe this framework is well-suited for team development because they can implement it smoothly with minimal learning costs. The ability to write responsive support within the same className is also a great advantage. <div className="md:px-6 lg:px-10 md:py-10 md:hover:shadow-xl"> <div className="mb-6"> <CoverImage slug={slug} title={title} src={coverImage} /> </div> <div className="flex items-center mb-4 md:mb-6"> <div className="background-color h-7 flex items-center rounded-lg p-2 md:p-4 mr-3"> <span className="text-white text-xs md:text-base">{category}</span> </div> <div className="text-gray-500 text-sm md:text-base transition"> <DateFormatter dateString={date} /> </div> </div> <h3 className="text-xl sm:text-2xl md:text-2xl lg:text-3xl mb-2 md:mb-6 leading-snug text-color"> <Link href={`/posts/${slug}`}> <a className="hover:underline">{title}</a> </Link> </h3> </div> Preparing Markdown Tools Our Tech Blog uses zenn-markdown-html and zenn-markdown-css as Markdown parsers. We chose these because the default Markdown notation provided by blog-starter lacks variation and is difficult to customize. The role of each parser is as follows. zenn-markdown-html Package for converting Markdown to HTML (markdownToHtml), including Zenn's own notation zenn-content-css CSS for applying to HTML converted from Markdown with zenn-markdown-html Specify className=znc to the component or block to which you want to apply CSS A wide range of embedded content is also available, making it easy to create engaging blogs. (Content can be easily displayed by simply stating the URL of the Tweet.) https://x.com/KintoTech_Dev/status/1597900747538046978 Functions I Want to Try in the Future The Tech Blog started small with the goal of being simple and easy to understand. I'll also summarize ideas for functions that I want to implement in the future. Since its release, we've received many comments from both inside and outside the company, asking, "Why not add this function?" I'm thrilled to see that we're getting more attention every day. We are actually working on updates, such as adding RSS function . Implementation of article search and refinement functions by adding tags and categories Implementation of localization function to support multiple languages Move content management to Micro CMS or cloud servers, and stop local management Summary Despite the limited resources, we were able to explore new front-end technologies and had a lot of fun developing. Furthermore, the growing number of people submitting pull requests and reporting issues suggests that a blogging culture is gradually taking root within the company. While there is still room for improvement in the Tech Blog, I'll continue to do my best and stay updated with the latest technologies. Conclusion I hope this year's advent calendar helps you learn more about our company's initiatives and how our employees work! Furthermore, KINTO Technologies is looking for people to work with us! You can find more information here Thank you for reading my article all the way to the end! Reference List of Zenn's Markdown Notation
This article is the entry for day [24] in the KINTO Technologies Advent Calendar 2024 🎅🎄 Introduction Hi, I'm Rasel , currently working in KINTO Technologies Corporation as an Android Engineer. Today, I’ll briefly introduce the approach to testing in Kotlin Multiplatform (KMP). Cross-platform testing in KMP allows you to ensure the reliability of shared code across Android and iOS. While simple tests are a great start, many applications require more complex setups to verify business logic, handle async functions, and test interdependencies between components. This post explores advanced testing scenarios, including handling async code, testing dependencies, using parameterized tests, and structuring complex setups. Let’s dig into the details! Setting Up for Advanced Cross-Platform Testing Configure Common Test Dependencies Here’s an enhanced setup with testing libraries for assertions, coroutines, and mocking: // In shared module’s build.gradle.kts plugins { id("dev.mokkery") version "2.5.1" // Mocking library for multiplatform } sourceSets { val androidInstrumentedTest by getting { dependencies { implementation(libs.core.ktx.test) implementation(libs.androidx.test.junit) implementation(libs.androidx.espresso.core) implementation(libs.kotlin.test) } } commonTest.dependencies { implementation(libs.kotlin.test) implementation(libs.kotlinx.coroutines.test) implementation(libs.kotlin.test.annotations.common) } iosTest.dependencies { implementation(libs.kotlin.test) } } With this setup, you’ll be equipped to handle async tests, and dependency mocking necessary for testing. Basic Testing in KMP KMP makes it easy to write shared tests in commonTest while allowing platform-specific tests in androidTest and iosTest . Here's an overview of how you can get started: class GrepTest { companion object { val sampleData = listOf( "123 abc", "abc 123", "123 ABC", "ABC 123", ) } @Test fun shouldFindMatches() { val results = mutableListOf<String>() // Let's get the matching results with our global function grep which is defined in commonMain module grep(sampleData, "[a-z]+") { results.add(it) } // Check results with expectations assertEquals(2, results.size) for (result in results) { assertContains(result, "abc") } } } With this simple test in commonTest , you can verify the shared logic in the commonMain module across platforms. Advanced Test Scenarios 1. Testing Asynchronous Functions with Coroutines Many shared KMP projects use coroutines for asynchronous work. Testing coroutines effectively requires using kotlinx-coroutines-test , which provides tools for controlling and advancing coroutine execution in tests. Here’s a sample scenario: Imagine you have a UserRepository that fetches user data asynchronously. We’ll write a test that controls the coroutine flow to simulate data retrieval. @OptIn(ExperimentalCoroutinesApi::class) class UserRepositoryTest { private val testDispatcher = StandardTestDispatcher() private val userRepository = UserRepository(testDispatcher) @BeforeTest fun setup() { Dispatchers.setMain(testDispatcher) // Set test dispatcher as main } @AfterTest fun tearDown() { Dispatchers.resetMain() // Reset main dispatcher } @Test fun `fetch user successfully`() = runTest { val user = userRepository.fetchUser("123") assertEquals("John Doe", user.name) } } In this example: Dispatchers.setMain(testDispatcher) replaces the default dispatcher, allowing us to control coroutine execution. runTest {} automatically handles coroutine setup and cleanup, making it easier to manage suspending functions. We can control the flow within runTest to simulate delays and other asynchronous behaviors. 2. Using Mocks and Verifying Interactions Mocking dependencies in a multiplatform setup can streamline testing complex interactions between classes. Here, we’ll mock an API client to simulate a network call and verify interactions with the repository. class NewsRepositoryTest { private val testDispatcher = StandardTestDispatcher() private val apiService = mock<ApiService> { everySuspend { getNews(defaultSectionName) } returns TopStoryResponse(mockNewsArticles) } private val repository = NewsRepository(apiService, testDispatcher) @BeforeTest fun setup() { Dispatchers.setMain(testDispatcher) // Set test dispatcher as main } @AfterTest fun tearDown() { Dispatchers.resetMain() // Reset main dispatcher } @Test fun `fetch news list for home section successfully`() = runTest { val articleList: List<Article> = repository.fetchNews() assertEquals(mockNewsArticles.size, articleList.size) assertEquals(mockNewsArticles.first(), articleList.first()) assertEquals(mockNewsArticles.last(), articleList.last()) verifySuspend { apiService.getNews(defaultSectionName) } } } const val defaultSectionName = "home" In this example: mock<ApiService>() allows the mock to return default values without explicit behavior definitions. verifySuspend checks that getNews() was called properly, ensuring the correct flow in the repository. everySuspend sets the mock data that will be returned in every call of getNews() . getNews() method of NewsRepository fetches data from ApiService as TopStoryResponse and returns the result as List<Article> 3. Parameterized Tests for Different Input Scenarios KMP currently doesn't natively support parameterized tests in the same way libraries like JUnit5 do. However, there are workarounds to achieve parameterized-like testing behavior using Kotlin's features, allowing you to test functions with various inputs in a concise, reusable way. Here’s an example of testing different date formats for a DateUtils function. class DateUtilsTest { private val testCases = listOf( Triple("2024-11-18T00:00:00", "dd MMM yyyy", "18 Nov 2024"), Triple("2024-11-18T15:34:00", "hh:mm", "03:34"), Triple("2024-11-18T15:34:00", "dd MMM yyyy hh:mma", "18 Nov 2024 03:34PM"), ) @Test fun `check date format`() { testCases.forEach { (dateString, outputFormat, expectedOutput) -> val actualOutput = formatDatetime(dateString = dateString, inputFormat = "yyyy-MM-dd'T'HH:mm:ss", outputFormat = outputFormat) assertEquals(expectedOutput, actualOutput, "Failed for date $dateString and output format $outputFormat") } } } [!NOTE] Here, formatDatetime() is a global function defined inside DateUtils to format datetime string. With this example: We define expected results for each input, making it easy to expand test coverage without duplicating code. Works in both androidTest and iosTest without relying on platform-specific test libraries. Platform-Specific Tests with Complex Setups Some test cases require using platform-specific APIs or behaviors, especially when working with Android’s SharedPreferences or iOS’s NSUserDefaults . Here’s a breakdown for both platforms. Android-Specific Test: Testing SharedPreferences In Android, you may need to test data storage with SharedPreferences . Here’s a setup using AndroidX’s ApplicationProvider to access a test context. @RunWith(AndroidJUnit4::class) class SharedPreferencesTest { private lateinit var sharedPreferences: SharedPreferences private val expectedAppStartCount = 10 @BeforeTest fun setup() { val context = ApplicationProvider.getApplicationContext<Context>() sharedPreferences = context.getSharedPreferences(SHARED_PREF_NAME, Context.MODE_PRIVATE) } @AfterTest fun tearDown() { sharedPreferences.edit().clear().apply() } @Test fun checkAppStartCountStoresCorrectly() { sharedPreferences.edit().putInt(KEY_APP_START_COUNT, expectedAppStartCount).apply() val actualAppStartCount = sharedPreferences.getInt(KEY_APP_START_COUNT, -1) assertEquals(expectedAppStartCount, actualAppStartCount) } companion object { private const val SHARED_PREF_NAME = "test_prefs" private const val KEY_APP_START_COUNT = "app_start_count" } } This platform dependent test needs to be placed inside androidInstrumentedTest and it will require an Emulator or real Android device to run. iOS-Specific Test: Testing NSUserDefaults In iOS, similar logic can be tested with NSUserDefaults . You’d typically write this test in iosTest , as shown below. class NSUserDefaultsTest { private lateinit var userDefaults: NSUserDefaults private val expectedAppStartCount = 10 @BeforeTest fun setup() { userDefaults = NSUserDefaults.standardUserDefaults() } @AfterTest fun teardown() { userDefaults.removeObjectForKey(KEY_APP_START_COUNT) // Clean up after test } @Test fun `test app start count stores correctly in NSUserDefaults`() { userDefaults.setObject(expectedAppStartCount, forKey = KEY_APP_START_COUNT) val actualAppStartCount = userDefaults.integerForKey(KEY_APP_START_COUNT) assertEquals(expectedAppStartCount, actualAppStartCount.toInt()) } companion object { private const val KEY_APP_START_COUNT = "app_start_count" } } Complex Test Setups: Testing Interdependencies Advanced tests sometimes need to simulate multiple dependencies interacting with each other. Here’s an example involving a repository that depends on both an API client and a local cache. class ComplexRepositoryTest { private val apiService = mock<ApiService>() private val localCache = mock<LocalCache>() private val repository = ComplexRepository(apiService, localCache) @Test fun `fetch data from local cache`() = runTest { everySuspend { localCache.getArticles() } returns mockNewsArticles val data = repository.getNewsArticles() assertEquals(mockNewsArticles.size, data.size) verifySuspend { localCache.getArticles() } } @Test fun `fetch data from remote source`() = runTest { everySuspend { localCache.getArticles() } returns emptyList() everySuspend { apiService.getNews(defaultSectionName) } returns TopStoryResponse(mockNewsArticles) everySuspend { localCache.insertAllArticles(mockNewsArticles) } returns Unit val data = repository.getNewsArticles() assertEquals(mockNewsArticles.size, data.size) verifySuspend { localCache.getArticles() apiService.getNews(defaultSectionName) localCache.insertAllArticles(mockNewsArticles) } } } In this example: The repository checks the cache first, and only calls the API if the cache is empty. By verifying interactions, we ensure the repository follows the intended flow and doesn’t call the API unnecessarily. With all those above, you have done writing tests for common, Android, and iOS implementations. You can now run those test individually or can also run all tests at once using gradle task named allTests , by which, every test in your project will be run with the corresponding test runner.  With every run of tests, HTML reports will be generated in the shared/build/reports/ directory:  In this way, we can proceed with our KMP journey while ensuring app quality with properly tuned tests. Best Practices for Complex KMP Tests Isolate Test Setup : Create helper functions or classes to set up mocks, reducing repetitive code. Control Asynchronous Behavior : Use kotlinx-coroutines-test to control coroutine timing and simulate delays or network responses. Mix Cross-Platform and Platform-Specific Tests : Use platform-specific tests for native behaviors and cross-platform tests for shared logic. Monitor Test Coverage : Ensure comprehensive coverage, especially for complex flows with dependencies. Conclusion Cross-platform testing in Kotlin Multiplatform can handle simple and complex test scenarios, providing robust tools to ensure code reliability across Android and iOS. By setting up reusable tests, controlling async behavior, and isolating dependencies, you can write advanced tests that verify critical business logic and enhance overall code quality. With these techniques, your KMP project will be well-prepared for consistent, reliable performance across platforms, delivering a seamless experience for users everywhere. Happy KMPing!
Introduction Hello. I am Okita from the Mobile App Development Group. I'm involved in developing a smartphone app for a specific service project. Although I'm working with the Tokyo team members, I'm primarily based at the Osaka Tech Lab. So, let me introduce you to the Osaka Tech Lab! History of Osaka Tech Lab Born in April 2022. The Osaka Tech Lab was established with the aim of strengthening our capabilities as an IT engineering company and broadening our reach, including recruiting talented engineers. Believe it or not...I started it by myself! I had the whole floor to myself at the start. Our company consists of four locations: Nagoya Office Muromachi Office Jinbocho Office Osaka Tech Lab "Why is only the Osaka location called Osaka Tech Lab?" I’m often asked this question. The reason is that 'Osaka Tech Lab' was perceived as sounding more stylish than 'Osaka Branch' or 'Osaka Office,' and it was thought to appeal to a wider audience. In July 2022. Our first Osaka recruitment brought in four people. And from there, we've steadily grown. As of May 2023, we've expanded to 16 members! Where is the Osaka Tech Lab? The closest station is Shinsaibashi Station! Osaka Tech Lab Just a 1-minute walk from Exit 3 of Shinsaibashi Station on the Osaka Metro Midosuji Line and Nagahori Tsurumi-ryokuchi Line. *Non-smoking facility (Indoor smoking area available). What's the Atmosphere Like at the Osaka Tech Lab? Let me give you a glimpse with some photos. Entrance Bookshelf On the top shelf, you'll find a collection of miniature cars featuring the KINTO logo. There are also cactuses. Free Space The area offers both sofa and table seating. We use this space to enjoy meals, take a quick break, or use it as a corner to focus on our tasks. Snack Area This space brings together team members working on different tasks , designed to encourage casual conversations during a quick break. It’s been a big hit! Clock Our discussions led to the purchase of this clock, which we all selected together. It went something like this. “It’s nice to check the time at a glance, isn’t it?” "Oh, I was thinking the same!" "Let’s ask if we can get one installed." "I like something stylish." "Let’s make sure it’s earthquake-proof!'" This is the kind of casual conversation we have, whether in person or on Slack. We Also Have Seasonal Decorations During the Christmas season, we even set up a Christmas tree. What Kind of Team Members Work at Osaka Tech Lab? There are a total of 16 team members, representing various groups from the following departments: Project Promotion Group Owned Media & Incubation Development Group Platform Group Common Service Development Group Analysis Group Corporate IT Group Human Resources Group Mobile App Development Group There are veterans who provide steady guidance, sometimes leading, sometimes mentoring others, as well as juniors who actively contribute a variety of fresh ideas. The balance of age groups feels just right. What Makes Osaka Tech Lab So Special Arguably the people and the unknown future. The people It's what makes it a comfortable place to be. You can say it has a warm, at-home atmosphere. Even visitors on business trips often compliment us like, Even visitors on business trips often compliment us, saying, "This is my first time here, but Osaka Tech Lab has such a great atmosphere!" I've thought about why it feels so comfortable here, and I believe it's because we have team members that respects each other, even with different roles. Everyone has their own opinions, but they’re also open to listening to others and engaging in discussions to improve things. It might seem like a given, but isn’t it actually quite rare? I think this is the strength of Osaka Tech Lab! The unknown future It’s not every day that you get the chance to help set up an office! I decided to join the company because I wanted to have such an experience. Whenever I raise my hand and say, "I want to try this," the response is always "Go ahead, it’s all yours!" Of course, it is not a free-for-all, but as long as I set clear goals and outline the steps, I'm encouraged to take on new challenges. Here's one example: We are organizing information-sharing meetings at The Osaka Tech Lab with the following objectives: To enhance communication among Osaka Tech Lab members To understand what our colleagues are working on and strengthen cross-functional connections To share team and individual experiences and inspire new initiatives Here's what we're doing: A group introduction An LT (Lightning Talk) A discussion to make Osaka Tech Lab better In January 2023, as the members had grown closer, we hosted the third session, inviting managers from various groups who are usually based at other locations. Talk, talk and talk more: Osaka Tech Lab's first step in shaping the future We listened to the managers’ expectations for Osaka Tech Lab, and each team member shared their thoughts. Looking back, I think this was a significant first step. At first, these sessions started with just 10 members. But as people invited others, it expanded to include other locations. Now, the number of participants from other locations exceeds the members of Osaka Tech Lab itself. While we occasionally meet members from other locations during business trips, these information-sharing sessions have also created connections with members we normally wouldn't interact with. Osaka Tech Lab's Ambition Each of us is currently working on Tokyo-based projects, spending our days in a fast-paced, stimulating environment. One day... Someday... We hope to launch, develop, and operate a service entirely from Osaka Tech Lab. It seems many of us secretly share this dream. I'm excited for the unseen future that lies ahead! Conclusion So, what do you think? Why not join us in building the Osaka Tech Lab together toward an exciting, unknown future? We look forward to your application! KINTO Technologies Recruitment TOP page Wantedly
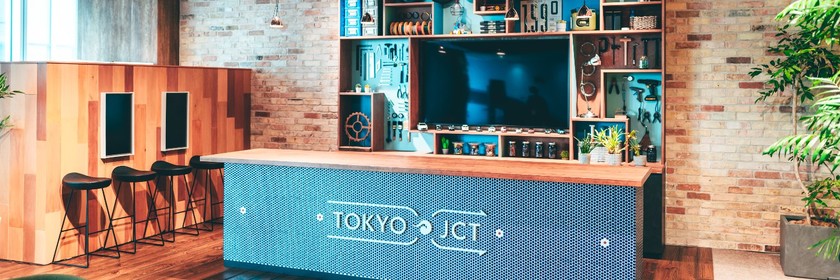
こんにちは( º∀º )/ 技術広報G イベントチームのゆかちです。 2024年、カンファレンスのスポンサー活動等も開始し外部発信活動が活発になり、 以前に比べて社内外どちらもイベントがたくさん増えました…! 社外向けイベントを開催していて、エントランスまでの行き方を伝えるのが難しいな~とモヤモヤしておりました。 「写真で説明したい…はっテックブログがある…!」と思い立った先の記事デス。 オフィスについて 弊社、拠点が4つあります! そういえば2年前にオフィス紹介の記事を書いていた…! @ card そんな中でイベント会場になることが多いのが、 室町オフィスの TOKYO JCT です。 コレド室町2のオフィス棟16階にあります!  ** 住所:〒103-0022 東京都中央区日本橋室町2丁目3−1 室町古河三井ビルディング(COREDO室町2) 東京メトロ銀座線『三越前』駅直結 ※改札でて徒歩 2 分 東京メトロ半蔵門線『三越前』駅直結 ※改札でて徒歩 5 分 JR 総武快速『新日本橋』駅直結 ※改札でて徒歩 5 分 JR 中央線・京浜東北線・山手線『神田』駅徒歩 10 分 ではでは各駅からのアクセス方法を写真にて紹介します! アクセス案内へのショートカット 東京メトロ銀座線『三越前』駅 東京メトロ半蔵門線『三越前』駅 JR総武快速『新日本橋』駅 JR中央線・京浜東北線・山手線『神田』駅 東京メトロ銀座線『三越前』駅 まずは一番近い銀座線から!  三越方面改札をでて左へ  コレド室町1があるので通り抜ける  通り抜けた先にコレド室町2の入口があります  はいってエスカレーターを上って…  すぐにみえるオフィスエリアになります! :::message イベント受付時間内はオフィスエリアのエントランスに受付が立っています! コレド室町2からオフィスエリアへは入館カードがないと入れないため、受付時間内は来場者っぽいかたを見つけたら扉を開けております。 ::: イベントではなくアポなど、18:00 までに来客者のかたは、 一旦外にでていただいてすぐ左手前のオフィスエリアの表入口からエントランスへお入りください。  こちらから江戸桜通り沿いへ一旦でる  こちらが正面入口 エントランス入って正面のビル受付にて入館手続き後、担当者より指定の階におあがりください。 :::message イベント受付時間以降にいらっしゃるかたも、同じく表入り口からエントランスへ入っていただき、 イベント情報に記載のある担当者の電話番号、もしくは公式 X アカウントへご連絡ください。 担当者が1階へお迎えにあがります。 @ card ::: 東京メトロ半蔵門線『三越前』駅 半蔵門線三越前駅からも直結ですがすこし歩きます・・・  日本橋方面改札をでて右にまっすぐ  小さい階段があるので下って斜め右に  まっすぐ進んで突き当りひだり  ここがコレド室町2です!  はいってエスカレーターを上って…  すぐにみえるオフィスエリアになります! :::message イベント受付時間内はオフィスエリアのエントランスに受付が立っています! コレド室町2からオフィスエリアへは入館カードがないと入れないため、受付時間内は来場者っぽいかたを見つけたら扉を開けております。 ::: イベントではなくアポなど、18:00 までに来客者のかたは、 一旦外にでていただいてすぐ左手前のオフィスエリアの表入口からエントランスへお入りください。  こちらから江戸桜通り沿いへ一旦でる  こちらが正面入口 エントランス入って正面のビル受付にて入館手続き後、担当者より指定の階におあがりください。 :::message イベント受付時間以降にいらっしゃるかたも、同じく表入り口からエントランスへ入っていただき、 イベント情報に記載のある担当者の電話番号、もしくは公式 X アカウントへご連絡ください。 担当者が1階へお迎えにあがります。 @ card ::: JR総武快速『新日本橋』駅 新日本橋駅からも直結ですがすこし歩きます・・・  改札をでて左にまっすぐ三越駅方面へ(新日本橋駅は改札がひとつ!)  三越駅方面へ左に曲がる  銀座線を右手にさらにまっすぐ  コレド室町1が左手にでてくるので入って通り抜ける  通り抜けた先にコレド室町2の入口があります  はいってエスカレーターを上って…  すぐにみえるオフィスエリアになります! :::message イベント受付時間内はオフィスエリアのエントランスに受付が立っています! コレド室町2からオフィスエリアへは入館カードがないと入れないため、受付時間内は来場者っぽいかたを見つけたら扉を開けております。 ::: イベントではなくアポなど、18:00 までに来客者のかたは、 一旦外にでていただいてすぐ左手前のオフィスエリアの表入口からエントランスへお入りください。  こちらから江戸桜通り沿いへ一旦でる  こちらが正面入口 エントランス入って正面のビル受付にて入館手続き後、担当者より指定の階におあがりください。 :::message イベント受付時間以降にいらっしゃるかたも、同じく表入り口からエントランスへ入っていただき、 イベント情報に記載のある担当者の電話番号、もしくは公式 X アカウントへご連絡ください。 担当者が1階へお迎えにあがります。 @ card ::: JR中央線・京浜東北線・山手線『神田』駅 最後に神田駅からの行き方を紹介しますね!  南口(日本橋方面口)をでてスターバックス沿いを進む  横断歩道を渡って左へまっすぐ  横断歩道を渡って右へまっすぐ  まだまだまっすぐ  コレド室町3の手前を左へまっすぐ  コレド室町2が見えてきますが、そのまままっすぐ通過してください  左手にオフィスエントランスが見えてくるのでこちらになります!  オフィスエリアのエントランス内に看板をもった受付が立っています(イベント受付時間内) イベントではなくアポなど、18:00 までに来客者のかたは エントランス入って正面のビル受付にて入館手続き後、担当者より指定の階におあがりください。 :::message イベント受付時間以降にいらっしゃるかたも、同じく表入り口からエントランスへ入っていただき、 イベント情報に記載のある担当者の電話番号、もしくは公式 X アカウントへご連絡ください。 担当者が1階へお迎えにあがります。 @ card ::: さいごに 以上、KINTOテクノロジーズ室町オフィスに足を運んでくださる人に 少しでも役に立てれば!な記事でした! ご来場いただきありがとうございます! またのお越しをお待ちしております(^_^)/
こんにちは(=゚ω゚)ノ KINTOテクノロジーズで採用担当をしている たけの ひかる @t_hikarutaaaan です! KTC歴はもう少しで3年ですが、人事としてはまだ1年目のぴよぴよです。 今回はそんなぴよぴよ人事の私が 初めてイベントの PM をして実践したこと、学んだことを共有したいと思います! イベント概要 イベント名: プロダクトヒストリーカンファレンス 主催:株式会社 YOUTRUST 実施日:2024 年 11 月 30 日(土)10:00-20:00 場所:TODA HALL & CONFERENCE TOKYO @ card はじまり 開催日から3ヶ月切ったタイミングでKTCがゴールドスポンサーとして協賛することが決定! 「よし、決裁とれたぜ!!」って安心し… それと同時に「あれ? なにからやるんだ…?」ってなっていた私… そんな私に 神の手 が °˖✧◝(⁰▿⁰)◜✧˖° 技術広報Gのマネージャーである きんちゃん が他イベントでのSlackチャンネルを共有してくださり、 「こうゆう動きをしたらいいんだよ!」とアドバイスをくださいました…( ;∀;) 実践で吸収するタイプの私にとって、一番わかりやすい情報を提供してくれました。感謝です。 次にしたこと 「よし、ほなSlackチャンネル見ていこか」 … (ㆆωㆆ)ジー 「うーん、なんかわからんけど、まずは関係者集めてMTGや!!!」 MTG セット して 社内の Confluence を漁る それっぽい 議事録 を発見 コピー! !  過去資料をコピー! なんだかんだで 社内の Confluence と過去のイベント関連の Slack チャンネル を漁ることで大体のことが解決できました! ! 改めて振り返ってみても、 ナレッジを溜めやすい環境が整っているんだな~ と感心と感謝の気持ちが沢山です…タスカッタ… いざ本番当日 前日にブースの準備は終えていたので 09:30 に会場入り 。  簡単なセッティングを終えたブース 少し落ち着いたところで開場時間が近づき…と思ったら… 「協賛企業みんなで円陣を組みましょう!!」 と Σ(・ω・ノ)ノ! しっかり両サイドの方と肩を組ませて頂きました。 さて、イベントスタート! 徐々に人も増えてきて、 お昼時にはブースに人だかり!  たくさんの方が興味を持ってくださいました! 本当にずーーーーーっと喋ってました! ! ブースでアンケートを実施していたのですが、予想より KTC のことを知っている方が多くて とても嬉しかったです。 一番多かった反応: 「色んなイベントでお見かけしました!!」 コツコツと沢山のイベントに参加してきた社員みんなの力を再認識しました! !  KTCのマスコット「くもびぃ」も活躍中 景山さん登壇 今回は 取締役副社長の景山均 と 株式会社Luup CTO 岡田直道氏 によるクロストークを実施! 「テクノロジーの活用でモビリティの新常識をつくる 2 社が描く未来」をテーマに 創業・設立時の想い 各フェーズにおける開発組織の変遷 制約の多いプロダクト開発に取り組む難しさと面白さ などなど、両社の挑戦についてざっくばらんにお話いただきました。  クロストーク 学んだこと 運営MTGはアジェンダ決めて、必要なタイミングで実施が良い 週次固定の定例スタイルも試してみると良いかも? くもびぃ人気 やっぱり可愛いは最強だった くもびぃは KINTO 公式マスコットキャラクターです @ card 社内にナレッジが溜まっている環境が強すぎる Slack のオープンチャンネル文化のおかげで探しやすい 経験値高い社員が集まりすぎ 後夜祭を予定していてよかった! イベント当日だけで繋がりを終わらせず、次に繋げやすい。 後夜祭には25~30名の方に参加頂きました!  後夜祭には他社の方も参加してくださいました X Mile さん @xmile_product 、 アスエネ さん @asuene_inc_ 、 note さん @note_corp 、ありがとうございました!! 次のイベントに活かしたいこと ブースに来た人に “どんな体験をしてほしいのか” をもっと考えたい ブースのセッティングやノベルティのアレンジに活かしたい 実際にお話した方限定で選考ステップをスキップできるような“express card”を用意したい キャリアSNSであるYOUTRUSTさんのイベントでもあることから転職意欲がある人も多かった 優秀な方を確実に選考に乗ってもらえるようなフローを作っても良かったかも KPI を立てたい 振り返って ビビりな私は 「何が起きるかわかんない…!」 とドキドキしながらスタートしましたが、 結果、 「なんとかなったーーー!」 と大きな問題なく終了できたのは、 様々な方面から先回りして「これ決めたほうがいいんじゃない?」「これどうなってる?」と誘導してくれたり 準備だけでなく当日も臨機応変に対応してくれた運営メンバーのおかげでした!! 本当にありがとうございました!!!  みんなでくもびぃ着用!
この記事は 技術広報カレンダー2024 の23日目の記事です🎅🎄 はじめに こんにちは!リナ( @chimrindayo )です。 KINTOテクノロジーズで、エンジニアとして モビリティマーケット の開発運用と技術広報を兼務しています。 さて、KINTOテクノロジーズは2022年7月にテックブログを開設し、執筆者及び読者のみなさんのおかげで今日までテックブログが運営できています。いつもありがとうございます! 中でもアドベントカレンダーは、テックブログの一大イベントです🎄 そんな一大イベントで、今年はついに シリーズ4まで計100記事 を投稿できました👏(すごい) こうして100記事リリースできるようになるまで、技術広報のメンバーはさまざまな工夫に日々取り組んできました。今回はアドベントカレンダーを100記事リリースできるまでの軌跡と工夫の一部をご紹介したいと思います。 KINTOテクノロジーズ アドベントカレンダーの軌跡 KINTOテクノロジーズのアドベントカレンダーは、有志のメンバーによってテックブログ開設前の2021年に開始しました。そして翌年、2022年4月にテックブログ運用プロジェクト(現:技術広報グループ)という有志のチームが発足し、2022年7月にテックブログを開設しています。 テックブログ開設以降は毎年欠かさずにアドベントカレンダーを投稿し、25記事ずつ投稿数を増やしています⤴️ 年 URL 投稿数 2021 KINTO Technologies - トヨタ車のサブスク「KINTO」開発中! Advent Calendar 2021 24 2022 4月:テックブログ運用チーム発足 7月:テックブログ開設🎉 - 2022 KINTOテクノロジーズ Advent Calendar 2022 KINTOテクノロジーズ グループ紹介 Advent Calendar 2022 50 2023 KINTOテクノロジーズ Advent Calendar 2023 75 2024 KINTOテクノロジーズ Advent Calendar 2024 100 では私たちが記事を増やすためにどんな工夫に取り組んできたのか、各年ごとにふりかえっていきます。 テックブログ開設初期〜継続期で各フェーズに合わせて工夫を凝らしているため、これからテックブログを開設する or したい方、現在テックブログを運用しているが執筆者が増えなくて悩んでいる方のご参考になれば嬉しいです🙌 2022年 アドベントカレンダーの工夫 まずはじめに、テックブログ開設初期の工夫点です。 ふりかえってみると開設初期は、テックブログを執筆してもらうために 各個人にアプローチ をしていたのが大きな特徴だと思います。では具体的な内容をご紹介します。 執筆者への感謝のスタンスをルールにする まずはじめにやったことが「執筆者への感謝」をレビュアーのスタンスとしてルールにすることです。 このルールは 中西さん を中心に有志のメンバーで決めていきました。 そして、レビュアーになり得るマネージャーやリーダーに全社会議や1on1などの場で依頼したり、テックブログのPRテンプレートに書くことで執筆者に感謝するマインドを伝え続けています。 テックブログのPRテンプレートから抜粋 今でも執筆に感謝するということは、技術広報チーム全員が大切にしています。 全てのマネージャーに記事を書いてもらう 次にやったことは、各部署のマネージャーに記事を書いてもらうことです。 テックブログ開設初期は、「テックブログって何?どうしてやるの?」と思っている社内のメンバーも少なくありませんでした。よって、まずは各グループをリードしているマネージャー1人1人にテックブログの必要性を理解してもらうこと、そして全社にテックブログを広めるためには上位レイヤーの人から執筆する必要があると考え、マネージャーのみなさんと30分ほどのミーティングをしたうえで実現したのが「KINTOテクノロジーズ グループ紹介」です。 https://qiita.com/advent-calendar/2022/kinto-technologies-introduction 「社員・オフィスの様子をみんなに知ってもらう」をテーマに、各グループのマネージャーおよびリーダがアドベントカレンダーを執筆しました。 クリスマスには副社長の景山さんが「2022年振り返り&2023年展望」と言う記事で締めくくっています🎅 2022年以降クリスマスは景山さんの記事が毎年恒例になり、採用候補者の方や社員がほぼ全員目を通しています。 KINTOテクノロジーズが どのような組織で この1年どんなことをやってきたか 今後1年どんなことをやっていくのか がこの記事に凝縮されていて、組織の道しるべとなるような記事です。 景山さんが年に1度力を入れて執筆しています。 振り返り&展望の記事はこちら👇 https://blog.kinto-technologies.com/posts/2022-12-25-LookBack2022/ 記事の構成を一緒に考える 主に記事の執筆意欲はあるが技術記事を執筆した経験がなく、何を書いたらいいか相談したい人向けに30分程度で記事の構成を一緒に考えるミーティングを実施しています。 技術広報のメンバーが執筆者にインタビューする形式で 今までどんな業務をしていたのか 各プロジェクトの失敗/成功談と改善策 技術スタック などをヒアリングして、技術広報のメンバーがインタビュー内容を聞きながらその場で記事の構成を組み立てていきます。一通りインタビューが終わったら、作成した記事の構成をその場で執筆者の方に見ていただきます。すると、ほとんどの人に「思ったより簡単書けるかも!」と言っていただけます。 2022年のテックブログを開設した当時は、この取り組みを執筆者全員に行っていました。 (今考えたら力技すぎる...!ですが全員とコミュニケーションを取るこの力技こそが、私たちKINTOテクノロジーズの技術広報の強みであると考えています。よくこの話を他社の技術広報の方に共有すると「素晴らしい取り組み」と評価をいただけることが多いです。) 全員に行っていた理由はいくつかあります。 主な理由は、 テックブログの必要性をみんなに理解してもらいたい テックブログを書くことのハードルを下げたい 誰が何の業務を担当しているのか知りたい 気軽になんでも相談してもらえる関係を築く などです。 しかし、最も大事だと考えているのが、みなさんの 業務に価値があると再認識 してもらうことです。 実際に当時みなさんと対面でミーティングをした時に「書いてもいいけど、自分の業務は普通のことだからブログにするほどじゃないよ」と言う人が多くいました。 いやいや普通でいいんです! 絶対に同じように悩んでいる人が世界に1人か2人いて、その人に届けばいいんです。 誰か1人に届けば、誰か1人が面白いと思えば、十分にあなたの業務をテックブログ発信する価値があります。 だから一緒に執筆してみましょう!! というのを執筆者1人1人に伝え続けました。 この考えは現在でも技術広報チームが大事にしており、先日リリースされたブログでもご紹介しています👇 https://blog.kinto-technologies.com/posts/2024-12-11-gekishin/ このように記事の構成を一緒に考えるだけでなく、執筆者がこれから書こうとしている記事の内容に自信を持ってもらうことが重要であると考えています。 2023年 アドベントカレンダーの工夫 テックブログの開設初期は、1人1人と会話することで「まずはテックブログを書いてもらう」ための工夫を中心に取り組んできました。 次に2023年はいかにテックブログを 継続 して書いてもらうかに着目し、さらに執筆者を増やすための取り組みを実践しています。 インプットを支援する 2023年まず技術広報のメンバーで実施したことは、 Udemy Business の導入支援です。 なぜ導入を支援したかというと、そもそもテックブログへのアウトプットは知識やスキルのインプットがなければできないと考えているためです。したがって、Udemyのアカウント登録条件を「テックブログを書くこと」にしています。 実際にUdemyを受講して記事を書いているメンバーがいます👇 https://blog.kinto-technologies.com/posts/2024-08-30-udemy-kotlin-coroutines-and-flow/ またその後2024年にUdemyの導入支援以外に技術広報で知識のインプットからアウトプットまで包括的にサポートできるように「学びの道の駅」というチームが発足しています。 学びの道の駅チーム発足の経緯はこちら👇 https://blog.kinto-technologies.com/posts/2024-04-23_%E5%AD%A6%E3%81%B3%E3%81%AE%E9%81%93%E3%81%AE%E9%A7%85%E3%81%AF%E3%81%98%E3%82%81%E3%81%BE%E3%81%97%E3%81%9F/ 入社エントリを書いてもらう そして2023年10月から入社エントリを開始しました。 これから入社する人に会社の雰囲気をわかってもらえたら嬉しい テックブログへのアウトプットへの抵抗がなくなってほしい 入社同期の横の繋がりを作れたら嬉しい という思いから、入社エントリの記入をお願いしています。 入社時に誰もがテックブログを書くことで、テックブログの書き方や書くこと自体のハードルを下げること、そしてテックブログを書くことが当たり前になることを願っています。 https://blog.kinto-technologies.com/posts/2024-01-01-newcomers-introduction/ また、この入社エントリは入社メンバー1人1人に執筆してもらうとして技術広報メンバーで企画を進めていたのですが、10月入社の Ryommさん が「共同執筆したい!」と提案してくれたのをきっかけに1記事を共同で執筆する流れができました。 入社エントリの例のように技術広報グループのメンバーだけで企画を決めて進行するだけでなく、社員全員でアウトプットするカルチャーを創りあげています。 チーム単位で執筆を依頼する 次に、アドベントカレンダーをプロジェクト・部署単位のチームで執筆してもらう企画を実践しました。 5グループ・5名ずつ、計25日分執筆しています。 新車サブスクサイトのリニューアル アジャイル開発 KINTO FACTORY QA Diversity & Inclusion テックブログを日頃業務をともにしているチームのメンバーみんなで書くことによって、執筆者がテックブログのレビュー依頼や執筆の相談がチーム内でよりやりやすくだろうと考えたためです。 そしてチームのメンバーと一緒に、また共通のトピックで記事を執筆したことは、テックブログは読み手である社内のメンバーにとっては身近なコンテンツになるため、テックブログを読むきっかけになったり、SNSでブログを共有するきっかけになると考えました。 実際の企画はこちらのブログで紹介しています👇 https://blog.kinto-technologies.com/posts/2023-11-20-advent-calendar/#2.-%E8%A8%98%E4%BA%8B%E3%83%AA%E3%83%AC%E3%83%BC 2024年 アドベントカレンダーの工夫 最後に今年実践した工夫を紹介します。2024年はさらなる テックブログの拡張と品質向上 をテーマに取り組んできました。 テックブログの勉強会を開催する 2024年8月に技術広報のメンバーである p2skさん による社内向けのテックブログの勉強会を実施しました。 「テックブログの振り返りと発信力向上のためのベストプラクティス」というテーマで、KINTOテクノロジーズのテックブログ全記事を読んだ上で、Goodポイントや記事をよりよくするためのアイディアを共有しています。 社内の勉強会参加者からは「モチベーションが上がった!」「記事が書いてみたくなった」「アドベントカレンダー頑張ろう!」などの声があがり大変好評でした。 勉強会の内容は、非常に濃く本記事では割愛します。 企画運営を公募する 例年は技術広報のメンバーでアドベントカレンダーを企画・リードしていたのですが、今年は有志のメンバーを募集しました。狙いは、技術広報グループ以外の新しいメンバーに運営に入ってもらうことで、技術広報が今までアプローチできていなかったメンバーにリーチすることです。  最大5名ほど集まったら嬉しいなと思っていたのですが、手を挙げてくれたのは1名でした。 その手を挙げてくれた1名が naka_shimaさん です。 naka_shimaさんが挙手してくれたことがきっかけで後述の部署単位でのシリーズの追加に繋がったと思います👏 部署単位でシリーズを埋める 2024年はグループ(部署)単位でシリーズを埋めました。 シリーズというのは、1~25日のアドベントカレンダー全日程 計25記事投稿することを指しています。 対象となったグループは、運営として挙手してくれたnaka_shimaさんが所属するモバイルグループと技術広報グループです。 モバイルグループ 技術広報グループ まずモバイルグループが選出された理由は、今年最も積極的に情報発信を行なっていたグループだからです。iOSDC2024やDroid Kaigiなどのスポンサーイベントの企画運営はもちろん、日頃のテックブログの発信も自発的に行なっていたのが特に目立っていたグループです。そこで「もしかしたら、1~25日全部モバイルグループで埋められるんじゃない・・・?」という無茶振りのもと実現したのが、モバイルグループで1シリーズです🎉 次に技術広報グループで1シリーズ実施することになった理由は、情報発信をリードするチーム自身が積極的にテックブログでのアウトプットを行う姿を見せることが重要だと考えたからです。 こうして ランダムテーマ(有志のメンバーが自由に執筆できる) モバイルグループ 技術広報グループ 翻訳(ローカライゼーションチームによる英日翻訳記事) の計100本をリリースすることができたのです。 今後の展望 テックブログを開設した2022年から2024年現在に至るまでの3年間の工夫をアドベントカレンダーを通してご紹介しました。みなさんのご協力とこれまでの工夫が2024年のアドベントカレンダー100本リリースに繋がっていると思います! 2025年は 執筆のしやすさ 執筆のモチベーション維持 を中心に工夫に取り組んでいきたいと思います。 2024年もありがとうございました☺️
こんにちは! KINTOテクノロジーズ(以下、KTC)の生成AI活用PJTで生成AIエバンジェリストをしている和田( @cognac_n )です。 さて、KTCでは、様々なシーンでの生成AI活用が進んでいます。例えば @ card @ card @ card :::details その他、生成AI関連のKTCテックブログ @ card @ card @ card @ card @ card ::: エンジニアも非エンジニアも、自分のロールや業務に合わせた生成AI活用をしていますね。生成AI活用PJTはこのように「だれもが当たり前に生成AIを活用している企業」を目指して活動をしてきました。 今回はその取り組みについてご紹介します。 1. はじめに、生成AI活用PJTの紹介 社内の生成AI活用を促進するため、2024年1月に立ち上げられた組織です。 生成AI活用PJTは現在、主に3つの機能を持っています。 PJTが持つ、3つの重点機能 生成AI活用PJTの機能 これらは独立した機能ではなく 良いアイデアを生み出す 実現の目処をつける 実装してデリバリーする 事例展開 という、生成AIがあらゆるシーンで活用されるためのサイクルを加速させることを目的としています。 生成AI活用PJTの機能とサイクル 今回はその中でも、 教育・研修 を中心に取り組みの紹介をしていきます。 2. 教育・研修体系の基礎となる考え方 「だれもが当たり前に生成AIを活用している企業」を具体化するために、3つの考え方を採用しています。 生成AIは特定のスペシャリストだけのものではありません 各自の役割に応じた「最適な活用レベル」があります 基礎から専門まで、段階的な学習を重視します 研修体系の基礎となる考え方 KTCでは複数の講師が様々なトピックについて研修をしています。また、受講者にはエンジニアも非エンジニアも、多様な業務に関わる人が含まれます。そのような状況下でもブレのない高品質な研修を提供するために、基礎的な考え方を共通認識として持つに至りました。 最初からこの考え方が固まっていたわけではなく、社内からのフィードバックをもとに改善を繰り返す中で自然と生まれた考え方です。 3. 実施している研修体系 3つの考え方をベースとして、段階的かつ体系的な研修プログラムを展開しています。 研修名 想定受講者 内容 初級 全社員 生成AIやプロンプトエンジニアリングの基礎知識。全ての基本となる最初の一歩 事例紹介 全社員 社内外の活用事例紹介。良い事例を取り込み、自らアレンジする力を身につける 事務生産性向上 各部から選抜(アンバサダー制) 生成AIをツールとして使いこなし、業務価値を生み出す。生成AIの活用を前提とした業務プロセスの改革を目指す。社内の生成AI活用推進者・伝道師となる ジェネラリスト システム開発関係者 生成AIを用いたシステム開発の勘所を学ぶ。技術の目利きや、価値の創出/検証力を身につける エンジニアリング 実装を行うエンジニア 生成AIを用いたシステム開発の実装力を身につける。価値を実現するための具体的知識と経験を得る それぞれの道のりにおいて、目指すべき生成AI活用のレベルを独自に定義しています。 4. 生まれ始めている価値 エンジニアの変化 既存システムへの生成AI機能の追加提案 生成AIを活用した新規サービスの企画提案 生成AIを活用した業務効率化ツールの自主的な開発 GitHub Copilotなどの生成AIツールの高度な活用 非エンジニアの変化 日常業務における積極的な生成AI活用 生成AIの支援によるテクニカルコミュニケーションの向上 簡易的なツール開発への挑戦 冒頭にブログを紹介した通り、研修を受けた社員が、それぞれの役割や業務の中で生成AIの価値を発揮し始めています。日常業務、コミュニケーション、システム開発・・・ありとあらゆるシーンで生成AIによる効率化、価値の向上が行われています。 我々に届く相談も「何ができるかわからない」ようなものから「やってみた!さらに良くするにはどうしたらいい?」「きっとこんなことができると思うので協力してほしい」と変化してきています。生成AIリテラシーが身についているからこそ恐れずに「まず試す」ことができ、「こんなことができそう(そしてそれは価値がある)」というセンスが身につきます。 5. 今後の展望 生成AI技術は日進月歩で進化しています。「当たり前の活用」が実現し始めているKTC/KINTOですが、この「当たり前」の水準にゴールはありません。 「だれもが当たり前に生成AIを活用している企業を目指して」 これからも取り組みを続けていきます! We Are Hiring! KINTOテクノロジーズでは、事業における生成AIの活用を推進する仲間を探しています。まずは気軽にカジュアル面談からの対応も可能です。少しでも興味のある方は以下のリンク、または XのDM などからご連絡ください。お待ちしております!! @ card ここまでお読みいただき、ありがとうございました!
Introduction Hello. I am Okita from the Mobile App Development Group. I'm involved in developing a smartphone app for a specific service project. Although I'm working with the Tokyo team members, I'm primarily based at the Osaka Tech Lab. So, let me introduce you to the Osaka Tech Lab! History of Osaka Tech Lab Born in April 2022. The Osaka Tech Lab was established with the aim of strengthening our capabilities as an IT engineering company and broadening our reach, including recruiting talented engineers. Believe it or not...I started it by myself! I had the whole floor to myself at the start. Our company consists of four locations: Nagoya Office Muromachi Office Jinbocho Office Osaka Tech Lab "Why is only the Osaka location called Osaka Tech Lab?" I’m often asked this question. The reason is that 'Osaka Tech Lab' was perceived as sounding more stylish than 'Osaka Branch' or 'Osaka Office,' and it was thought to appeal to a wider audience. In July 2022. Our first Osaka recruitment brought in four people. And from there, we've steadily grown. As of May 2023, we've expanded to 16 members! Where is the Osaka Tech Lab? The closest station is Shinsaibashi Station! Osaka Tech Lab Just a 1-minute walk from Exit 3 of Shinsaibashi Station on the Osaka Metro Midosuji Line and Nagahori Tsurumi-ryokuchi Line. *Non-smoking facility (Indoor smoking area available). What's the Atmosphere Like at the Osaka Tech Lab? Let me give you a glimpse with some photos. Entrance Bookshelf On the top shelf, you'll find a collection of miniature cars featuring the KINTO logo. There are also cactuses. Free Space The area offers both sofa and table seating. We use this space to enjoy meals, take a quick break, or use it as a corner to focus on our tasks. Snack Area This space brings together team members working on different tasks , designed to encourage casual conversations during a quick break. It’s been a big hit! Clock Our discussions led to the purchase of this clock, which we all selected together. It went something like this. “It’s nice to check the time at a glance, isn’t it?” "Oh, I was thinking the same!" "Let’s ask if we can get one installed." "I like something stylish." "Let’s make sure it’s earthquake-proof!'" This is the kind of casual conversation we have, whether in person or on Slack. We Also Have Seasonal Decorations During the Christmas season, we even set up a Christmas tree. What Kind of Team Members Work at Osaka Tech Lab? There are a total of 16 team members, representing various groups from the following departments: Project Promotion Group Owned Media & Incubation Development Group Platform Group Common Service Development Group Analysis Group Corporate IT Group Human Resources Group Mobile App Development Group There are veterans who provide steady guidance, sometimes leading, sometimes mentoring others, as well as juniors who actively contribute a variety of fresh ideas. The balance of age groups feels just right. What Makes Osaka Tech Lab So Special Arguably the people and the unknown future. The people It's what makes it a comfortable place to be. You can say it has a warm, at-home atmosphere. Even visitors on business trips often compliment us like, Even visitors on business trips often compliment us, saying, "This is my first time here, but Osaka Tech Lab has such a great atmosphere!" I've thought about why it feels so comfortable here, and I believe it's because we have team members that respects each other, even with different roles. Everyone has their own opinions, but they’re also open to listening to others and engaging in discussions to improve things. It might seem like a given, but isn’t it actually quite rare? I think this is the strength of Osaka Tech Lab! The unknown future It’s not every day that you get the chance to help set up an office! I decided to join the company because I wanted to have such an experience. Whenever I raise my hand and say, "I want to try this," the response is always "Go ahead, it’s all yours!" Of course, it is not a free-for-all, but as long as I set clear goals and outline the steps, I'm encouraged to take on new challenges. Here's one example: We are organizing information-sharing meetings at The Osaka Tech Lab with the following objectives: To enhance communication among Osaka Tech Lab members To understand what our colleagues are working on and strengthen cross-functional connections To share team and individual experiences and inspire new initiatives Here's what we're doing: A group introduction An LT (Lightning Talk) A discussion to make Osaka Tech Lab better In January 2023, as the members had grown closer, we hosted the third session, inviting managers from various groups who are usually based at other locations. Talk, talk and talk more: Osaka Tech Lab's first step in shaping the future We listened to the managers’ expectations for Osaka Tech Lab, and each team member shared their thoughts. Looking back, I think this was a significant first step. At first, these sessions started with just 10 members. But as people invited others, it expanded to include other locations. Now, the number of participants from other locations exceeds the members of Osaka Tech Lab itself. While we occasionally meet members from other locations during business trips, these information-sharing sessions have also created connections with members we normally wouldn't interact with. Osaka Tech Lab's Ambition Each of us is currently working on Tokyo-based projects, spending our days in a fast-paced, stimulating environment. One day... Someday... We hope to launch, develop, and operate a service entirely from Osaka Tech Lab. It seems many of us secretly share this dream. I'm excited for the unseen future that lies ahead! Conclusion So, what do you think? Why not join us in building the Osaka Tech Lab together toward an exciting, unknown future? We look forward to your application! KINTO Technologies Recruitment TOP page Wantedly
この記事は KINTOテクノロジーズアドベントカレンダー2024 の23日目の記事です🎅🎄 1. はじめに こんにちは、KINTO FACTORY でバックエンドエンジニアをしている西田です。 今回はAWSコスト削減をテーマにお話をしたいと思います。 2. コスト削減に取り組んだきっかけ KINTO テクノロジーズでは AWS のサービス利用料を Amazon QuickSight を使って可視化しており、プロダクト単位で利用料を確認することができます。 KINTO FACTORY をローンチしてしばらく経った頃、何気なくプロジェクトのコストを確認してみたところ、なんと社内全プロダクトの中で2番目にコストがかかっていることが分かりました。まだサービスを開始して間もない段階でここまでのコストが発生しているのは想定外でした。この「えっ!?」という発見をきっかけに、アプリケーションチームを主体に私たちのコスト削減への取り組みが始まります。 3. 具体的にやったこと それでは、私たちが実際に取り組んだコスト削減施策について詳しくご紹介していきます。 ECS Fargate のインスタンス数と起動タイプの見直し コストの内訳を眺めてみると、ECS Fargateの利用料が断トツ1位でした。KINTO FACTORYのアプリケーションがECS Fargate上で動いているため当然といえば当然なのですが、このコストを何とか最適化できないか検討することにしました。 まず最初に気づいたのが、「あれ?開発環境のインスタンス数、本番と同じになってない?」という点。開発環境ってそんなにガッツリしたスペックはいらないはず。そこで、開発環境のインスタンス数を必要最低限まで減らすことにしました。 さらに調べてみると、Fargate の起動タイプには通常とは別の Fargate Spot というものがあることがわかりました。Fargate Spot は AWS 上にある未使用のリソースを利用する仕組みで、通常の Fargate に比べて最大70%の割引が適用されます。使わない手はないですね。 Fargate Spot を使用すると、割り込み許容のある Amazon ECS タスクを、Fargate 料金と比較して割引料金で実行できます。Fargate Spot は、予備のコンピュートキャパシティーでタスクを実行します。AWS がキャパシティを戻す必要がある場合、タスクは中断され、2 分間の警告が表示されます。 -- https://docs.aws.amazon.com/ja_jp/AmazonECS/latest/developerguide/fargate-capacity-providers.html ただ、ドキュメントにもある通り Fargate Spot は予備のコンピュートキャパシティーでタスクを実行している仕組みとなるため、AWS 側のリソース調整でタスクが途中で中断される可能性があります。本番環境への適用は難しいので中断されても問題ない開発環境を対象に設定を変更しました。 開発環境の起動・停止の自動化 本番環境だけでなく開発環境も24/365稼働していたため、深夜帯や休日といった利用しない期間は開発環境を停止させるようにしました。 構成としては Step Functions を使って、Application、DB の起動停止を自動化しました。 前段に EventBridge を使い、cron で指定した日時に Step Functions に対して起動・停止のトリガーを送信します。 ポイントとしては DB の起動には時間がかかり起動直後に ECS を起動するとコネクションエラーになってしまうため、DB のステータスを確認してから ECS を起動するようにしています。 参考のため、以下にStep Functionsのワークフローを記述するサンプルコード(YAMLファイル)を示します。 "DB起動": { "Type": "Task", "Parameters": { "DbClusterIdentifier": "${db_cluster_identifier}" }, "Resource": "arn:aws:states:::aws-sdk:rds:startDBCluster", "Next": "Wait" }, "Wait": { "Type": "Wait", "Seconds": 300, "Next": "起動後のDBの状態取得" }, "起動後のDBの状態取得": { "Type": "Task", "Parameters": { "DbClusterIdentifier": "${db_cluster_identifier}" }, "Resource": "arn:aws:states:::aws-sdk:rds:describeDBClusters", "Next": "起動完了しているかチェック" }, "起動完了しているかチェック": { "Type": "Choice", "Choices": [ { "Variable": "$.DbClusters[0].Status", "StringEquals": "available", "Next": "各サービスの起動" } ], "Default": "Wait" }, サーバーレスアーキテクチャへの移行 次に、ある機能のバッチ処理を見直していた時に処理自体は1分もかからないのにECSを使った常駐サービスで稼働させていることがわかりました。 こちらもコスト的に効率が悪いと考え、Lambdaを用いたサーバーレスアーキテクチャへ移行しました。 Lambda はリクエスト数と実行時間に応じて課金されるため、短時間で終わる処理や常時起動不要な処理を実行するには最適なサービスです。 4. コスト削減の結果 結果として、コスト削減に取り組んですぐに効果が現れ、ピーク時と比較すると 65% も削減となりました。まさかの半分以下です。 これだけ削減できる余地があったのは正直驚きでした。。。 5. さいごに 今回は私たちのコスト削減への取り組みについてお話しました。 実施したことはどれも簡単で特別なものではなかったですが、大きな成果を出すことができました。 また、取り組んでみて分かったことがあります。コスト削減って、単純に「お金を節約できた!」というだけじゃないんですよね。 無駄なリソースを見直すことで、システム全体の見える化ができた アーキテクチャを見直すきっかけになった 「本当にこのリソースいる?」を考える習慣が身についた その先に得られるメリットも大きいので、改めて取り組みをして良かったなと感じます。 もし似たような課題をお持ちの方の参考になれば嬉しいです。
Introduction Hello! I am a team member of the KINTO Technologies study session organizing staff. The other day, we held a case study presentation and roundtable discussion session specializing in the field of corporate IT, under the title “ KINTO Technologies MeetUp! Sharing Four Case Studies for Information Systems People by Information Systems People .” Before the study session was held, a previous article on this topic talked about the steps from planning to launching by the organizing staff. In this article, by way of a sequel to that one, I would like to tell you about the various things the organizing staff did in the run-up to holding it. Following the previous session, we hope this will serve as a helpful reference for those looking to start and promote study sessions from scratch within their own organization. The previous article mainly covered the following: Planning the study session Calling for organizing staff members and speakers Discussing the matters still pending Dividing up roles and starting up agile progress management Now, I would like to delve deeper into things like what kinds of roles there were specifically, and what kinds of activities each of them entailed. Preliminary Reporting to Management This study session will be conducted as a "company activity" rather than "by individuals or volunteers". To get the appropriate support from the company, it is extremely important to report to management and get their understanding and advice regarding the activities. Therefore, this time we have decided to report in advance to the management team in the following manner. Reporting to the vice president (who is also the CIO and CISO): First of all, asking about the “holding of the event” itself, and asking for support Reporting to the president: Asking about the objectives, KPIs, equipment to be used, and budget Of course, when it comes to reporting, it is necessary to "set up a place for the report and make preparations in advance." However, by adopting the following format, we were able to carry it out relatively inexpensively. Reporting to the vice president Timing of implementation: Utilize the regularly scheduled departmental report meetings to provide updates. Report materials: We used the original plan document virtually as is, and provided details about the budget at a later date. Reporting to the president Timing of implementation: Report during the regular recruitment team briefing session Report materials: We summarized the plan document in three slides, and gave a simple report based on three points: an overview, the objectives, and the budget. As a result, we received positive responses in both cases, such as "Let's give it a try." Venue Arrangements At KINTO's Muromachi office, there is a photogenic spot called "KINTO TOKYO Junction (commonly known as the Junction)" that is always used for company introductions and external announcements. There is no reason not to use this photogenic spot when holding your first study session. Venue arrangements Junction bears the name of KINTO but is in fact owned by the parent company, Toyota Financial Services. For official use, permission from the parent company is required. However, a request can be made with just an email, and generally approval is given. We got the green light to use it for this event without any problems, too. Building arrangements The venue is a building with a security gate, so we needed to set up a reception desk outside the security gate to welcome outside guests. We notified the building management in advance and asked if we could place a desk there. This was also approved without any problems. Also, when we got permission from the building, we discovered that the automatic doors leading to the entrance were locked outside of business hours (after 6pm) (they can be unlocked from the inside, but an ID card is needed to enter from the outside). We asked the building management how to deal with this, and they agreed to install a small sign. Consultation is vital, right? Venue layout We were given permission to use the facilities, so all that was left was to decide how to lay out the venue! We had initially planned to use several large monitors for the presentation, but then we discovered a projector screen and decided we wanted to use a projector! However, we lacked the all-important projector for that, so we decided to procure one in a hurry, with a view to using it in future as well. (Everyone acted as one team wonderfully for this, too.) Wanting the layout to make the projector the main feature and encourage as many people as possible to take part as much as possible, this is what we came up with: Arrangements for the desks and chairs We used the desks and chairs that were originally there at Junction, but they were not enough on their own... So, we gathered up desks and chairs that could be used within the company. We mainly borrowed desks and chairs from the break space and were able to secure the required number of desks and chairs. On the day On the day, all the operation staff readily sprang into action, and we managed to get everything set up very quickly! The tidying up was also done really quickly, and this gave me a strong “one team” feeling, too. Everyone was amazing! Finally Inviting guests from outside to Junction was also a first for a company event, too. Throughout it all, everyone pulled together as one team to make the company look as good as possible to as many people as possible. We plan to carry on holding more study sessions as an organization in the future, too. To that end, we intend to use the results of this one to make them even smoother to enjoy! Snack Arrangements We decided to hold a social gathering as part of the study session And when it comes to social gatherings, snacks are a must. Right, time to prepare those! Snacks! The classic choice for a study session is pizza. It has been the most frequently provided food at the study sessions I've attended, leaving a strong impression on me We really wanted to make an impact right from the get-go, but since it was a first for everyone, we could not do anything over-the-top. So, we sensibly opted for pizza. Calories are right and just. And if there is pizza, there has to be cola. We were thinking that having these two would do the trick, but we were told from on high to provide some other drinks besides, so we prepared some alcoholic ones as well. How much should we provide? — Pizza — We had never paid any mind to how much there had been at the other study sessions we had taken part in up to then. How much would do...? The L-size pizza we were thinking of offering is 12 slices, and generally serves three to four people. This time, it's treated as a "light meal," so we decided to treat it as 5 people per slice. Even in the study sessions I've attended, people usually eat about 2 slices. We also took that personal experience into account. In the end, we arranged 10 pizzas for 50 people, thinking of a maximum of 40 participants plus the 10 operation staff. How much should we provide? — Drinks — For this, too, we also based the calculation on personal experience. Figuring that we usually drank around two or three cans per event ourselves...we decided to get three cans per person. The breakdown we decided on was to provide alcoholic drinks and soda in the ratio 1:1. Assuming 40 participants, that meant arranging 120 drinks. However...plastic bottles would be handier for the soda. So, we switched to those, and also ended up ordering 48 (two boxes of 24), because it was a convenient quantity in terms of placing an order. We prepared a total of 60 alcoholic drinks. Together with the 48 bottles of soda, this gave a grand total of 108 drinks. When should we arrange them by? We arranged the pizza the day before and the drinks three days before. We took delivery of all of them without any trouble. What were the results like? Pizza: None left over Alcohol: Eight left over → 52 consumed Soda: 21 left over → 27 consumed There were around 20 participants on the day, and the results were as above. This includes the food and drinks consumed by the staff on the day as well. In terms of the pizza, I feel there was not enough (because the operation staff did not get to have any of it). This is because the format of the social gathering was a "roundtable discussion" with KTC staff, and the time spent listening to each other was long, which meant more time spent eating. That is our analysis. Also, in terms of the drinks, we think the alcohol was just right, but our impression is that there was too much soda. Some people said they wanted tea, so we felt it would have been better to provide that instead of soda. In conclusion This was our first time providing snacks at a study session. So, while there were many things we were not sure about, I think we somehow managed to provide them without incurring any major dissatisfaction. We hope to provide them in a better way the next time we hold the session! Producing a Novelty Item HOS-PI-TAL-I-TY KINTO Technologies is a new company that was established in April 2021. Also, the format for holding this event was offline, which means people needed to come all the way to the venue at our company. There would be snacks and drinks like the ones mentioned above as well, but to make the effort even more worthwhile, we wanted to prepare something for everyone to: take home with them and remember the company by. To that end, we decided to produce a novelty item. How to make it happen? The members of the organizing staff discussed the matter together, and the unanimous result was, “Let’s make a novelty item!” And so, a team was launched to produce one. 1. What to make? The first thing we did was to decide what kind of novelty item to make. Of course, there were budgetary constraints as well, and when batting ideas around, we also pictured the kinds of people we were anticipating would attend.  Part of the materials we used to bat ideas around As a result, we decided to make a sticker this time! Lessons learned: It's important to ground your endless thoughts in a practical place. 2. How to make it? We had decided to make the item a sticker. We had a track record of making stickers for other in-house events, so we consulted with the design department, who have the know-how, about the purpose of the event, and with the corporate engineer about the expected attributes and interests of the visitors, and this is what we came up with! Ta-da! Based on these two patterns, we discussed which one would yield the most value as a novelty item for this event. As a result, we decided to go with the white-background, corporate-colors version! How it turned out Then, we steadily proceeded with placing the order and settling the payment, and awaited the delivery... Ta-da! (For the second time.) Production was completed without a hitch in time for the event! We hope that this novelty created with a one-team spirit spanning various departments will go on to be used in many places in the future as well, and help people know about KINTO Technologies. Promotion and Measurement Summary We thought about how to measure the results of this study session and how to announce the event itself. With the aim of gathering material for reporting to the company and indicators for doing kaizen (continuous improvement), we promoted the event as much as possible while measuring the influx into it and the impact of the event itself. We will share what we actually did, what we thought, and the results of our implementation. Background The first thing we thought about was reporting the results to the company. We had said that the study session would raise awareness of KTC, so for reporting its results to the company, we needed to gather data to show how well it had done so (the number of participants being a prime example). And since we wanted to hold the study session itself a second and third time as well, we figured we would need to have indicators for doing kaizen . Above all, since this was the first study session we held for outside the company, we honestly had no idea how many people would attend. To do our utmost to avoid winding up with zero participants, we tried out as many announcement methods as we could. In the end, we roughly settled on collecting the following indicators. Which channels had there been influx from, and how much? How much had the study session raised awareness of KTC? What we did and thought In order to visually represent what indicators we wanted, first, we wrote down the structure of the influx. Since we decided to accept entries to the event via connpass, we measured the influx into that. We also decided to measure how well the study session and roundtable discussion had helped raise awareness. Since it was an info sys event, we decided to announce it on the info sys Slack. In addition, since KTC has a Tech Blog and X (formerly Twitter) account, we asked the team operating those to announce it as well. We also used the in-house Slack to call on all employees to spread the word about it via social media. As results of the study session and roundtable discussion, we decided to prepare an X hashtag and pick up the number of posts and impressions that had it. Also, we decided to run a survey asking people if they had already known about KTC, measure the percentage who had not, multiply that by the total number of impressions, and use the result as a half-forceful way to measure the reach among people who had not known about the company before. Finally, after the event, we decided to measure how the influx and following on our company’s X account, corporate website, and Tech Blog changed, and how they changed from before the event to after it. Results Many people cooperated with spreading the word, and a total of 56 people applied to take part, so the capacity of 40 was filled up. On the day, 31 people actually came! The influx per channel for connpass was as follows: Up to the day of the event, there were 61 posts on X, and a total of 28,608 impressions. Of these, 376 were accessed, so 1.31% of the people who had viewed us on X had come to our connpass. Our survey revealed that 39% of the event participants had not originally known about KTC. If we apply this to the 1,356 visitors to connpass, that means that 39% = about 530 people did not know about KTC before, so we succeeded in making that many people aware of KTC!! (A bit of a stretch) Comparing before and after the event, the number of followers of our in-house X account increased slightly. The number of pageviews and unique users on our corporate website and tech blog were slightly higher than usual on the day of the event. However, we were able to see that it definitely had an effect, even if only a little, so we will continue to measure and improve from the second time onwards! Announcement website preparation Summary We opted for connpass as the medium for announcing the event, and prepared an information page about it. We learned about what kinds of events are popular from the top-ranking ones, and implemented our findings for our own event. connpass itself is a service that lets you to create events extremely easily, so creating the page was no struggle at all. This enabled us to put all the more thought into setting the target and deciding what message to convey. Thoughts Seeing as it was going to be the first event we had ever held, we were terrified of getting zero participants... So, we resolved to create the best page that we could at the time. What we did and thought First, we submitted an internal application to use an external service. If it is the first time a business is doing business with/using the service, it is necessary for the relevant department to check, but I cleared this without any problems. Then, we decided on a management method for making the application. After briefly defining the purpose of management, the objects to be managed, and the purpose of use, we designated the system and account administrators, and then simply determined the specific account management method. Once our application was approved and we could actually start working with connpass, first of all, we identified and checked out all the configurable items. This is because we wanted to leave it as a guide for holding future events, and also because we wanted to see if there were any irreversible settings. As a result of checking the items within the scope of an offline event with no participation fee, we found that the following two were the only ones that were unchangeable or restricted. Group: Unchangeable. Participation details and participation slots: Participation slots can be deleted only while there are no applicants . Most of the items were changeable. However, if the date, time, or venue were to change, participants would be confused, so I think it's better to add, but not change or delete. In addition to checking the specifications for the event information page, we also analyzed the popular events. We looked at the event rankings on connpass and picked out around 20 events that had the same attributes as our own and were extremely popular for some reason. We looked at them one by one, extracted and abstracted the elements that we felt were important, and applied them to our event information page. Now that we knew the specifications and points to consider, we once again solidified the basic design. Before we could move on to the detailed design of the "Event Information Page," we first clarified the purpose of the study session and verbalized the following: 1) the target users, 2) the message, and 3) the basic rules for communication. (1) The target users We set the target to be corporate engineers who are actively into study sessions. We provisionally set the needs “Want to know about case studies from other companies” and “Want to connect with outside info sys people,” and created wording for the event information page in relation to those. (2) Message We opted for a message along the lines of “Let’s talk candidly about how other companies do info sys!” Wanting to spread study session culture is the theme of KINTO Technologies MeetUp!, and we want to convey our own ideas and so on, and hear other people’s as well. In order to achieve that, we wanted to provide the framework of a roundtable discussion, and create a forum where people would be able to talk to each other free from the distinction of internal versus external. (3) Basic rules for communication We made it a rule that the event should be a forum for input and output as means of studying. We firmly suppressed any thoughts like “Well, since we have gotten them to come, it would be a shame not to advertise KTC’s business, recruitment, and what makes it so great...,” and thoroughly stayed true to the concept of “a study session for info sys people by info sys people.” When it came time to open the event to the public, from a technical standpoint, we decided to start with a low capacity and then increase it if necessary. It seems that there is a lot of last minute demand for tickets that are at the very limit. It's not embarrassing if there are few applications (important) Results This is how it turned out: The first KINTO Technologies MeetUp! event’s connpass page Our takeaways from looking at popular pages were the following: People are more likely to attend if it is clear who the event is aimed at and what they will gain from participating. People are more likely to come an event if it seems safe. Famous companies and people, etc. Having images and videos that show the atmosphere of past events might also be good. Hot topics (for example, ChatGPT) seem to be a draw for people. We also used notification emails to remind people just before the day. If there is a gap between the announcement and the event itself, we recommend giving people a well-timed reminder about it. This will also serve to keep the participants and operation people motivated. Coordinating the Session Overview Here's a comprehensive summary of the arrangements for the day. Specifically, these included creating a timetable for the event day, planning the roundtable discussion and deciding the venue layout, compiling the presentation materials, and managing the event’s progress. Although it was our first event, all of our staff proactively looked for work, and as a result, we were able to complete the event without any major issues and have a great time! The key point It was our first-ever event Actions/Things to consider Creating a timetable for the event day Planning the roundtable discussion and deciding the venue layout Compiling the presentation materials Managing the event’s progress Execution result We were able to complete the event without any major issues. As it was our first event, and we had no idea what would happen, all the staff were on edge with adrenaline. I think the event was a success precisely because each and every staff member actively looked for jobs that were not even someone’s role and tasks that were not even tasks! Preparation of the Case Study Presentation Materials by the Speakers Case study presentations were going to be the main feature of this study session. Since the speakers-to-be had varying levels of experience of taking the stage at study sessions, after broadly deciding on the process for preparing the materials, we met up periodically to make sure no one is left behind as we proceeded with the work. Making the slide templates uniform Based on the judgment that the presentation materials should look organized, we decided to use uniform templates. Slide templates for in-house use already existed, so we were able to agree on this matter smoothly. Setting deadlines that would serve as milestones Setting a deadline that was right before the last minute would lead to uneven progress from person to person, so instead, we split up the process of creating the materials based on the following milestones, and used these to keep everyone on schedule. Initial short-term deadline: We set a rough deadline of “in two weeks’ time,” and checked up on everyone then. Show-each-other meeting: We held a meeting to check each other’s progress on creating the materials, stipulating that while no one would be told off for falling behind, they would certainly be urged to get a move on. Review by the vice president: We set a deadline for the finished versions, with a view to getting the go-ahead from the vice president in advance. Pre-rehearsal: We held a rehearsal among the presenters a week before the event, to get the presentations even more polished. As a result, in the final pre-rehearsal, everyone had virtually finished their preparations in terms of getting their materials complete and staying withing the allotted time, and we could now look forward to the event day with peace of mind. Lastly Thanks to the organizing staff working so proactively, we were able to make it to the event day like this without a hitch. I think this is a case study that truly embodies the philosophy of “ One Team, One Player ” that we champion as our working stance. Thank you to everyone who took part, and to everyone who got involved on the operation side as well! In addition to this Tech Blog article, at a later date, we are planning to release one that talks about the event from the operation staff’s perspective and one about the case study presentations by the speakers. Please do check those out as well!
Introduction Hello! I am a team member of the KINTO Technologies study session organizing staff. The other day, we held a case study presentation and roundtable discussion session specializing in the field of corporate IT, under the title “ KINTO Technologies MeetUp! Sharing Four Case Studies for Information Systems People by Information Systems People .” Before the study session was held, a previous article on this topic talked about the steps from planning to launching by the organizing staff. In this article, by way of a sequel to that one, I would like to tell you about the various things the organizing staff did in the run-up to holding it. Following the previous session, we hope this will serve as a helpful reference for those looking to start and promote study sessions from scratch within their own organization. The previous article mainly covered the following: Planning the study session Calling for organizing staff members and speakers Discussing the matters still pending Dividing up roles and starting up agile progress management Now, I would like to delve deeper into things like what kinds of roles there were specifically, and what kinds of activities each of them entailed. Preliminary Reporting to Management This study session will be conducted as a "company activity" rather than "by individuals or volunteers". To get the appropriate support from the company, it is extremely important to report to management and get their understanding and advice regarding the activities. Therefore, this time we have decided to report in advance to the management team in the following manner. Reporting to the vice president (who is also the CIO and CISO): First of all, asking about the “holding of the event” itself, and asking for support Reporting to the president: Asking about the objectives, KPIs, equipment to be used, and budget Of course, when it comes to reporting, it is necessary to "set up a place for the report and make preparations in advance." However, by adopting the following format, we were able to carry it out relatively inexpensively. Reporting to the vice president Timing of implementation: Utilize the regularly scheduled departmental report meetings to provide updates. Report materials: We used the original plan document virtually as is, and provided details about the budget at a later date. Reporting to the president Timing of implementation: Report during the regular recruitment team briefing session Report materials: We summarized the plan document in three slides, and gave a simple report based on three points: an overview, the objectives, and the budget. As a result, we received positive responses in both cases, such as "Let's give it a try." Venue Arrangements At KINTO's Muromachi office, there is a photogenic spot called "KINTO TOKYO Junction (commonly known as the Junction)" that is always used for company introductions and external announcements. There is no reason not to use this photogenic spot when holding your first study session. Venue arrangements Junction bears the name of KINTO but is in fact owned by the parent company, Toyota Financial Services. For official use, permission from the parent company is required. However, a request can be made with just an email, and generally approval is given. We got the green light to use it for this event without any problems, too. Building arrangements The venue is a building with a security gate, so we needed to set up a reception desk outside the security gate to welcome outside guests. We notified the building management in advance and asked if we could place a desk there. This was also approved without any problems. Also, when we got permission from the building, we discovered that the automatic doors leading to the entrance were locked outside of business hours (after 6pm) (they can be unlocked from the inside, but an ID card is needed to enter from the outside). We asked the building management how to deal with this, and they agreed to install a small sign. Consultation is vital, right? Venue layout We were given permission to use the facilities, so all that was left was to decide how to lay out the venue! We had initially planned to use several large monitors for the presentation, but then we discovered a projector screen and decided we wanted to use a projector! However, we lacked the all-important projector for that, so we decided to procure one in a hurry, with a view to using it in future as well. (Everyone acted as one team wonderfully for this, too.) Wanting the layout to make the projector the main feature and encourage as many people as possible to take part as much as possible, this is what we came up with: Arrangements for the desks and chairs We used the desks and chairs that were originally there at Junction, but they were not enough on their own... So, we gathered up desks and chairs that could be used within the company. We mainly borrowed desks and chairs from the break space and were able to secure the required number of desks and chairs. On the day On the day, all the operation staff readily sprang into action, and we managed to get everything set up very quickly! The tidying up was also done really quickly, and this gave me a strong “one team” feeling, too. Everyone was amazing! Finally Inviting guests from outside to Junction was also a first for a company event, too. Throughout it all, everyone pulled together as one team to make the company look as good as possible to as many people as possible. We plan to carry on holding more study sessions as an organization in the future, too. To that end, we intend to use the results of this one to make them even smoother to enjoy! Snack Arrangements We decided to hold a social gathering as part of the study session And when it comes to social gatherings, snacks are a must. Right, time to prepare those! Snacks! The classic choice for a study session is pizza. It has been the most frequently provided food at the study sessions I've attended, leaving a strong impression on me We really wanted to make an impact right from the get-go, but since it was a first for everyone, we could not do anything over-the-top. So, we sensibly opted for pizza. Calories are right and just. And if there is pizza, there has to be cola. We were thinking that having these two would do the trick, but we were told from on high to provide some other drinks besides, so we prepared some alcoholic ones as well. How much should we provide? — Pizza — We had never paid any mind to how much there had been at the other study sessions we had taken part in up to then. How much would do...? The L-size pizza we were thinking of offering is 12 slices, and generally serves three to four people. This time, it's treated as a "light meal," so we decided to treat it as 5 people per slice. Even in the study sessions I've attended, people usually eat about 2 slices. We also took that personal experience into account. In the end, we arranged 10 pizzas for 50 people, thinking of a maximum of 40 participants plus the 10 operation staff. How much should we provide? — Drinks — For this, too, we also based the calculation on personal experience. Figuring that we usually drank around two or three cans per event ourselves...we decided to get three cans per person. The breakdown we decided on was to provide alcoholic drinks and soda in the ratio 1:1. Assuming 40 participants, that meant arranging 120 drinks. However...plastic bottles would be handier for the soda. So, we switched to those, and also ended up ordering 48 (two boxes of 24), because it was a convenient quantity in terms of placing an order. We prepared a total of 60 alcoholic drinks. Together with the 48 bottles of soda, this gave a grand total of 108 drinks. When should we arrange them by? We arranged the pizza the day before and the drinks three days before. We took delivery of all of them without any trouble. What were the results like? Pizza: None left over Alcohol: Eight left over → 52 consumed Soda: 21 left over → 27 consumed There were around 20 participants on the day, and the results were as above. This includes the food and drinks consumed by the staff on the day as well. In terms of the pizza, I feel there was not enough (because the operation staff did not get to have any of it). This is because the format of the social gathering was a "roundtable discussion" with KTC staff, and the time spent listening to each other was long, which meant more time spent eating. That is our analysis. Also, in terms of the drinks, we think the alcohol was just right, but our impression is that there was too much soda. Some people said they wanted tea, so we felt it would have been better to provide that instead of soda. In conclusion This was our first time providing snacks at a study session. So, while there were many things we were not sure about, I think we somehow managed to provide them without incurring any major dissatisfaction. We hope to provide them in a better way the next time we hold the session! Producing a Novelty Item HOS-PI-TAL-I-TY KINTO Technologies is a new company that was established in April 2021. Also, the format for holding this event was offline, which means people needed to come all the way to the venue at our company. There would be snacks and drinks like the ones mentioned above as well, but to make the effort even more worthwhile, we wanted to prepare something for everyone to: take home with them and remember the company by. To that end, we decided to produce a novelty item. How to make it happen? The members of the organizing staff discussed the matter together, and the unanimous result was, “Let’s make a novelty item!” And so, a team was launched to produce one. 1. What to make? The first thing we did was to decide what kind of novelty item to make. Of course, there were budgetary constraints as well, and when batting ideas around, we also pictured the kinds of people we were anticipating would attend.  Part of the materials we used to bat ideas around As a result, we decided to make a sticker this time! Lessons learned: It's important to ground your endless thoughts in a practical place. 2. How to make it? We had decided to make the item a sticker. We had a track record of making stickers for other in-house events, so we consulted with the design department, who have the know-how, about the purpose of the event, and with the corporate engineer about the expected attributes and interests of the visitors, and this is what we came up with! Ta-da! Based on these two patterns, we discussed which one would yield the most value as a novelty item for this event. As a result, we decided to go with the white-background, corporate-colors version! How it turned out Then, we steadily proceeded with placing the order and settling the payment, and awaited the delivery... Ta-da! (For the second time.) Production was completed without a hitch in time for the event! We hope that this novelty created with a one-team spirit spanning various departments will go on to be used in many places in the future as well, and help people know about KINTO Technologies. Promotion and Measurement Summary We thought about how to measure the results of this study session and how to announce the event itself. With the aim of gathering material for reporting to the company and indicators for doing kaizen (continuous improvement), we promoted the event as much as possible while measuring the influx into it and the impact of the event itself. We will share what we actually did, what we thought, and the results of our implementation. Background The first thing we thought about was reporting the results to the company. We had said that the study session would raise awareness of KTC, so for reporting its results to the company, we needed to gather data to show how well it had done so (the number of participants being a prime example). And since we wanted to hold the study session itself a second and third time as well, we figured we would need to have indicators for doing kaizen . Above all, since this was the first study session we held for outside the company, we honestly had no idea how many people would attend. To do our utmost to avoid winding up with zero participants, we tried out as many announcement methods as we could. In the end, we roughly settled on collecting the following indicators. Which channels had there been influx from, and how much? How much had the study session raised awareness of KTC? What we did and thought In order to visually represent what indicators we wanted, first, we wrote down the structure of the influx. Since we decided to accept entries to the event via connpass, we measured the influx into that. We also decided to measure how well the study session and roundtable discussion had helped raise awareness. Since it was an info sys event, we decided to announce it on the info sys Slack. In addition, since KTC has a Tech Blog and X (formerly Twitter) account, we asked the team operating those to announce it as well. We also used the in-house Slack to call on all employees to spread the word about it via social media. As results of the study session and roundtable discussion, we decided to prepare an X hashtag and pick up the number of posts and impressions that had it. Also, we decided to run a survey asking people if they had already known about KTC, measure the percentage who had not, multiply that by the total number of impressions, and use the result as a half-forceful way to measure the reach among people who had not known about the company before. Finally, after the event, we decided to measure how the influx and following on our company’s X account, corporate website, and Tech Blog changed, and how they changed from before the event to after it. Results Many people cooperated with spreading the word, and a total of 56 people applied to take part, so the capacity of 40 was filled up. On the day, 31 people actually came! The influx per channel for connpass was as follows: Up to the day of the event, there were 61 posts on X, and a total of 28,608 impressions. Of these, 376 were accessed, so 1.31% of the people who had viewed us on X had come to our connpass. Our survey revealed that 39% of the event participants had not originally known about KTC. If we apply this to the 1,356 visitors to connpass, that means that 39% = about 530 people did not know about KTC before, so we succeeded in making that many people aware of KTC!! (A bit of a stretch) Comparing before and after the event, the number of followers of our in-house X account increased slightly. The number of pageviews and unique users on our corporate website and tech blog were slightly higher than usual on the day of the event. However, we were able to see that it definitely had an effect, even if only a little, so we will continue to measure and improve from the second time onwards! Announcement website preparation Summary We opted for connpass as the medium for announcing the event, and prepared an information page about it. We learned about what kinds of events are popular from the top-ranking ones, and implemented our findings for our own event. connpass itself is a service that lets you to create events extremely easily, so creating the page was no struggle at all. This enabled us to put all the more thought into setting the target and deciding what message to convey. Thoughts Seeing as it was going to be the first event we had ever held, we were terrified of getting zero participants... So, we resolved to create the best page that we could at the time. What we did and thought First, we submitted an internal application to use an external service. If it is the first time a business is doing business with/using the service, it is necessary for the relevant department to check, but I cleared this without any problems. Then, we decided on a management method for making the application. After briefly defining the purpose of management, the objects to be managed, and the purpose of use, we designated the system and account administrators, and then simply determined the specific account management method. Once our application was approved and we could actually start working with connpass, first of all, we identified and checked out all the configurable items. This is because we wanted to leave it as a guide for holding future events, and also because we wanted to see if there were any irreversible settings. As a result of checking the items within the scope of an offline event with no participation fee, we found that the following two were the only ones that were unchangeable or restricted. Group: Unchangeable. Participation details and participation slots: Participation slots can be deleted only while there are no applicants . Most of the items were changeable. However, if the date, time, or venue were to change, participants would be confused, so I think it's better to add, but not change or delete. In addition to checking the specifications for the event information page, we also analyzed the popular events. We looked at the event rankings on connpass and picked out around 20 events that had the same attributes as our own and were extremely popular for some reason. We looked at them one by one, extracted and abstracted the elements that we felt were important, and applied them to our event information page. Now that we knew the specifications and points to consider, we once again solidified the basic design. Before we could move on to the detailed design of the "Event Information Page," we first clarified the purpose of the study session and verbalized the following: 1) the target users, 2) the message, and 3) the basic rules for communication. (1) The target users We set the target to be corporate engineers who are actively into study sessions. We provisionally set the needs “Want to know about case studies from other companies” and “Want to connect with outside info sys people,” and created wording for the event information page in relation to those. (2) Message We opted for a message along the lines of “Let’s talk candidly about how other companies do info sys!” Wanting to spread study session culture is the theme of KINTO Technologies MeetUp!, and we want to convey our own ideas and so on, and hear other people’s as well. In order to achieve that, we wanted to provide the framework of a roundtable discussion, and create a forum where people would be able to talk to each other free from the distinction of internal versus external. (3) Basic rules for communication We made it a rule that the event should be a forum for input and output as means of studying. We firmly suppressed any thoughts like “Well, since we have gotten them to come, it would be a shame not to advertise KTC’s business, recruitment, and what makes it so great...,” and thoroughly stayed true to the concept of “a study session for info sys people by info sys people.” When it came time to open the event to the public, from a technical standpoint, we decided to start with a low capacity and then increase it if necessary. It seems that there is a lot of last minute demand for tickets that are at the very limit. It's not embarrassing if there are few applications (important) Results This is how it turned out: The first KINTO Technologies MeetUp! event’s connpass page Our takeaways from looking at popular pages were the following: People are more likely to attend if it is clear who the event is aimed at and what they will gain from participating. People are more likely to come an event if it seems safe. Famous companies and people, etc. Having images and videos that show the atmosphere of past events might also be good. Hot topics (for example, ChatGPT) seem to be a draw for people. We also used notification emails to remind people just before the day. If there is a gap between the announcement and the event itself, we recommend giving people a well-timed reminder about it. This will also serve to keep the participants and operation people motivated. Coordinating the Session Overview Here's a comprehensive summary of the arrangements for the day. Specifically, these included creating a timetable for the event day, planning the roundtable discussion and deciding the venue layout, compiling the presentation materials, and managing the event’s progress. Although it was our first event, all of our staff proactively looked for work, and as a result, we were able to complete the event without any major issues and have a great time! The key point It was our first-ever event Actions/Things to consider Creating a timetable for the event day Planning the roundtable discussion and deciding the venue layout Compiling the presentation materials Managing the event’s progress Execution result We were able to complete the event without any major issues. As it was our first event, and we had no idea what would happen, all the staff were on edge with adrenaline. I think the event was a success precisely because each and every staff member actively looked for jobs that were not even someone’s role and tasks that were not even tasks! Preparation of the Case Study Presentation Materials by the Speakers Case study presentations were going to be the main feature of this study session. Since the speakers-to-be had varying levels of experience of taking the stage at study sessions, after broadly deciding on the process for preparing the materials, we met up periodically to make sure no one is left behind as we proceeded with the work. Making the slide templates uniform Based on the judgment that the presentation materials should look organized, we decided to use uniform templates. Slide templates for in-house use already existed, so we were able to agree on this matter smoothly. Setting deadlines that would serve as milestones Setting a deadline that was right before the last minute would lead to uneven progress from person to person, so instead, we split up the process of creating the materials based on the following milestones, and used these to keep everyone on schedule. Initial short-term deadline: We set a rough deadline of “in two weeks’ time,” and checked up on everyone then. Show-each-other meeting: We held a meeting to check each other’s progress on creating the materials, stipulating that while no one would be told off for falling behind, they would certainly be urged to get a move on. Review by the vice president: We set a deadline for the finished versions, with a view to getting the go-ahead from the vice president in advance. Pre-rehearsal: We held a rehearsal among the presenters a week before the event, to get the presentations even more polished. As a result, in the final pre-rehearsal, everyone had virtually finished their preparations in terms of getting their materials complete and staying withing the allotted time, and we could now look forward to the event day with peace of mind. Lastly Thanks to the organizing staff working so proactively, we were able to make it to the event day like this without a hitch. I think this is a case study that truly embodies the philosophy of “ One Team, One Player ” that we champion as our working stance. Thank you to everyone who took part, and to everyone who got involved on the operation side as well! In addition to this Tech Blog article, at a later date, we are planning to release one that talks about the event from the operation staff’s perspective and one about the case study presentations by the speakers. Please do check those out as well!
はじめに Flutterのマルチパッケージプロジェクトでは、アセット管理、特にローカルJSONファイルの読み込みが課題となることがあります。 通常のシングルパッケージプロジェクトとは異なるアプローチが必要となり、開発者を悩ませることがあります。 この記事では、Flutterのマルチパッケージプロジェクトにおいて、ローカルのJSONファイルを効果的に読み込む方法について詳しく解説します。 この記事は KINTOテクノロジーズアドベントカレンダー2024 の23日目の記事です🎅🎄 今回用意したテストプロジェクト 今回、調査のため、マルチパッケージで管理する簡潔なプロジェクトを用意しました。 このプロジェクトは、以下のような構成になっています。 🎯 Dart SDK: 3.5.4 🪽 Flutter SDK: 3.24.5 🧰 melos: 6.2.0 ├── .github ├── .vscode ├── app/ │ ├── android/ │ ├── ios/ │ ├── lib/ │ │ └── main.dart │ └── pubspec.yaml ├── packages/ │ ├── features/ │ │ ├── assets/ │ │ │ └── sample.json │ │ ├── lib/ │ │ │ └── package1.dart │ │ └── pubspec.yaml │ ├── .../ ├── analysis_options.yaml ├── melos.yaml ├── pubspec.yaml └── README.md Assetにあるファイルを読み込む 一般的なシングルパッケージでのAssetの読み込みは、以下のようにすればできるという説明はよく見かけます。 flutter: assets: - assets/ # アセットフォルダを指定 import 'package:flutter/services.dart' show rootBundle; Future<String> loadAsset() async { return await rootBundle.loadString('assets/sample.json'); } 公式も同じ様な説明をしています。 https://docs.flutter.dev/ui/assets/assets-and-images 実際にAssetからJSONファイルを読み込んでTextにString表示するだけのWidgetを作ってみました。 import 'dart:convert'; import 'package:flutter/material.dart'; import 'package:flutter/services.dart' show rootBundle; class LocalAssetPage extends StatefulWidget { const LocalAssetPage({super.key}); @override LocalAssetPageState createState() => LocalAssetPageState(); } class LocalAssetPageState extends State<LocalAssetPage> { String _jsonContent = ''; @override void initState() { super.initState(); _loadJson(); } Future<void> _loadJson() async { final response = await rootBundle.loadString('assets/sample.json'); final data = await json.decode(response); setState(() { _jsonContent = json.encode(data); }); } @override Widget build(BuildContext context) { return Scaffold( appBar: AppBar( title: const Text('Local Asset Page'), ), body: Center( child: _jsonContent.isEmpty ? const CircularProgressIndicator() : Text(_jsonContent), ), ); } } しかし、マルチパッケージでのAssetの読み込みは、この方法ではうまくいきません。 🤨 flutter_genを使ってAssetを読み込む 大抵の場合、マルチパッケージでのAssetの読み込みは、flutter_genを使って解決できます。 flutter_genは、AssetやLocalization等のパスからコード生成をして、タイプセーフにアセットの読み込みが実現できるツールで、マルチパッケージのAssetの読み込みもサポートしています。 https://github.com/FlutterGen/flutter_gen flutter_genでマルチパッケージのAssetを読み込むには、以下の設定が必要になります。 flutter_gen: assets: outputs: package_parameter_enabled: true この設定を入れて、flutter_genを実行すると、マルチパッケージのAssetを読み込むためのコードが生成されます。 そこで生成されたコードを使ってタイプセーフにAssetを読み込むことができます。 上記の例をflutter_genを使って書き換えると、以下のようになります。 import 'package:{YOUR_PACKAGE_NAME}/gen/assets.gen.dart'; Future<String> loadAsset() async { return await rootBundle.loadString(Assets.sample); } 実際に以下の様なコードを書くことで、マルチパッケージのAssetを読み込むことができます。 import 'dart:convert'; + import 'package:feature_flutter_gen_sample/gen/assets.gen.dart'; import 'package:flutter/material.dart'; import 'package:flutter/services.dart' show rootBundle; class FlutterGenSamplePage extends StatefulWidget { const FlutterGenSamplePage({super.key}); @override FlutterGenSamplePageState createState() => FlutterGenSamplePageState(); } class FlutterGenSamplePageState extends State<FlutterGenSamplePage> { String _jsonContent = ''; @override void initState() { super.initState(); _loadJson(); } Future<void> _loadJson() async { + final response = await rootBundle.loadString(Assets.sample); - final response = await rootBundle.loadString('assets/sample.json'); final data = await json.decode(response); setState(() { _jsonContent = data.toString(); }); } @override Widget build(BuildContext context) { return Scaffold( appBar: AppBar( title: const Text('FlutterGen Sample'), ), body: Center( child: _jsonContent.isNotEmpty ? Text(_jsonContent) : const CircularProgressIndicator(), ), ); } } ファイルのパスが構造化されるので、とてもキレイですね! チーム開発のAsset管理はこれで安心です。 ですが、なるべくツールに頼らない方法を取りたい場合も多々ありますよね? 次はその方法についてもお話します。 flutter_genを使わないでAssetを読み込む flutter_genを使わずにマルチパッケージのAssetを読み込む方法ももちろんあります。 その場合は、以下のルールでパスを指定することでAssetを読み込むことができます。 :::message packages/ {パッケージ名} / {フォルダパス} /ファイル名 ::: パッケージ名 は、そのassetが格納されているPackageのpubspec.yamlのnameに指定した名前になります。 フォルダパス は、そのPackageのpubspec.yamlのassetsに指定したパスになります。 name: local_asset ... flutter: assets: - assets/ import 'dart:convert'; import 'package:flutter/material.dart'; import 'package:flutter/services.dart' show rootBundle; class LocalAssetPage extends StatefulWidget { const LocalAssetPage({super.key}); @override LocalAssetPageState createState() => LocalAssetPageState(); } class LocalAssetPageState extends State<LocalAssetPage> { String _jsonContent = ''; @override void initState() { super.initState(); _loadJson(); } Future<void> _loadJson() async { + final response = await rootBundle.loadString('packages/local_asset/assets/sample.json'); - final response = await rootBundle.loadString('assets/sample.json'); final data = await json.decode(response); setState(() { _jsonContent = json.encode(data); }); } @override Widget build(BuildContext context) { return Scaffold( appBar: AppBar( title: const Text('Local Asset Page'), ), body: Center( child: _jsonContent.isEmpty ? const CircularProgressIndicator() : Text(_jsonContent), ), ); } } このようにして、flutter_genを使わずにマルチパッケージのAssetを読み込むことができます。 小規模プロジェクトや、個人開発ではこの方法でも十分に対応できそうです。 このパスの作成ルールが理解できておらず、ファイルの相対パスを指定したり、パスの設定を色々工夫してみたりしましたが、 そもそもエラーでビルドできなかったりととても苦戦しました... pubspec.yamlで指定するパスについて ローカルでアセットを管理する時に、pubspec.yamlで指定するパスについても注意が必要です。 assetsのパスは、pubspec.yamlからの相対パスで指定しますが、 /assets と /assets/{サブフォルダ} の扱いにも注意が必要です。 以下の様にJSONファイルをサブフォルダに移動した場合、 ├── packages/ │ ├── features/ │ │ ├── assets/ │ │ │ └── jsons/ │ │ │ └── sample.json <<< HERE │ │ ├── lib/ │ │ │ └── package1.dart │ │ └── pubspec.yaml │ ├── .../ 僕はてっきり /assets と指定すれば、 /assets/{サブフォルダ} 以下のファイルも読み込めると思っていましたが、 loadStringのパスを packages/local_asset/assets/jsons/sample.json に変更しても読み込めなくなります。 サブフォルダに移動した場合は、以下の様にサブフォルダを明示的に指定する必要があります。 flutter: assets: - /assets/jsons/ これで、 packages/local_asset/assets/jsons/sample.json をロードできる様になりました。 サブフォルダで細かくアセットを管理するのであれば、サブフォルダの指定もpubspec.yamlに追加するのを忘れない様にしないといけません。 ちなみに、ここまで assets フォルダで話をしていましたが、このフォルダ名も変更できます。 pubspec.yamlと実際のパス構成が合っていれば、 assets フォルダ以外でも問題なく読み込めます。 まとめ 今回はFlutterのマルチパッケージの中でローカルのJSONを読み込む方法についてお話しました。 普段はiOSの開発がメインなので、簡単にできるだろうと思っていたのですが、意外と苦労しました。 マルチパッケージ下での開発手法はまだあまり情報がない様なので、今後もこういった情報があれば共有していきたいと思います。
こんにちは、人事グループ組織人事チームのHOKAです。 このBlogは 10X innovation culture program 内製化における苦悩と挑戦【前編】 の続きです。 8月:Google Cloud Next Tokyo'24に登壇して気づいたこと Google Cloud Next Tokyo'24とは、グーグル・クラウド・ジャパン合同会社が2024年8月1日(木)~2日(金)に開催した旗艦イベントで、ビジネスリーダー、イノベーター、エンジニアのためのクラウドカンファレンスです。生成AIやセキュリティをはじめとするビジネスに欠かせないテーマをもとに、基調講演やライブセッション、ハンズオンなどさまざまなプログラムが用意されていました。 詳細はこちら→ https://cloudonair.withgoogle.com/events/next-tokyo-24 KTCからは開発支援部 部長のきっしーとDBREグループ マネージャーのあわっちが「10X Innovation Culture Program 体験ワークショップ」に登壇しました。ワークショップ参加者の皆様に10X Innovation Culture Programを導入している事例をお話する機会をいただいたのです。 本番までには何度も打ち合わせをし、Google オフィスでリハーサルをし、ランチもご一緒させていただき、Googleの方々と接する時間が増えました。 そして迎えた本番。 パシフィコ横浜の広い会場における非日常感が「今日は学ぶぞ」という気持ちを醸成させてくれます。 初めに、Googleの方から10X についてご案内しました。なぜGoogleが10X innovation culture programを社内外で推進しているか、その背景や理由、結果を「生きた言葉」で話してくださり、会場にいたKTCのメンバーは「10XはやはりKTCにも必要だ!!!」と士気が上がりました。 続いて、きっしーとあわっちが登壇しました。 きっしーとあわっちからは下記3つについてお話しました。 カルチャー変革に取り組んだ背景、なぜ 10X Innovation Culture Program を実施することになったのか 10X Innovation Culture Program を実際にやってみて、実施する上でのポイント 今後の展開について 特に、10X Innovation Culture Program を実施しながら感じている 「Google だからできる」という思い込みを捨て、深く考えずにまずはやってみることが大事 ボトムアップから社内自立化の実現に向けた社内ファシリテーターの育成が重要 カルチャーは一足飛びではなく、何度も気づき、体験して浸透していくもの ということをKey Messageとして会場で伝えました。 質問タイムではたくさんの方がKTCに質問してくださり、「10Xは素晴らしい。しかし、導入するのは難しくないのか?」という疑問を投げかけてくださいました。まだ10X innovation culture programによる大きな効果は見えないものの、私たちの取り組みが少しでも参考になっていれば幸いです。 Google Cloud Next Tokyo’24に参加して、私は7月に自分たちで手作りした10X innovation culture programと圧倒的な違いを感じました。それは オフィスとは別の会場で参加者の聞く体制の準備が整う Googleの社員によって語られる「10X」は、とても心に響く ディスカッションメインの場と思っていたが、もっとインプットメインでも良いのかもしれない。 その上で、「10Xの考えを日々の業務に取り入れたい」と変わるのかもしれない。 ということでした。上記を仮説として、秋に開催する10X innovation culture programで検証していくことが定まりました。 9月:10Xファシリテーター研修を受けてみた まず、私たちは10Xの理解およびディスカッションをスムーズにさせるファシリテーターの育成から着手することにしました。私たちが立てた仮説 Googleの社員によって語られる「10X」は、すごく浸透する ディスカッションメインの場と思っていたが、もっとインプットメイン を紐解くと、10Xを運営する側が「10Xとは何か」のインプットが少ないから、相手に伝わらないと思ったからです。 思い切って、Googleの方に相談したところ、ファシリテーター研修を実施していただける運びとなりました。 ファシリテーター研修を実施するにあたり、メンバー選出で悩みましたが、そもそも10X innovation culture programはリーダーシッププログラムなので、マネージャーに受講いただくことにしました。 ファシリテーター研修当日 今回の研修のメイン担当であるGoogleのKotaさんから、研修の冒頭で 「めちゃくちゃスパルタです。1回言ったことを覚えて、話せるようにする研修です。 Googleで大切にされている言葉 Steal with pride(プライドを持って盗もう) Feedback is a gift!(フィードバックは贈り物) を体感する構成となっております。 Googleの社員よりも10Xについて濃密な時間を過ごします。」 というメッセージをいただきました。 一体、何が始まるのか?という空気感で、研修は幕を開けました。 【研修前半】インプット Kotaさのメッセージにあった通り、初めにGoogleの方から10Xの6つの要素をプレゼンテーションし、KTC社員が理解する「インプットの時間」がありました。 例えば、ひとつ目の要素「DEI」について。 Googleでは Unconscious Bias @ Work という無意識の偏見に目を向ける研修を社員の50%が受講済。 週に一度の意識調査: Googlegeist を行い、ダイバーシティの受け入れや公平性に関する成果を測定している。 といった具体的な施策と、それによる効果についてお話いただきました。 同様に、10Xの6つの要素ひとつひとつに、Googleにおける具体的事例と、プレゼンターご自身が社員として感じていることやエピソードを交えて話してくださいました。 【研修後半】アウトプット Googleの方のプレゼンテーションを聞いた後、KTCのメンバーは6人1グループに分かれました。 そして、1人1要素を暗記し、自分のエピソードを交えてプレゼンテーションをしました。 プレゼンテーションを聞く人は聞いているだけではなく、1人ずつプレゼンテーションの良かったところや改善点をフィードバックしていきました。Googleの方からもフィードバックをいただきました。 このプロセスは、冒頭にKotaさんが仰ったとおり「スパルタ」かもしれませんが、Googleのやり方を「Steal with pride」し、「Feedback is a gift」する時間でした。 また、フィードバックの内容も 「もっと全社でビジョン共有した方が良いね」 「目標設定、どうなってんでしたっけ?」 「もっと事例を言えるようになりたい。経営者との接点を増やそう!」 など、どんどんアイデアが生まれて来ました。 10Xをインプットしたことで、「KTCの今」と照らし合わせることができるようになった瞬間に立ち会うことができました。 実際に、ファシリテーター研修を受けたKTCのメンバーから「今まで10Xを素晴らしいものとは思いつつも、どこか他人事だったが、研修を通して短時間で暗記し、自分のエピソードと絡め、他者にプレゼンテーションすることで一気に自分のものにすることが出来ました」というコメントが多数寄せられました。 また、その場でGoogleの方からフィードバックをもらえたのも貴重な機会だったと思います。 10月:3回目の10X innovation culture programに向けて準備中 ファシリテーター研修を終え、3回目の10X innovation culture program準備中(10月)にこのBlogを書きました。 3回目の10X innovation culture programは2日程に分かれます。新しいやり方です。 また、参加者のうち初めて参加するメンバーは47%を占めています。 前回(7月)より前のめりで参加してもらえるか? 9月のファシリテーター研修の成果は出るか? また改めてTechBlogに投稿いたします。 10X innovation culture program 内製化における苦悩と挑戦【後編】に続く ※2025年1月公開予定
1. はじめに こんにちは、共通サービス開発グループの鳥居( @yu_torii )です。主にバックエンド/フロントエンド領域を担当しています。 KINTO 会員プラットフォーム開発チームでフロントエンドエンジニアを務めながら、社内での生成 AI 活用にも携わっています。 本記事では、Slack 上で LLM を活用する社内チャットボット「しぇるぱ」の RAG や Slack リアクションを活用した翻訳機能を紹介します。 しぇるぱは、社内での生成 AI 活用を目指して開発された Slack チャットボットです。 フロントエンド開発を省略して素早く社内に展開し、社員が普段使う Slack 上で生成 AI を自然に利用できる環境を目標としています。 「しぇるぱ」という名前はエベレスト登山のガイドとして知られるシェルパ族に由来し、彼らが登山者を支える頼れる存在であるように、しぇるぱもまた社内の業務効率の向上や情報共有の円滑化のための頼れるパートナーでありたいという願いが込められています。 ちなみに、バナーの「しぇるぱ」さんはクリエイティブグループの方が KINTO テクノジーズ全体会議(KTC 超本部会)に際してサプライズで描いてくれたものです。ありがとうございます! この取り組みは、生成 AI 活用プロジェクトを推進する和田さん( @cognac_n )との協力により進められました。RAG パイプラインの導入、ローカル開発環境の整備、Slack 絵文字リアクションを活用した翻訳・要約機能など、多角的な改善を行い、社内での生成 AI 利活用を推進しています。 :::details 和田さんの記事はこちら @ card @ card @ card ::: なお、RAG や生成 AI 技術そのものの詳細解説は省き、実装や機能追加の過程を中心にまとめています。 また、しぇるぱの LLM は Azure OpenAI を利用しています。 この記事で得られること Slack Botによる生成AIを活用したチャット機能の利用方法 Slack と LLM を組み合わせ、絵文字リアクションや自然なメッセージ投稿で翻訳・要約を呼び出すチャットボット実装例を紹介 HTMLサニタイズを含むConfluenceデータ取得の工夫 Confluence ドキュメントを Go で取得し、HTML サニタイズにより要約・Embedding に適したテキストを整える方法 FAISS とS3を使った簡易的なRAGパイプライン導入 FAISS インデックスと S3 を活用した簡易 RAG パイプライン導入の手順と注意点を解説 応答速度はあまり早くないものの、低コストで簡易的な RAG を組み込む際の実装ステップや注意点をまとめます。 :::message 本記事は、執筆時点での実装状況をもとにしています。改善点が多分に含まれている点をご了承ください。 社内向けのツールであるため、プロダクションレベルのパフォーマンスを必要とした実装ではありません。 AWS SAM でのデプロイや Step Functions のパイプライン構築、GitHub Actions による CI/CD など、開発環境の整備については、本記事では詳細を省略しています。 ::: :::details 目次(展開) 1. はじめに この記事で得られること 2. 全体アーキテクチャの概要 3. Slack Botによる生成AIを活用したチャット機能 「チャット機能」と「リアクション機能」 チャット機能:利用シナリオ リアクション機能:利用シナリオ この構成のメリット 3.5 実際の利用例 3章まとめ 4. 実装方針と内部設計 全体的な処理フロー 条件分岐による機能判定 サニタイズの役割 RAG利用をConfluence参照に限定 拡張性・保守性への考慮 5. コード例と設定ファイルの紹介 5.1 [Go] Slackイベント受信と解析 5.2 [Go] HTMLテキストのサニタイズ 5.3 [Python] LLM問い合わせの具体例 5.4 [Python] RAG検索呼び出し例 5.5 [Python] EmbeddingとFAISSインデックス化 ::: 2. 全体アーキテクチャの概要 ここでは、しぇるぱが生成 AI による回答を返すまでの流れを、「ユーザとの生成 AI チャット機能」と「Confluence ドキュメントをインデックス化する処理」という 2 つの視点で整理します。 ユーザとの生成AIチャット機能の処理 Slackでしぇるぱを呼び出す しぇるぱの呼び出し方は、チャットでの呼び出しと、リアクション絵文字での呼び出しの 2 通りがあります。 チャットでの呼び出しは、チャンネルでメンションを付けて投稿するか、ダイレクトメッセージで直接投稿することで、生成 AI による回答をリクエストできます。 リアクションでの呼び出しは、翻訳・要約用の絵文字リアクションを付けることで、そのメッセージの翻訳や要約をリクエストできます。 Go Slack Bot Lambda Slack イベントを受け取る Bot は Go で実装し、Lambda 上で動作します。 ユーザからの質問やリアクションを受け取り、リクエストの種類に応じて処理を振り分けます。 LLM へのリクエストや、Embedding 済みデータの参照など Azure OpenAI を利用する場合は、ここでリクエストを生成し、Python Lambda へ送信します。 Python LambdaでのLLMへのリクエスト・RAG参照 Python Lambda は機能ごとに分割し、LLM 問い合わせや RAG 参照などを担当します。 Go Lambda からのリクエストを受け取り、LLM への問い合わせや RAG による回答生成を行います。 Slackへの回答返送 生成された回答は、Go Slack Bot Lambda を経由して Slack へ返送します。 絵文字リアクションで呼び出す翻訳・要約機能も、このフローに組み込まれています。 :::details アーキテクチャ図(ユーザからの呼び出しに対応する処理) flowchart LR subgraph "ユーザからの呼び出しに対応する処理" A["User(Slack)"] -->|"質問・絵文字"| B["Go Slack Bot(Lambda)"] B -->|"リクエスト"| C["Python Lambda RAG/LLM"] C -->|"回答"| B B -->|"回答"| A end ::: Confluence ドキュメントをインデックス化する処理 RAG パイプラインを利用するには、Confluence ドキュメントを要約・Embedding しやすい状態に整える必要があります。これらの前処理は StepFunctions でワークフロー化し、定期的かつ自動的に実行しています。 ドキュメント取得・HTMLサニタイズ(Go実装) Go で実装した Lambda が Confluence API からドキュメントを取得し、HTML タグを整理してテキストを扱いやすい状態にします。 サニタイズ済みテキストは JSON として出力します。 要約処理(Go + Python Lambda呼び出し) 要約処理の目的は、テキストを Embedding や RAG で扱いやすい範囲に絞ることです。 Go 実装の Lambda が Azure OpenAI Chat API のリクエスト処理を行う Python Lambda を呼び出し、テキストを短く整え、再び JSON 化します。 FAISSインデックス化とS3保存(Indexer Lambda) 要約後のテキストを Embedding し、FAISS インデックスを生成する Indexer Lambda がインデックスやメタ情報を S3 へ格納します。 これにより、問い合わせ発生時にはインデックス済みデータを即座に参照でき、RAG パイプラインがスムーズに稼働します。 :::details アーキテクチャ図(Confluence ドキュメントのインデックス化フロー) flowchart LR subgraph "インデックス化準備処理 StepFunctions" D["Go Lambda(ドキュメント取得/HTMLサニタイズ)"] D --> E["Go Lambda(要約/Python呼出)"] E --> F["Indexer Lambda(Embedding/FAISS/S3)"] end ::: こうした事前処理と問い合わせ時の処理が組み合わさることで、しぇるぱは Slack 上の簡易な操作で社内特有のナレッジを反映した生成 AI 回答を返せるようになっています。 以降の章では、これらの要素についてさらに詳細を見ていきます。 3. Slack Botによる生成AIを活用したチャット機能 前章でアーキテクチャの全体像を示しましたが、本章では、ユーザが Slack 上で自然な操作を行うだけで得られる機能について、その使い方や有用性に焦点を当てます。 ここでは「何ができるか」「どんなシナリオで役立つか」という利用イメージを示し、実装詳細は次章以降で体系的に紹介します。 「チャット機能」と「リアクション機能」 しぇるぱは、Slack 上での自然な操作を原動力に、多様な生成 AI 機能を提供します。 チャット機能 : 質問を投稿したり、ファイルや画像、外部リンクを貼ったり、特定の形式でメッセージを送ることで、LLM への問い合わせや(特定の場合)RAG 検索が行われ、必要な回答が得られます。 Slack という日常的なツールに機能を統合することで、ユーザは新たな環境やコマンドを学ぶ必要なく、生成 AI を自然に日常業務へ取り込むことができます。 リアクション機能 : 特定の絵文字リアクションをメッセージに付与するだけで翻訳やしぇるぱ発言の削除などをトリガーでき、コマンドレスでの追加操作が可能になります。 チャット機能:利用シナリオ 基本的な質問・回答 普通に質問を投稿するだけで、LLM を通じて回答を取得できます。 利用シーン例: 「このプロジェクトの手順は?」と尋ねれば即座に回答が得られ、スレッド内の履歴や発言者情報を考慮して文脈に沿った応答が可能です。 ファイル・画像・外部リンク参照 ファイルを貼り付けて「要約して」と依頼すれば、ファイル内容を要約。 画像を添付すれば文字起こしや画像内容を踏まえた回答が可能。 外部リンクを貼れば、そのページ内容を整理して LLM 回答に生かせます。 利用シーン例: 会議メモが入ったテキストファイルを「要約して」で短いサマリを得る、画像内文字情報を抜き出す、外部記事リンクを要約するといった、手間を省く活用ができます。 Confluenceページ参照(RAG活用) :confluence: index:Index名 で、社内でのルールや申請方法等のドキュメントが含まれた Confluence ページを RAG 検索。 利用シーン例: 社内申請手順や内部ルールが Confluence にまとまっている場合、必要な情報を即座に引き出し、一般的な回答以上に社内事情に即したアドバイスが得られます。 利用シーン例: プロジェクト独自の手順書や設定値を検索して、その内容を回答に反映。検索しづらい情報を簡単に引き出せます。 リアクション機能:利用シナリオ 特定の絵文字リアクションを付けることで、さらに直感的な機能呼び出しが可能です。 翻訳 : 翻訳用絵文字を付ければ、そのメッセージを指定言語へ翻訳可能です。言語の壁を低くし、コミュニケーションを円滑化します。 削除 不要になったしぇるぱ発言を絵文字 1 つで簡易に削除し、チャンネルを整理できます。 この構成のメリット 自然な操作で活用可能 : ユーザは慣れた Slack 操作(メッセージ投稿、絵文字付与など)だけで生成 AI 機能を使え、学習コストを低減できます。 日常ツールへの統合で生成AI定着 : Slack という普段使うコミュニケーション基盤に機能を溶け込ませることで、生成 AI を身近に利用することが可能です。またリアクション機能は文字入力をすることなく、翻訳や削除などの操作ができるため、手軽に利用できます。 拡張に対応しやすい土台 : 今後、新たなモデルや追加機能を組み込みたくなった場合も、既存のフロー(質問投稿、絵文字操作)に条件を増やすだけで拡張可能です。 3.5 実際の利用例 ここで、しぇるぱが Slack 上でどのように使われているか、実際のシナリオをいくつか紹介します。 例1:画像の認識 メッセージに画像を添付すると、しぇるぱは画像内のテキストを認識し、その内容を回答します。  画像の認識 例2:Confluenceドキュメントに基づく回答 :confluence: という絵文字を使うことで、Confluence ドキュメントを参照した回答を得ることができます。  Confluenceドキュメントに基づく回答 ご覧の通り、しぇるぱはワークフローから呼び出すことも可能で、プロンプトストアのような利用も可能です。 例3:翻訳リアクションでの英訳依頼 ユーザが英訳したいメッセージに翻訳リアクションを付与 英語話者に共有したい日本語メッセージに :sherpa_translate_to_english: といったリアクション絵文字を付けると、そのメッセージのテキストが自動で英訳されます。  英語翻訳リアクション 翻訳内容を過信しないように、自動翻訳であることを複数言語で通知することで、誤解を防ぎます。 また、機能を普及させるために、利用方法も記載しています。 英訳の他に複数言語の翻訳機能を提供しています。 3章まとめ 本章では、「どんな操作で何ができるか」というユーザ視点の使い方に注目しました。 ここで得た利用イメージを基に、次の章以降で実装内容を体系的に示し、Go 製 Bot や Python Lambda の連携方法、Slack イベントの処理や RAG 検索のしくみ、ファイル抽出やサニタイズ処理などの詳細を紹介します。 4. 実装方針と内部設計 この章では、しぇるぱが Slack のメッセージやリアクションを通じて多様な生成 AI 機能を提供するための実装方針と内部設計について説明します。 ここで紹介するのは、あくまで全体的な考え方や役割分担、拡張性への配慮に関する部分です。具体的なコードや設定ファイルは次章以降に記載します。 全体的な処理フロー Slackイベント受信(Go Lambda) Slack で行われるメッセージ投稿、ファイル添付、画像挿入、外部リンク記載、絵文字リアクションなどのイベントは、Slack API 経由で Go 実装の AWS Lambda へ通知されます。 Go 側はこれらのイベントを解析し、ユーザが求める処理(通常のチャット、翻訳、Confluence 参照など)を判定します。 Go側でのテキスト処理・サニタイズ 外部リンクやファイルからテキストを取得し、コンテキストとしてプロンプトに追加します。 外部リンクを参照する場合は table 、 ol 、 ul など意味のあるタグは残し、不要なタグだけを除去してトークンを節約します。 Python側でのLLM問い合わせ・RAG検索 必要な場合、Go 側は LLM 問い合わせ用の Python Lambda(LLM 用)か、RAG 検索用の Python Lambda(Confluence 参照用)を呼び出します。 例えば、 :confluence: が含まれていれば RAG 検索用 Lambda を呼び出し、index が指定されていなければデフォルトインデックスで検索します。 そうでなければ通常は LLM 用 Lambda へテキストを渡し、LLM への問い合わせを行います。 回答返却とSlack表示 Python 側の Lambda が生成した回答を Go 側に戻し、Go 側が Slack へ投稿します。 これにより、ユーザはコマンドを暗記する必要なく、絵文字やキーワード、ファイル添付など日常的な操作だけで高度な機能を利用できます。 条件分岐による機能判定 特定の絵文字( :confluence: など)やキーワード、ファイルや画像の有無、外部リンク存在などにより処理を振り分けます。 新機能を追加する場合は、Go 側で新たな条件を追加して、必要なら対応する Python 側の Lambda(LLM 用、RAG 用など)を呼び出すロジックを増やすことで実現できます。 サニタイズの役割 Go 側でサニタイズし、不要な HTML タグを除去することで、モデルへ渡すテキストを効率的に扱い、トークン消費を抑えます。 table、ol、ul など意味あるタグは残して情報構造を保持し、モデルにとって有用な文脈を損ねないようにしています。 RAG利用をConfluence参照に限定 RAG 検索は :confluence: 指定時のみ利用します。 これにより通常の要約や翻訳、Q&A は LLM 直接問い合わせで済み、RAG 関連ロジックは Confluence 参照時だけ発動します。 Confluence ドキュメントの Embedding 生成や FAISS インデックス更新は StepFunctions で定期的に実行し、問い合わせ時には常に最新インデックスを利用できます。 拡張性・保守性への考慮 絵文字やキーワード、ファイル・画像の有無による条件分岐は、機能を増やす際の変更箇所を少なく保ち、保守性を高めます。 Go 側でテキスト整形やサニタイズ、Python 側で LLM 問い合わせ・RAG 検索を行う役割分担も、コードの見通しを良くし、将来的なモデル切り替えや処理追加を容易にします。 次章では、これらの方針を踏まえた具体的なコードスニペットや設定ファイル例を紹介します。 5. コード例と設定ファイルの紹介 この章では、第 4 章で説明した実装方針や設計上の考え方に基づいて、実装例を要点を絞って紹介します。 本章は次のセクションで構成します。 5.1 Slack イベント受信と解析(Go 側) Slack の Events API を用いてメッセージや絵文字リアクションなどのイベントを受信・解析する方法を示します。 5.2 Go 側でサニタイズ例 外部リンク参照した際の HTML サニタイズ処理の例を示します。 5.3 Python 側 LLM 問い合わせの具体例 LLM(LLM)への問い合わせを行う Lambda のコード例を提示します。 5.4 Python 側 RAG 検索呼び出し例 Confluence 参照など RAG を使う場合の検索呼び出し例を紹介します。 5.5 Python 側 Embedding と FAISS インデックス化 Confluence ドキュメントを定期的に Embedding し、FAISS インデックスを更新する Lambda のコード例を示します。 5.1 [Go] Slackイベント受信と解析 このセクションでは、Slack の Events API を利用して、AWS Lambda 上で Go コードでイベントを受信・解析する基本的な流れを説明します。 Slack 側での設定(OAuth & Permissions、イベント購読)や、 chat.postMessage メソッド利用時に必要なスコープ( chat:write など)の確認方法にも触れ、読者が実装を始めるまでに必要な準備を明確にします。 Slack側での設定手順 App作成とApp IDの確認 : https://api.slack.com/apps で新規 App を作成します。 作成後、Basic Information ページ( https://api.slack.com/apps/APP_ID/general 、 APP_ID は App 固有の ID)で App ID( A で始まる文字列)を確認します。 この App ID は Slack App の識別子であり、後述の OAuth & Permissions や Event Subscriptions ページの URL アクセスに用いることができます。 OAuth & Permissionsでスコープ付与 : 「OAuth & Permissions」ページ( https://api.slack.com/apps/APP_ID/oauth )にアクセスし、Bot Token Scopes に必要なスコープを追加します。 例えば、チャンネルへメッセージ投稿に chat.postMessage メソッドが必要である場合、 https://api.slack.com/methods/chat.postMessage で「Required scopes」を確認すると chat:write が必要であるとわかります。 スコープ付与後、「reinstall your app」をクリックし、ワークスペースに再インストールすると、変更が反映されます。  Required scopesの確認  Scopeの設定 Events API有効化とイベント購読 : 「Event Subscriptions」ページ( https://api.slack.com/apps/APP_ID/event-subscriptions )で Events API を有効化し、「Request URL」に後述の AWS Lambda エンドポイントを設定します。 message.channels や reaction_added など、購読するイベントを追加します。これにより、対象イベント発生時に Slack が指定 URL へ通知を送るようになります。  AWS Lambda側でのイベント受信・解析 Slack 側での設定が完了すると、購読対象のイベントが発生するたびに Slack は API Gateway 経由で Lambda へ POST リクエストを送ります。 ステップ1:Slackイベントの解析 slack-go/slackevents パッケージを用いて、受信した JSON を EventsAPIEvent へ変換します。 これにより、URL 検証や CallbackEvent などイベントタイプを判別しやすくなります。 func parseSlackEvent(body string) (*slackevents.EventsAPIEvent, error) { event, err := slackevents.ParseEvent(json.RawMessage(body), slackevents.OptionNoVerifyToken()) if err != nil { return nil, fmt.Errorf("Slackイベントの解析に失敗しました: %w", err) } return &event, nil } @ card ステップ2:URL検証要求対応 初回に Slack は type=url_verification のイベントを送ってきます。この中の challenge をそのまま返すことで Slack は URL 有効性を確認し、その後イベントを通知してくれるようになります。 func handleURLVerification(body string) (events.APIGatewayProxyResponse, error) { var r struct { Challenge string `json:"challenge"` } if err := json.Unmarshal([]byte(body), &r); err != nil { return createErrorResponse(400, err) } return events.APIGatewayProxyResponse{ StatusCode: 200, Body: r.Challenge, }, nil } @ card ステップ3:署名検証・再試行リクエスト無視 Slack はリクエスト署名を付与し、正当性を検証できます(実装は省略)。 また、障害時などに再試行リクエストが送られる場合があり、 X-Slack-Retry-Num ヘッダで再試行を判定して同じイベントを二重処理しないようにできます。 func verifySlackRequest(body string, headers http.Header) error { // 署名検証処理(省略) return nil } func isSlackRetry(headers http.Header) bool { return headers.Get("X-Slack-Retry-Num") != "" } func createIgnoredRetryResponse() (events.APIGatewayProxyResponse, error) { responseBody, _ := json.Marshal(map[string]string{"message": "Slackの再試行を無視します"}) return events.APIGatewayProxyResponse{ StatusCode: 200, Headers: map[string]string{"Content-Type": "application/json"}, Body: string(responseBody), }, nil } ステップ4:CallbackEvent処理 CallbackEvent は実際のメッセージ投稿やリアクション追加などが含まれます。ここで、 :confluence: が含まれるか、ファイルがあるか、翻訳用絵文字が付いているかなどを判定し、5.2 以降で示すテキスト処理や Python Lambda 呼び出しへ進みます。 // handleCallbackEvent は、コールバックイベントを処理します。(5.1での説明対象) func handleCallbackEvent(ctx context.Context, isOrchestrator bool, event *slackevents.EventsAPIEvent) (events.APIGatewayProxyResponse, error) { innerEvent := event.InnerEvent switch innerEvent.Data.(type) { case *slackevents.AppMentionEvent: // AppMentionEventの場合の処理(5.2で詳細説明) case *slackevents.MessageEvent: // MessageEventの場合の処理(5.2で詳細説明) case *slackevents.ReactionAddedEvent: // ReactionAddedEventの場合の処理(5.2で詳細説明) } return events.APIGatewayProxyResponse{Body: "OK", StatusCode: http.StatusOK}, nil } ハンドラ全体のコード例 これらのステップを組み合わせて AWS Lambda ハンドラを定義します。 :::details ハンドラ全体のコード例 func handler(ctx context.Context, request events.APIGatewayProxyRequest) (events.APIGatewayProxyResponse, error) { event, err := parseSlackEvent(request.Body) if err != nil { return createErrorResponse(400, err) } if event.Type == slackevents.URLVerification { return handleURLVerification(request.Body) } headers := convertToHTTPHeader(request.Headers) err = verifySlackRequest(request.Body, headers) if err != nil { return createErrorResponse(http.StatusUnauthorized, fmt.Errorf("リクエストの検証に失敗しました: %w", err)) } if isSlackRetry(headers) { return createIgnoredRetryResponse() } if event.Type == slackevents.CallbackEvent { return handleCallbackEvent(ctx, event) } return events.APIGatewayProxyResponse{Body: "OK", StatusCode: 200}, nil } func convertToHTTPHeader(headers map[string]string) http.Header { httpHeaders := http.Header{} for key, value := range headers { httpHeaders.Set(key, value) } return httpHeaders } func createErrorResponse(statusCode int, err error) (events.APIGatewayProxyResponse, error) { responseBody, _ := json.Marshal(map[string]string{"error": err.Error()}) return events.APIGatewayProxyResponse{ StatusCode: statusCode, Headers: map[string]string{"Content-Type": "application/json"}, Body: string(responseBody), }, err } ::: 5.1のまとめ このセクションで、Slack App の App ID や OAuth & Permissions でのスコープ付与方法、Event Subscriptions でのイベント購読設定を説明し、Slack イベントの受信・解析プロセス(URL Verification 対応、署名検証、再試行リクエスト無視、CallbackEvent 処理)を示しました。 次の 5.2 以降では、CallbackEvent 処理の具体例や、Go 側でのテキスト処理、Python Lambda への問い合わせ方法などを紹介します。 5.2 [Go] HTMLテキストのサニタイズ 外部リンク参照内容のサニタイズ 外部リンクから取得した HTML テキストには、 script や style など回答に不要なタグが含まれる場合があります。そのまま LLM に渡すと、トークン数が増えてモデルコストが上昇し、回答精度が下がる可能性があります。次のコードでは、 bluemonday パッケージを用いて基本的なサニタイズを行ったうえで、 table や ol 、 ul など重要なタグを残しつつ不要なタグを除去し、読みやすい形に整形します。 addNewlinesForTags 関数を活用し、特定のタグ後に改行を挿入してテキストを整えることで、モデルへの問い合わせ時に必要な情報のみを最適なフォーマットで渡すことが可能になります。 @ card func sanitizeContent(htmlContent string) string { // 基本的なサニタイズ ugcPolicy := bluemonday.UGCPolicy() sanitized := ugcPolicy.Sanitize(htmlContent) // カスタムポリシーで特定タグを許可 customPolicy := bluemonday.NewPolicy() customPolicy.AllowLists() customPolicy.AllowTables() customPolicy.AllowAttrs("href").OnElements("a") // タグごとに改行を追加して可読性向上 formattedContent := addNewlinesForTags(sanitized, "p") // カスタムポリシー適用後の最終サニタイズ finalContent := customPolicy.Sanitize(formattedContent) return finalContent } func addNewlinesForTags(htmlStr string, tags ...string) string { for _, tag := range tags { closeTag := fmt.Sprintf("</%s>", tag) htmlStr = strings.ReplaceAll(htmlStr, closeTag, closeTag+"\n") } return htmlStr } この処理により、モデルへの入力は不要なタグが取り除かれたテキストのみとなり、回答精度とコスト効率が向上します。必要な構造(テーブルや箇条書き)は保持しつつ、特定タグの終了後に改行を挿入することで、モデルが情報を理解しやすい形でコンテキストを提供できます。 5.3 [Python] LLM問い合わせの具体例 以下は、Python で LLM(たとえば Azure OpenAI)へ問い合わせる処理の例です。 OpenAIClientFactory を用いてモデルやエンドポイントを動的に切り替えられるため、複数の Lambda ハンドラ間で共通のクライアント生成処理を再利用できます。 クライアント生成処理 OpenAIClientFactory は api_type や model に応じて Azure OpenAI または OpenAI 用のクライアントを動的に生成します。 環境変数や秘密情報により API キー、エンドポイントを取得するため、モデル変更や設定変更時もコード修正が最小限で済みます。 import openai from shared.secrets import get_secret class OpenAIClientFactory: @staticmethod def create_client(region="eastus2", model="gpt-4o") -> openai.OpenAI: secret = get_secret() api_type = secret.get("openai_api_type", "azure") if api_type == "azure": return openai.AzureOpenAI( api_key=secret.get(f"azure_openai_api_key_{region}"), azure_endpoint=secret.get(f"azure_openai_endpoint_{region}"), api_version=secret.get( f"azure_openai_api_version_{region}", "2024-07-01-preview" ), ) elif api_type == "openai": return openai.OpenAI(api_key=secret.get("openai_api_key")) raise ValueError(f"Invalid api_type: {api_type}") LLM問い合わせ処理 chatCompletionHandler 関数では、HTTP リクエストとして受け取った JSON から messages や model 、 temperature などを取得し、 OpenAIClientFactory で生成したクライアントを用いて LLM に問い合わせます。 レスポンスは JSON 形式で返し、エラー発生時は共通のエラーレスポンス生成関数によって整形されたレスポンスを返します。 import json from typing import Any, Dict, List import openai from openai.types.chat import ChatCompletionMessageParam from shared.openai_client import OpenAIClientFactory def chatCompletionHandler(event: Dict[str, Any], context: Any) -> Dict[str, Any]: request_body = json.loads(event["body"]) messages: List[ChatCompletionMessageParam] = request_body.get("messages", []) model = request_body.get("model", "gpt-4o") client = OpenAIClientFactory.create_client(model=model) temperature = request_body.get("temperature", 0.7) max_tokens = request_body.get("max_tokens", 4000) response_format = request_body.get("response_format", None) completion = client.chat.completions.create( model=model, stream=False, messages=messages, max_tokens=max_tokens, frequency_penalty=0, presence_penalty=0, temperature=temperature, response_format=response_format, ) return { "statusCode": 200, "body": json.dumps(completion.to_dict()), "headers": { "Content-Type": "application/json", "Access-Control-Allow-Origin": "*", "Access-Control-Allow-Methods": "OPTIONS,POST", "Access-Control-Allow-Headers": "Content-Type,X-Amz-Date,Authorization,X-Api-Key,X-Amz-Security-Token", }, } この仕組みにより、異なる Lambda ハンドラでも同様の手順で LLM 問い合わせが可能となり、モデルやエンドポイント変更にも柔軟に対応できる構成となっています。 5.4 [Python] RAG検索呼び出し例 このセクションでは、Python で RAG(Retrieval Augmented Generation)検索を行うための手順を示します。 Confluence ドキュメントなど社内のナレッジをベクトル化し、FAISS インデックスを用いて類似文書検索を行うことで、LLM 回答に特化した情報を組み込むことが可能です。 ここで注目すべき点は faiss ライブラリの取り扱いです。 faiss は非常にサイズが大きく、Lambda Layer の容量制限を超える可能性があるため、通常は EFS を利用するか、Lambda をコンテナ化する必要があります。 今回はその手間を省くため、 setup_faiss 関数により S3 から faiss 関連パッケージをダウンロード・展開し、 sys.path に動的に追加することで faiss を利用可能にしています。 FAISS とは FAISS(Facebook AI Similarity Search)は、Meta(Facebook)製の近似最近傍探索ライブラリであり、類似の画像やテキストを検索するためのインデックスを作成するツールです。 @ card setup_faiss 関数によるFAISSセットアップ FAISS パッケージを Lambda 環境で利用するために、 setup_faiss 関数では次の手順を行います。 ローカル/CI環境でfaissパッケージをビルド・アーカイブ 開発者が GitHub Actions などの CI 環境で faiss-cpu パッケージをインストールし、必要なバイナリを tar.gz 形式でまとめます。 S3へアップロード CI でビルド・アーカイブした faiss_package.tar.gz を S3 にアップロードします。 本番やステージング環境に合わせて、適切なバケットやパスへ格納することで、Lambda 実行時に S3 から動的に取得可能です。 Lambda実行時に setup_faiss で動的ロード Lambda 実行環境上では、 setup_faiss 関数が起動時に S3 から faiss_package.tar.gz をダウンロード・展開し、 sys.path に追加します。 これにより、Lambda コード内で import faiss が可能となり、Embedding 処理で作成したベクトルを高速に検索できます。 GitHub Actions でfaissパッケージをS3へアップロードする例 以下は、 faiss-cpu をインストールし、Lambda で利用できるようにパッケージ化した上で、S3 にアップロードする GitHub Actions の例です。 ここでは、GitHub Actions の Secret や Environment Variables 機能を利用することで、AWS 認証情報や S3 バケット名などをハードコーディングせずに管理しています。 @ card name: Build and Upload FAISS on: workflow_dispatch: inputs: environment: description: デプロイ環境 type: environment default: dev jobs: build-and-upload-faiss: environment: ${{ inputs.environment }} runs-on: ubuntu-latest steps: - uses: actions/checkout@v4 - uses: actions/setup-python@v5 with: python-version: "3.11" # 必要なパッケージのインストール(faiss-cpu) - name: Install faiss-cpu run: | set -e echo "Installing faiss-cpu..." pip install faiss-cpu --no-deps # faiss のバイナリをアーカイブ - name: Archive faiss binaries run: | mkdir -p faiss_package pip install --target=faiss_package faiss-cpu tar -czvf faiss_package.tar.gz faiss_package # AWS認証情報の設定(環境に合わせてSecretsやRoleを指定) - name: Configure AWS credentials uses: aws-actions/configure-aws-credentials@v3 with: aws-access-key-id: ${{ secrets.CICD_AWS_ACCESS_KEY_ID }} aws-secret-access-key: ${{ secrets.CICD_AWS_SECRET_ACCESS_KEY }} aws-region: ap-northeast-1 # S3 にアップロード - name: Upload faiss binaries to S3 run: | echo "Uploading faiss_package.tar.gz to S3..." aws s3 cp faiss_package.tar.gz s3://${{ secrets.AWS_S3_BUCKET }}/lambda/faiss_package.tar.gz echo "Upload complete." 上記の例では、 faiss_package.tar.gz が S3 に lambda/faiss_package.tar.gz というキーでアップロードされます。 Lambda側での動的ロード処理 ( setup_faiss 関数) setup_faiss 関数は、Lambda 実行時に S3 から faiss_package.tar.gz をダウンロードし、 /tmp ディレクトリに展開、 sys.path にパッケージパスを追加します。こうして Lambda 内で import faiss が可能になり、FAISS インデックス検索を実行できるようになります。 # setup_faiss例:S3上のfaissパッケージをダウンロードし、sys.pathに追加 import os import sys import tarfile from shared.logger import getLogger from shared.s3_client import S3Client logger = getLogger(__name__) def setup_faiss(s3_client: S3Client, s3_bucket: str) -> None: try: import faiss logger.info("faiss が既にインポートされています。") except ImportError: logger.info("faiss が見つかりません。S3からダウンロードします。") faiss_package_key = "lambda/faiss_package.tar.gz" faiss_package_path = "/tmp/faiss_package.tar.gz" faiss_extract_path = "/tmp/faiss_package" # S3からパッケージをダウンロードして展開 s3_client.download_file(bucket_name=s3_bucket, key=faiss_package_key, file_path=faiss_package_path) with tarfile.open(faiss_package_path, "r:gz") as tar: for member in tar.getmembers(): member.name = os.path.relpath(member.name, start=member.name.split("/")[0]) tar.extract(member, faiss_extract_path) sys.path.insert(0, faiss_extract_path) import faiss logger.info("faiss のインポートに成功しました。") EmbeddingsとFAISSインデックスを用いたRAG検索 search_data 関数では、S3 から取得した FAISS インデックスをローカルでロードし、クエリに合致する文書を検索します。 get_embeddings 関数によって生成される Embeddings クライアント(Azure OpenAI または OpenAI)を用いて文書をベクトル化しており、 faiss を活用した高速検索が可能です。 from typing import Any, Dict, List, Optional from langchain_community.vectorstores import FAISS from langchain_core.documents.base import Document from langchain_core.vectorstores.base import VectorStoreRetriever from shared.secrets import get_secret from shared.logger import getLogger from langchain_openai import AzureOpenAIEmbeddings, OpenAIEmbeddings logger = getLogger(__name__) def get_embeddings(secrets: Dict[str, str]): api_type: str = secrets.get("openai_api_type", "azure") if api_type == "azure": return AzureOpenAIEmbeddings( openai_api_key=secrets.get("azure_openai_api_key_eastus2"), azure_endpoint=secrets.get("azure_openai_endpoint_eastus2"), model="text-embedding-3-large", api_version=secrets.get("azure_openai_api_version_eastus2", "2023-07-01-preview"), ) elif api_type == "openai": return OpenAIEmbeddings( openai_api_key=secrets.get("openai_api_key"), model="text-embedding-3-large", ) else: logger.error("無効なAPIタイプが指定されています。") raise ValueError("Invalid api_type") def search_data( query: str, index_folder_path: str, search_type: str = "similarity", score_threshold: Optional[float] = None, k: Optional[int] = None, fetch_k: Optional[int] = None, lambda_mult: Optional[float] = None, ) -> List[Dict]: secrets: Dict[str, str] = get_secret() embeddings = get_embeddings(secrets) db: FAISS = FAISS.load_local( folder_path=index_folder_path, embeddings=embeddings, allow_dangerous_deserialization=True, ) search_kwargs = {"k": k} if search_type == "similarity_score_threshold" and score_threshold is not None: search_kwargs["score_threshold"] = score_threshold elif search_type == "mmr": search_kwargs["fetch_k"] = fetch_k or k * 4 if lambda_mult is not None: search_kwargs["lambda_mult"] = lambda_mult retriever: VectorStoreRetriever = db.as_retriever( search_type=search_type, search_kwargs=search_kwargs, ) results: List[Document] = retriever.invoke(input=query) return [{"content": doc.page_content, "metadata": doc.metadata} for doc in results] 非同期ダウンロードとLambdaハンドラ async_handler 内で setup_faiss を実行し、 download_files で S3 から FAISS インデックスファイルを取得します。その後 search_data で RAG 検索を実行し、結果を JSON で返します。 import asyncio import json import os from shared.s3_client import S3Client from shared.logger import getLogger from shared.token_verifier import with_token_verification logger = getLogger(__name__) RESULT_NUM = 5 @with_token_verification async def async_handler(event: Dict[str, Any], context: Any) -> Dict[str, Any]: env = os.getenv("ENV") s3_client = S3Client() s3_bucket = "bucket-name" setup_faiss(s3_client, s3_bucket) request_body_str = event.get("body", "{}") request_body = json.loads(request_body_str) query = request_body.get("query") index_path = request_body.get("index_path") local_index_dir = "/tmp/index_faiss" await download_files(s3_client, s3_bucket, index_path, local_index_dir) results = search_data( query, local_index_dir, search_type=request_body.get("search_type", "similarity"), score_threshold=request_body.get("score_threshold"), k=request_body.get("k", RESULT_NUM), fetch_k=request_body.get("fetch_k"), lambda_mult=request_body.get("lambda_mult"), ) return create_response(200, results) def retrieverHandler(event: Dict[str, Any], context: Any) -> Dict[str, Any]: return asyncio.run(async_handler(event, context)) def create_response(status_code: int, body: Any) -> Dict[str, Any]: return { "statusCode": status_code, "body": json.dumps(body, ensure_ascii=False), "headers": { "Content-Type": "application/json", }, } async def download_files(s3_client: S3Client, bucket: str, key: str, file_path: str) -> None: loop = asyncio.get_running_loop() await loop.run_in_executor(None, download_files_from_s3, s3_client, bucket, key, file_path) def download_files_from_s3(s3_client: S3Client, s3_bucket: str, prefix: str, local_dir: str) -> None: keys = s3_client.list_objects(bucket_name=s3_bucket, prefix=prefix) if not keys: logger.info(f"'{prefix}'内にファイルが存在しません。") return for key in keys: relative_path = os.path.relpath(key, prefix) local_file_path = os.path.join(local_dir, relative_path) os.makedirs(os.path.dirname(local_file_path), exist_ok=True) s3_client.download_file(bucket_name=s3_bucket, key=key, file_path=local_file_path) 5.4のまとめ setup_faiss による faiss 動的ロードで Lambda レイヤー容量問題を回避 非同期 I/O と S3 利用により、コンテナ化や EFS 接続なしで FAISS インデックスをロード search_data で Embedding 済みインデックスを検索し、RAG が迅速な類似文書提供を実現 これにより、RAG 検索を用いた高速なナレッジ検索が可能となり、LLM 回答に特化した情報提供が実現できます。 5.5 [Python] EmbeddingとFAISSインデックス化 このセクションでは、Confluence ドキュメントなどの社内ドキュメントを Embedding し、FAISS インデックスを作成・更新する定期バッチ処理の例を示します。 RAG パイプラインで参照するインデックスは、生成 AI が社内特有の知識を回答に反映するための重要な鍵です。そのため、定期的なドキュメント更新時には Embedding と FAISS インデックスを再構築し、最新情報を常に参照できるようにします。 処理の概要 S3 から JSON フォーマットのドキュメントを取得 取得したドキュメントを Embedding(OpenAI や Azure OpenAI の Embeddings API を利用) Embedding 済みのテキスト群を FAISS インデックス化 作成した FAISS インデックスを S3 へアップロード これらの手順を Lambda バッチ処理や Step Functions ワークフローで定期的に実行することで、問い合わせ時には常に最新インデックスを用いた RAG 検索が行えます。 ステップ1:JSONドキュメントの読み込み S3 上の JSON ファイル(Confluence ページ等を要約済みのもの)をダウンロード・パースし、 Document オブジェクトのリストに変換します。 import json from typing import Any, Dict, List from langchain_core.documents.base import Document from shared.logger import getLogger logger = getLogger(__name__) def load_json(file_path: str) -> List[Document]: """ JSONファイルを読み込み、Documentオブジェクトのリストを返します。 JSONは [{"title": "...", "content": "...", "id": "...", "url": "..."}] のような形式を想定。 """ with open(file_path, "r", encoding="utf-8") as f: data = json.load(f) if not isinstance(data, list): raise ValueError("JSONトップレベルがリストではありません。") documents = [] for record in data: if not isinstance(record, dict): logger.warning(f"スキップされたレコード(辞書でない): {record}") continue title = record.get("title", "") content = record.get("content", "") metadata = { "id": record.get("id"), "title": title, "url": record.get("url"), } # タイトルとコンテンツをまとめたテキストとしてDocument化 doc = Document(page_content=f"Title: {title}\nContent: {content}", metadata=metadata) documents.append(doc) logger.info(f"{len(documents)} 件のドキュメントをロードしました。") return documents ステップ2:EmbeddingとFAISSインデックス化 vectorize_and_save 関数では、 get_embeddings で取得した Embeddings クライアントでドキュメントを Embedding し、 FAISS インデックスを作成します。その後、ローカルにインデックスを保存します。 import os from langchain_community.vectorstores import FAISS from langchain_core.text_splitter import RecursiveCharacterTextSplitter from shared.logger import getLogger logger = getLogger(__name__) def vectorize_and_save(documents: List[Document], output_dir: str, embeddings) -> None: """ ドキュメントをEmbeddingし、FAISSインデックスを作成してローカルに保存します。 """ # テキスト分割器を使用してドキュメントを小さなチャンクに分割 text_splitter = RecursiveCharacterTextSplitter(chunk_size=1024, chunk_overlap=128) split_docs = text_splitter.split_documents(documents) logger.info(f"{len(split_docs)} 件の分割済みドキュメント") # Embeddingsでベクトル化し、FAISSインデックス構築 db: FAISS = FAISS.from_documents(split_docs, embeddings) logger.info("ベクトルDBの構築が完了しました。") os.makedirs(output_dir, exist_ok=True) db.save_local(output_dir) logger.info(f"ベクトルDBを {output_dir} に保存しました。") ステップ3:インデックスをS3へアップロード ローカルで作成した FAISS インデックスを S3 にアップロードすることで、RAG 検索用 Lambda から容易に取得可能になります。 from shared.s3_client import S3Client from shared.logger import getLogger logger = getLogger(__name__) def upload_faiss_to_s3(s3_client: S3Client, s3_bucket: str, local_index_dir: str, index_s3_path: str) -> None: """ FAISSインデックスをS3にアップロードします。 """ index_files = ["index.faiss", "index.pkl"] for file_name in index_files: local_file_path = os.path.join(local_index_dir, file_name) s3_index_key = os.path.join(index_s3_path, file_name) s3_client.upload_file(local_file_path, s3_bucket, s3_index_key) logger.info(f"FAISSインデックスファイルを s3://{s3_bucket}/{s3_index_key} にアップロードしました。") ステップ4:全体フローをLambdaで実行 index_to_s3 関数は全体フローをまとめています。S3 から JSON をダウンロード、Embedding と FAISS インデックス作成、そしてインデックスを S3 へアップロードします。この処理を Step Functions などのワークフローで定期的に実行し、常に最新のインデックスを用意します。 import os from shared.faiss import setup_faiss from shared.logger import getLogger from shared.s3_client import S3Client from shared.secrets import get_secret logger = getLogger(__name__) def index_to_s3(json_s3_key: str, index_s3_path: str) -> Dict[str, Any]: """ S3からJSONファイルをダウンロードし、EmbeddingとFAISSインデックス作成を行い、インデックスをS3に保存します。 """ env = os.getenv("ENV") if env is None: error_msg = "ENV 環境変数が設定されていません。" logger.error(error_msg) return {"status": "error", "message": error_msg} try: s3_client = S3Client() s3_bucket = "bucket-name" local_json_path = "/tmp/json_file.json" local_index_dir = "/tmp/index" # 必要なら faiss のセットアップ(S3からダウンロード) setup_faiss(s3_client, s3_bucket) # JSONファイルをS3からダウンロード s3_client.download_file(s3_bucket, json_s3_key, local_json_path) documents = load_json(local_json_path) # Embeddingsクライアント取得 secrets = get_secret() embeddings = get_embeddings(secrets) # ベクトル化とFAISSインデックス作成 vectorize_and_save(documents, local_index_dir, embeddings) # インデックスファイルをS3へアップロード upload_faiss_to_s3(s3_client, s3_bucket, local_index_dir, index_s3_path) return { "status": "success", "message": "FAISSインデックスを作成し、S3にアップロードしました。", "output": { "bucket": s3_bucket, "index_key": index_s3_path, }, } except Exception as e: logger.error(f"インデックス作成処理中にエラー発生: {e}") return {"status": "error", "message": str(e)} 5.5のまとめ load_json で JSON ファイルを読み込み、 vectorize_and_save で Embedding と FAISS インデックス作成 upload_faiss_to_s3 でローカルインデックスを S3 へアップロード index_to_s3 で全体フローをまとめ、定期バッチ処理で最新インデックスを作成・更新 これにより、社内ドキュメントを Embedding し、RAG 検索用の FAISS インデックスを作成・更新するバッチ処理を実現できます。 6. まとめ 本記事では、Slack 上で LLM を活用する社内チャットボットしぇるぱの開発背景や技術的実装ポイント、RAG パイプラインの導入手順、Confluence ドキュメントのサニタイズや Embedding/FAISS インデックスによる検索基盤の整備、さらには翻訳・要約などの機能拡張について紹介しました。 こうした仕組みにより、Slack 内で自然な操作で生成 AI を利用でき、社員は新たなツールやコマンドを学ぶことなく高度な情報活用が可能になります。 7. 今後の展望 私たちはしぇるぱをさらに進化させるため次の改善・拡張に積極的に取り組みます。 Azure 環境での構築強化 Azure Functions や Azure CosmosDB などの Azure サービスとの連携を本格化し RAG パイプラインのパフォーマンスや拡張性を抜本的に向上させます。 Azure Cosmos DBベクトル検索の導入 Azure Cosmos DB for NoSQL 上でベクトル検索機能を実用化しより高度な検索を提供します。 @ card AI Document Intelligenceの活用 AI Document Intelligence を積極的に取り込み RAG のナレッジ範囲を拡大させより多彩な情報活用を実現します。 @ card モデルの多様化・高度化 GPT-4o のみならず GPT-o1 や Google Gemini など最新で多様なモデルへの対応を推進し常に最先端のモデルを統合します。 Web UIの実装 Slack 依存の表現上の制約を解消するため Web UI を構築し多彩なインタラクションや新機能を柔軟に展開します。 プロンプト管理の拡充 既存のプロンプトをテンプレート化し用途別に容易な再利用を実現します。またプロンプト共有機能を充実させ社内全体での生成 AI 活用を一層促進します。 マルチエージェント化の実現 要約や翻訳、 RAG 検索など特定機能に特化した専門エージェントを配置し、エージェントビルダー機能で自由に組み合わせることでより柔軟で高度な情報活用を可能にします。 RAG精度の評価・改善 テストセットを構築し回答の自動評価を実施して精度を定量的に把握し継続的な品質向上につなげます。 ユーザーフィードバックを起点とした改善 利用実態やフィードバックを反映し対話フローの最適化やプロンプトチューニング外部サービス連携強化など実運用を通じて常にしぇるぱの利便性と有用性を高めていきます。 私たちはこれらの取り組みによってしぇるぱを持続的に進化させ、より多様なニーズに応えられる力強い社内支援ツールへ成長させます。
1. はじめに こんにちは、共通サービス開発グループの鳥居( @yu_torii )です。主にバックエンド/フロントエンド領域を担当しています。 KINTO 会員プラットフォーム開発チームでフロントエンドエンジニアを務めながら、社内での生成 AI 活用にも携わっています。 本記事では、Slack 上で LLM を活用する社内チャットボットの RAG や Slack リアクションを活用した翻訳機能を紹介します。 社内向け生成AIツールは、社内での生成 AI 活用を目指して開発された Slack チャットボットです。 フロントエンド開発を省略して素早く社内に展開し、社員が普段使う Slack 上で生成 AI を自然に利用できる環境を目標としています。 頼れる存在であるように、また社内の業務効率の向上や情報共有の円滑化のための頼れるパートナーでありたいという願いが込められています。 ちなみに、バナーのキャラクターはクリエイティブグループの方が KINTO テクノジーズ全体会議(KTC 超本部会)に際してサプライズで描いてくれたものです。ありがとうございます! この取り組みは、生成 AI 活用プロジェクトを推進する和田さん( @cognac_n )との協力により進められました。RAG パイプラインの導入、ローカル開発環境の整備、Slack 絵文字リアクションを活用した翻訳・要約機能など、多角的な改善を行い、社内での生成 AI 利活用を推進しています。 :::details 和田さんの記事はこちら @ card @ card @ card ::: なお、RAG や生成 AI 技術そのものの詳細解説は省き、実装や機能追加の過程を中心にまとめています。 また、社内向け生成AIツールの LLM は Azure OpenAI を利用しています。 この記事で得られること Slack Botによる生成AIを活用したチャット機能の利用方法 Slack と LLM を組み合わせ、絵文字リアクションや自然なメッセージ投稿で翻訳・要約を呼び出すチャットボット実装例を紹介 HTMLサニタイズを含むConfluenceデータ取得の工夫 Confluence ドキュメントを Go で取得し、HTML サニタイズにより要約・Embedding に適したテキストを整える方法 FAISS とS3を使った簡易的なRAGパイプライン導入 FAISS インデックスと S3 を活用した簡易 RAG パイプライン導入の手順と注意点を解説 応答速度はあまり早くないものの、低コストで簡易的な RAG を組み込む際の実装ステップや注意点をまとめます。 :::message 本記事は、執筆時点での実装状況をもとにしています。改善点が多分に含まれている点をご了承ください。 社内向けのツールであるため、プロダクションレベルのパフォーマンスを必要とした実装ではありません。 AWS SAM でのデプロイや Step Functions のパイプライン構築、GitHub Actions による CI/CD など、開発環境の整備については、本記事では詳細を省略しています。 ::: :::details 目次(展開) 1. はじめに この記事で得られること 2. 全体アーキテクチャの概要 3. Slack Botによる生成AIを活用したチャット機能 「チャット機能」と「リアクション機能」 チャット機能:利用シナリオ リアクション機能:利用シナリオ この構成のメリット 3.5 実際の利用例 3章まとめ 4. 実装方針と内部設計 全体的な処理フロー 条件分岐による機能判定 サニタイズの役割 RAG利用をConfluence参照に限定 拡張性・保守性への考慮 5. コード例と設定ファイルの紹介 5.1 [Go] Slackイベント受信と解析 5.2 [Go] HTMLテキストのサニタイズ 5.3 [Python] LLM問い合わせの具体例 5.4 [Python] RAG検索呼び出し例 5.5 [Python] EmbeddingとFAISSインデックス化 ::: 2. 全体アーキテクチャの概要 ここでは、社内向け生成AIツールが生成 AI による回答を返すまでの流れを、「ユーザとの生成 AI チャット機能」と「Confluence ドキュメントをインデックス化する処理」という 2 つの視点で整理します。 ユーザとの生成AIチャット機能の処理 Slackで社内向け生成AIツールを呼び出す 社内向け生成AIツールの呼び出し方は、チャットでの呼び出しと、リアクション絵文字での呼び出しの 2 通りがあります。 チャットでの呼び出しは、チャンネルでメンションを付けて投稿するか、ダイレクトメッセージで直接投稿することで、生成 AI による回答をリクエストできます。 リアクションでの呼び出しは、翻訳・要約用の絵文字リアクションを付けることで、そのメッセージの翻訳や要約をリクエストできます。 Go Slack Bot Lambda Slack イベントを受け取る Bot は Go で実装し、Lambda 上で動作します。 ユーザからの質問やリアクションを受け取り、リクエストの種類に応じて処理を振り分けます。 LLM へのリクエストや、Embedding 済みデータの参照など Azure OpenAI を利用する場合は、ここでリクエストを生成し、Python Lambda へ送信します。 Python LambdaでのLLMへのリクエスト・RAG参照 Python Lambda は機能ごとに分割し、LLM 問い合わせや RAG 参照などを担当します。 Go Lambda からのリクエストを受け取り、LLM への問い合わせや RAG による回答生成を行います。 Slackへの回答返送 生成された回答は、Go Slack Bot Lambda を経由して Slack へ返送します。 絵文字リアクションで呼び出す翻訳・要約機能も、このフローに組み込まれています。 :::details アーキテクチャ図(ユーザからの呼び出しに対応する処理) flowchart LR subgraph "ユーザからの呼び出しに対応する処理" A["User(Slack)"] -->|"質問・絵文字"| B["Go Slack Bot(Lambda)"] B -->|"リクエスト"| C["Python Lambda RAG/LLM"] C -->|"回答"| B B -->|"回答"| A end ::: Confluence ドキュメントをインデックス化する処理 RAG パイプラインを利用するには、Confluence ドキュメントを要約・Embedding しやすい状態に整える必要があります。これらの前処理は StepFunctions でワークフロー化し、定期的かつ自動的に実行しています。 ドキュメント取得・HTMLサニタイズ(Go実装) Go で実装した Lambda が Confluence API からドキュメントを取得し、HTML タグを整理してテキストを扱いやすい状態にします。 サニタイズ済みテキストは JSON として出力します。 要約処理(Go + Python Lambda呼び出し) 要約処理の目的は、テキストを Embedding や RAG で扱いやすい範囲に絞ることです。 Go 実装の Lambda が Azure OpenAI Chat API のリクエスト処理を行う Python Lambda を呼び出し、テキストを短く整え、再び JSON 化します。 FAISSインデックス化とS3保存(Indexer Lambda) 要約後のテキストを Embedding し、FAISS インデックスを生成する Indexer Lambda がインデックスやメタ情報を S3 へ格納します。 これにより、問い合わせ発生時にはインデックス済みデータを即座に参照でき、RAG パイプラインがスムーズに稼働します。 :::details アーキテクチャ図(Confluence ドキュメントのインデックス化フロー) flowchart LR subgraph "インデックス化準備処理 StepFunctions" D["Go Lambda(ドキュメント取得/HTMLサニタイズ)"] D --> E["Go Lambda(要約/Python呼出)"] E --> F["Indexer Lambda(Embedding/FAISS/S3)"] end ::: こうした事前処理と問い合わせ時の処理が組み合わさることで、社内向け生成AIツールは Slack 上の簡易な操作で社内特有のナレッジを反映した生成 AI 回答を返せるようになっています。 以降の章では、これらの要素についてさらに詳細を見ていきます。 3. Slack Botによる生成AIを活用したチャット機能 前章でアーキテクチャの全体像を示しましたが、本章では、ユーザが Slack 上で自然な操作を行うだけで得られる機能について、その使い方や有用性に焦点を当てます。 ここでは「何ができるか」「どんなシナリオで役立つか」という利用イメージを示し、実装詳細は次章以降で体系的に紹介します。 「チャット機能」と「リアクション機能」 社内向け生成AIツールは、Slack 上での自然な操作を原動力に、多様な生成 AI 機能を提供します。 チャット機能 : 質問を投稿したり、ファイルや画像、外部リンクを貼ったり、特定の形式でメッセージを送ることで、LLM への問い合わせや(特定の場合)RAG 検索が行われ、必要な回答が得られます。 Slack という日常的なツールに機能を統合することで、ユーザは新たな環境やコマンドを学ぶ必要なく、生成 AI を自然に日常業務へ取り込むことができます。 リアクション機能 : 特定の絵文字リアクションをメッセージに付与するだけで翻訳や社内向け生成AIツール発言の削除などをトリガーでき、コマンドレスでの追加操作が可能になります。 チャット機能:利用シナリオ 基本的な質問・回答 普通に質問を投稿するだけで、LLM を通じて回答を取得できます。 利用シーン例: 「このプロジェクトの手順は?」と尋ねれば即座に回答が得られ、スレッド内の履歴や発言者情報を考慮して文脈に沿った応答が可能です。 ファイル・画像・外部リンク参照 ファイルを貼り付けて「要約して」と依頼すれば、ファイル内容を要約。 画像を添付すれば文字起こしや画像内容を踏まえた回答が可能。 外部リンクを貼れば、そのページ内容を整理して LLM 回答に生かせます。 利用シーン例: 会議メモが入ったテキストファイルを「要約して」で短いサマリを得る、画像内文字情報を抜き出す、外部記事リンクを要約するといった、手間を省く活用ができます。 Confluenceページ参照(RAG活用) :confluence: index:Index名 で、社内でのルールや申請方法等のドキュメントが含まれた Confluence ページを RAG 検索。 利用シーン例: 社内申請手順や内部ルールが Confluence にまとまっている場合、必要な情報を即座に引き出し、一般的な回答以上に社内事情に即したアドバイスが得られます。 利用シーン例: プロジェクト独自の手順書や設定値を検索して、その内容を回答に反映。検索しづらい情報を簡単に引き出せます。 リアクション機能:利用シナリオ 特定の絵文字リアクションを付けることで、さらに直感的な機能呼び出しが可能です。 翻訳 : 翻訳用絵文字を付ければ、そのメッセージを指定言語へ翻訳可能です。言語の壁を低くし、コミュニケーションを円滑化します。 削除 不要になった社内向け生成AIツール発言を絵文字 1 つで簡易に削除し、チャンネルを整理できます。 この構成のメリット 自然な操作で活用可能 : ユーザは慣れた Slack 操作(メッセージ投稿、絵文字付与など)だけで生成 AI 機能を使え、学習コストを低減できます。 日常ツールへの統合で生成AI定着 : Slack という普段使うコミュニケーション基盤に機能を溶け込ませることで、生成 AI を身近に利用することが可能です。またリアクション機能は文字入力をすることなく、翻訳や削除などの操作ができるため、手軽に利用できます。 拡張に対応しやすい土台 : 今後、新たなモデルや追加機能を組み込みたくなった場合も、既存のフロー(質問投稿、絵文字操作)に条件を増やすだけで拡張可能です。 3.5 実際の利用例 ここで、社内向け生成AIツールが Slack 上でどのように使われているか、実際のシナリオをいくつか紹介します。 例1:画像の認識 メッセージに画像を添付すると、社内向け生成AIツールは画像内のテキストを認識し、その内容を回答します。  画像の認識 例2:Confluenceドキュメントに基づく回答 :confluence: という絵文字を使うことで、Confluence ドキュメントを参照した回答を得ることができます。  Confluenceドキュメントに基づく回答 ご覧の通り、社内向け生成AIツールはワークフローから呼び出すことも可能で、プロンプトストアのような利用も可能です。 例3:翻訳リアクションでの英訳依頼 ユーザが英訳したいメッセージに翻訳リアクションを付与 英語話者に共有したい日本語メッセージに :ai_tool_translate_to_english: といったリアクション絵文字を付けると、そのメッセージのテキストが自動で英訳されます。  英語翻訳リアクション 翻訳内容を過信しないように、自動翻訳であることを複数言語で通知することで、誤解を防ぎます。 また、機能を普及させるために、利用方法も記載しています。 英訳の他に複数言語の翻訳機能を提供しています。 3章まとめ 本章では、「どんな操作で何ができるか」というユーザ視点の使い方に注目しました。 ここで得た利用イメージを基に、次の章以降で実装内容を体系的に示し、Go 製 Bot や Python Lambda の連携方法、Slack イベントの処理や RAG 検索のしくみ、ファイル抽出やサニタイズ処理などの詳細を紹介します。 4. 実装方針と内部設計 この章では、社内向け生成AIツールが Slack のメッセージやリアクションを通じて多様な生成 AI 機能を提供するための実装方針と内部設計について説明します。 ここで紹介するのは、あくまで全体的な考え方や役割分担、拡張性への配慮に関する部分です。具体的なコードや設定ファイルは次章以降に記載します。 全体的な処理フロー Slackイベント受信(Go Lambda) Slack で行われるメッセージ投稿、ファイル添付、画像挿入、外部リンク記載、絵文字リアクションなどのイベントは、Slack API 経由で Go 実装の AWS Lambda へ通知されます。 Go 側はこれらのイベントを解析し、ユーザが求める処理(通常のチャット、翻訳、Confluence 参照など)を判定します。 Go側でのテキスト処理・サニタイズ 外部リンクやファイルからテキストを取得し、コンテキストとしてプロンプトに追加します。 外部リンクを参照する場合は table 、 ol 、 ul など意味のあるタグは残し、不要なタグだけを除去してトークンを節約します。 Python側でのLLM問い合わせ・RAG検索 必要な場合、Go 側は LLM 問い合わせ用の Python Lambda(LLM 用)か、RAG 検索用の Python Lambda(Confluence 参照用)を呼び出します。 例えば、 :confluence: が含まれていれば RAG 検索用 Lambda を呼び出し、index が指定されていなければデフォルトインデックスで検索します。 そうでなければ通常は LLM 用 Lambda へテキストを渡し、LLM への問い合わせを行います。 回答返却とSlack表示 Python 側の Lambda が生成した回答を Go 側に戻し、Go 側が Slack へ投稿します。 これにより、ユーザはコマンドを暗記する必要なく、絵文字やキーワード、ファイル添付など日常的な操作だけで高度な機能を利用できます。 条件分岐による機能判定 特定の絵文字( :confluence: など)やキーワード、ファイルや画像の有無、外部リンク存在などにより処理を振り分けます。 新機能を追加する場合は、Go 側で新たな条件を追加して、必要なら対応する Python 側の Lambda(LLM 用、RAG 用など)を呼び出すロジックを増やすことで実現できます。 サニタイズの役割 Go 側でサニタイズし、不要な HTML タグを除去することで、モデルへ渡すテキストを効率的に扱い、トークン消費を抑えます。 table、ol、ul など意味あるタグは残して情報構造を保持し、モデルにとって有用な文脈を損ねないようにしています。 RAG利用をConfluence参照に限定 RAG 検索は :confluence: 指定時のみ利用します。 これにより通常の要約や翻訳、Q&A は LLM 直接問い合わせで済み、RAG 関連ロジックは Confluence 参照時だけ発動します。 Confluence ドキュメントの Embedding 生成や FAISS インデックス更新は StepFunctions で定期的に実行し、問い合わせ時には常に最新インデックスを利用できます。 拡張性・保守性への考慮 絵文字やキーワード、ファイル・画像の有無による条件分岐は、機能を増やす際の変更箇所を少なく保ち、保守性を高めます。 Go 側でテキスト整形やサニタイズ、Python 側で LLM 問い合わせ・RAG 検索を行う役割分担も、コードの見通しを良くし、将来的なモデル切り替えや処理追加を容易にします。 次章では、これらの方針を踏まえた具体的なコードスニペットや設定ファイル例を紹介します。 5. コード例と設定ファイルの紹介 この章では、第 4 章で説明した実装方針や設計上の考え方に基づいて、実装例を要点を絞って紹介します。 本章は次のセクションで構成します。 5.1 Slack イベント受信と解析(Go 側) Slack の Events API を用いてメッセージや絵文字リアクションなどのイベントを受信・解析する方法を示します。 5.2 Go 側でサニタイズ例 外部リンク参照した際の HTML サニタイズ処理の例を示します。 5.3 Python 側 LLM 問い合わせの具体例 LLM(LLM)への問い合わせを行う Lambda のコード例を提示します。 5.4 Python 側 RAG 検索呼び出し例 Confluence 参照など RAG を使う場合の検索呼び出し例を紹介します。 5.5 Python 側 Embedding と FAISS インデックス化 Confluence ドキュメントを定期的に Embedding し、FAISS インデックスを更新する Lambda のコード例を示します。 5.1 [Go] Slackイベント受信と解析 このセクションでは、Slack の Events API を利用して、AWS Lambda 上で Go コードでイベントを受信・解析する基本的な流れを説明します。 Slack 側での設定(OAuth & Permissions、イベント購読)や、 chat.postMessage メソッド利用時に必要なスコープ( chat:write など)の確認方法にも触れ、読者が実装を始めるまでに必要な準備を明確にします。 Slack側での設定手順 App作成とApp IDの確認 : https://api.slack.com/apps で新規 App を作成します。 作成後、Basic Information ページ( https://api.slack.com/apps/APP_ID/general 、 APP_ID は App 固有の ID)で App ID( A で始まる文字列)を確認します。 この App ID は Slack App の識別子であり、後述の OAuth & Permissions や Event Subscriptions ページの URL アクセスに用いることができます。 OAuth & Permissionsでスコープ付与 : 「OAuth & Permissions」ページ( https://api.slack.com/apps/APP_ID/oauth )にアクセスし、Bot Token Scopes に必要なスコープを追加します。 例えば、チャンネルへメッセージ投稿に chat.postMessage メソッドが必要である場合、 https://api.slack.com/methods/chat.postMessage で「Required scopes」を確認すると chat:write が必要であるとわかります。 スコープ付与後、「reinstall your app」をクリックし、ワークスペースに再インストールすると、変更が反映されます。  Required scopesの確認  Scopeの設定 Events API有効化とイベント購読 : 「Event Subscriptions」ページ( https://api.slack.com/apps/APP_ID/event-subscriptions )で Events API を有効化し、「Request URL」に後述の AWS Lambda エンドポイントを設定します。 message.channels や reaction_added など、購読するイベントを追加します。これにより、対象イベント発生時に Slack が指定 URL へ通知を送るようになります。  AWS Lambda側でのイベント受信・解析 Slack 側での設定が完了すると、購読対象のイベントが発生するたびに Slack は API Gateway 経由で Lambda へ POST リクエストを送ります。 ステップ1:Slackイベントの解析 slack-go/slackevents パッケージを用いて、受信した JSON を EventsAPIEvent へ変換します。 これにより、URL 検証や CallbackEvent などイベントタイプを判別しやすくなります。 func parseSlackEvent(body string) (*slackevents.EventsAPIEvent, error) { event, err := slackevents.ParseEvent(json.RawMessage(body), slackevents.OptionNoVerifyToken()) if err != nil { return nil, fmt.Errorf("Slackイベントの解析に失敗しました: %w", err) } return &event, nil } @ card ステップ2:URL検証要求対応 初回に Slack は type=url_verification のイベントを送ってきます。この中の challenge をそのまま返すことで Slack は URL 有効性を確認し、その後イベントを通知してくれるようになります。 func handleURLVerification(body string) (events.APIGatewayProxyResponse, error) { var r struct { Challenge string `json:"challenge"` } if err := json.Unmarshal([]byte(body), &r); err != nil { return createErrorResponse(400, err) } return events.APIGatewayProxyResponse{ StatusCode: 200, Body: r.Challenge, }, nil } @ card ステップ3:署名検証・再試行リクエスト無視 Slack はリクエスト署名を付与し、正当性を検証できます(実装は省略)。 また、障害時などに再試行リクエストが送られる場合があり、 X-Slack-Retry-Num ヘッダで再試行を判定して同じイベントを二重処理しないようにできます。 func verifySlackRequest(body string, headers http.Header) error { // 署名検証処理(省略) return nil } func isSlackRetry(headers http.Header) bool { return headers.Get("X-Slack-Retry-Num") != "" } func createIgnoredRetryResponse() (events.APIGatewayProxyResponse, error) { responseBody, _ := json.Marshal(map[string]string{"message": "Slackの再試行を無視します"}) return events.APIGatewayProxyResponse{ StatusCode: 200, Headers: map[string]string{"Content-Type": "application/json"}, Body: string(responseBody), }, nil } ステップ4:CallbackEvent処理 CallbackEvent は実際のメッセージ投稿やリアクション追加などが含まれます。ここで、 :confluence: が含まれるか、ファイルがあるか、翻訳用絵文字が付いているかなどを判定し、5.2 以降で示すテキスト処理や Python Lambda 呼び出しへ進みます。 // handleCallbackEvent は、コールバックイベントを処理します。(5.1での説明対象) func handleCallbackEvent(ctx context.Context, isOrchestrator bool, event *slackevents.EventsAPIEvent) (events.APIGatewayProxyResponse, error) { innerEvent := event.InnerEvent switch innerEvent.Data.(type) { case *slackevents.AppMentionEvent: // AppMentionEventの場合の処理(5.2で詳細説明) case *slackevents.MessageEvent: // MessageEventの場合の処理(5.2で詳細説明) case *slackevents.ReactionAddedEvent: // ReactionAddedEventの場合の処理(5.2で詳細説明) } return events.APIGatewayProxyResponse{Body: "OK", StatusCode: http.StatusOK}, nil } ハンドラ全体のコード例 これらのステップを組み合わせて AWS Lambda ハンドラを定義します。 :::details ハンドラ全体のコード例 func handler(ctx context.Context, request events.APIGatewayProxyRequest) (events.APIGatewayProxyResponse, error) { event, err := parseSlackEvent(request.Body) if err != nil { return createErrorResponse(400, err) } if event.Type == slackevents.URLVerification { return handleURLVerification(request.Body) } headers := convertToHTTPHeader(request.Headers) err = verifySlackRequest(request.Body, headers) if err != nil { return createErrorResponse(http.StatusUnauthorized, fmt.Errorf("リクエストの検証に失敗しました: %w", err)) } if isSlackRetry(headers) { return createIgnoredRetryResponse() } if event.Type == slackevents.CallbackEvent { return handleCallbackEvent(ctx, event) } return events.APIGatewayProxyResponse{Body: "OK", StatusCode: 200}, nil } func convertToHTTPHeader(headers map[string]string) http.Header { httpHeaders := http.Header{} for key, value := range headers { httpHeaders.Set(key, value) } return httpHeaders } func createErrorResponse(statusCode int, err error) (events.APIGatewayProxyResponse, error) { responseBody, _ := json.Marshal(map[string]string{"error": err.Error()}) return events.APIGatewayProxyResponse{ StatusCode: statusCode, Headers: map[string]string{"Content-Type": "application/json"}, Body: string(responseBody), }, err } ::: 5.1のまとめ このセクションで、Slack App の App ID や OAuth & Permissions でのスコープ付与方法、Event Subscriptions でのイベント購読設定を説明し、Slack イベントの受信・解析プロセス(URL Verification 対応、署名検証、再試行リクエスト無視、CallbackEvent 処理)を示しました。 次の 5.2 以降では、CallbackEvent 処理の具体例や、Go 側でのテキスト処理、Python Lambda への問い合わせ方法などを紹介します。 5.2 [Go] HTMLテキストのサニタイズ 外部リンク参照内容のサニタイズ 外部リンクから取得した HTML テキストには、 script や style など回答に不要なタグが含まれる場合があります。そのまま LLM に渡すと、トークン数が増えてモデルコストが上昇し、回答精度が下がる可能性があります。次のコードでは、 bluemonday パッケージを用いて基本的なサニタイズを行ったうえで、 table や ol 、 ul など重要なタグを残しつつ不要なタグを除去し、読みやすい形に整形します。 addNewlinesForTags 関数を活用し、特定のタグ後に改行を挿入してテキストを整えることで、モデルへの問い合わせ時に必要な情報のみを最適なフォーマットで渡すことが可能になります。 @ card func sanitizeContent(htmlContent string) string { // 基本的なサニタイズ ugcPolicy := bluemonday.UGCPolicy() sanitized := ugcPolicy.Sanitize(htmlContent) // カスタムポリシーで特定タグを許可 customPolicy := bluemonday.NewPolicy() customPolicy.AllowLists() customPolicy.AllowTables() customPolicy.AllowAttrs("href").OnElements("a") // タグごとに改行を追加して可読性向上 formattedContent := addNewlinesForTags(sanitized, "p") // カスタムポリシー適用後の最終サニタイズ finalContent := customPolicy.Sanitize(formattedContent) return finalContent } func addNewlinesForTags(htmlStr string, tags ...string) string { for _, tag := range tags { closeTag := fmt.Sprintf("</%s>", tag) htmlStr = strings.ReplaceAll(htmlStr, closeTag, closeTag+"\n") } return htmlStr } この処理により、モデルへの入力は不要なタグが取り除かれたテキストのみとなり、回答精度とコスト効率が向上します。必要な構造(テーブルや箇条書き)は保持しつつ、特定タグの終了後に改行を挿入することで、モデルが情報を理解しやすい形でコンテキストを提供できます。 5.3 [Python] LLM問い合わせの具体例 以下は、Python で LLM(たとえば Azure OpenAI)へ問い合わせる処理の例です。 OpenAIClientFactory を用いてモデルやエンドポイントを動的に切り替えられるため、複数の Lambda ハンドラ間で共通のクライアント生成処理を再利用できます。 クライアント生成処理 OpenAIClientFactory は api_type や model に応じて Azure OpenAI または OpenAI 用のクライアントを動的に生成します。 環境変数や秘密情報により API キー、エンドポイントを取得するため、モデル変更や設定変更時もコード修正が最小限で済みます。 import openai from shared.secrets import get_secret class OpenAIClientFactory: @staticmethod def create_client(region="eastus2", model="gpt-4o") -> openai.OpenAI: secret = get_secret() api_type = secret.get("openai_api_type", "azure") if api_type == "azure": return openai.AzureOpenAI( api_key=secret.get(f"azure_openai_api_key_{region}"), azure_endpoint=secret.get(f"azure_openai_endpoint_{region}"), api_version=secret.get( f"azure_openai_api_version_{region}", "2024-07-01-preview" ), ) elif api_type == "openai": return openai.OpenAI(api_key=secret.get("openai_api_key")) raise ValueError(f"Invalid api_type: {api_type}") LLM問い合わせ処理 chatCompletionHandler 関数では、HTTP リクエストとして受け取った JSON から messages や model 、 temperature などを取得し、 OpenAIClientFactory で生成したクライアントを用いて LLM に問い合わせます。 レスポンスは JSON 形式で返し、エラー発生時は共通のエラーレスポンス生成関数によって整形されたレスポンスを返します。 import json from typing import Any, Dict, List import openai from openai.types.chat import ChatCompletionMessageParam from shared.openai_client import OpenAIClientFactory def chatCompletionHandler(event: Dict[str, Any], context: Any) -> Dict[str, Any]: request_body = json.loads(event["body"]) messages: List[ChatCompletionMessageParam] = request_body.get("messages", []) model = request_body.get("model", "gpt-4o") client = OpenAIClientFactory.create_client(model=model) temperature = request_body.get("temperature", 0.7) max_tokens = request_body.get("max_tokens", 4000) response_format = request_body.get("response_format", None) completion = client.chat.completions.create( model=model, stream=False, messages=messages, max_tokens=max_tokens, frequency_penalty=0, presence_penalty=0, temperature=temperature, response_format=response_format, ) return { "statusCode": 200, "body": json.dumps(completion.to_dict()), "headers": { "Content-Type": "application/json", "Access-Control-Allow-Origin": "*", "Access-Control-Allow-Methods": "OPTIONS,POST", "Access-Control-Allow-Headers": "Content-Type,X-Amz-Date,Authorization,X-Api-Key,X-Amz-Security-Token", }, } この仕組みにより、異なる Lambda ハンドラでも同様の手順で LLM 問い合わせが可能となり、モデルやエンドポイント変更にも柔軟に対応できる構成となっています。 5.4 [Python] RAG検索呼び出し例 このセクションでは、Python で RAG(Retrieval Augmented Generation)検索を行うための手順を示します。 Confluence ドキュメントなど社内のナレッジをベクトル化し、FAISS インデックスを用いて類似文書検索を行うことで、LLM 回答に特化した情報を組み込むことが可能です。 ここで注目すべき点は faiss ライブラリの取り扱いです。 faiss は非常にサイズが大きく、Lambda Layer の容量制限を超える可能性があるため、通常は EFS を利用するか、Lambda をコンテナ化する必要があります。 今回はその手間を省くため、 setup_faiss 関数により S3 から faiss 関連パッケージをダウンロード・展開し、 sys.path に動的に追加することで faiss を利用可能にしています。 FAISS とは FAISS(Facebook AI Similarity Search)は、Meta(Facebook)製の近似最近傍探索ライブラリであり、類似の画像やテキストを検索するためのインデックスを作成するツールです。 @ card setup_faiss 関数によるFAISSセットアップ FAISS パッケージを Lambda 環境で利用するために、 setup_faiss 関数では次の手順を行います。 ローカル/CI環境でfaissパッケージをビルド・アーカイブ 開発者が GitHub Actions などの CI 環境で faiss-cpu パッケージをインストールし、必要なバイナリを tar.gz 形式でまとめます。 S3へアップロード CI でビルド・アーカイブした faiss_package.tar.gz を S3 にアップロードします。 本番やステージング環境に合わせて、適切なバケットやパスへ格納することで、Lambda 実行時に S3 から動的に取得可能です。 Lambda実行時に setup_faiss で動的ロード Lambda 実行環境上では、 setup_faiss 関数が起動時に S3 から faiss_package.tar.gz をダウンロード・展開し、 sys.path に追加します。 これにより、Lambda コード内で import faiss が可能となり、Embedding 処理で作成したベクトルを高速に検索できます。 GitHub Actions でfaissパッケージをS3へアップロードする例 以下は、 faiss-cpu をインストールし、Lambda で利用できるようにパッケージ化した上で、S3 にアップロードする GitHub Actions の例です。 ここでは、GitHub Actions の Secret や Environment Variables 機能を利用することで、AWS 認証情報や S3 バケット名などをハードコーディングせずに管理しています。 @ card name: Build and Upload FAISS on: workflow_dispatch: inputs: environment: description: デプロイ環境 type: environment default: dev jobs: build-and-upload-faiss: environment: ${{ inputs.environment }} runs-on: ubuntu-latest steps: - uses: actions/checkout@v4 - uses: actions/setup-python@v5 with: python-version: "3.11" # 必要なパッケージのインストール(faiss-cpu) - name: Install faiss-cpu run: | set -e echo "Installing faiss-cpu..." pip install faiss-cpu --no-deps # faiss のバイナリをアーカイブ - name: Archive faiss binaries run: | mkdir -p faiss_package pip install --target=faiss_package faiss-cpu tar -czvf faiss_package.tar.gz faiss_package # AWS認証情報の設定(環境に合わせてSecretsやRoleを指定) - name: Configure AWS credentials uses: aws-actions/configure-aws-credentials@v3 with: aws-access-key-id: ${{ secrets.CICD_AWS_ACCESS_KEY_ID }} aws-secret-access-key: ${{ secrets.CICD_AWS_SECRET_ACCESS_KEY }} aws-region: ap-northeast-1 # S3 にアップロード - name: Upload faiss binaries to S3 run: | echo "Uploading faiss_package.tar.gz to S3..." aws s3 cp faiss_package.tar.gz s3://${{ secrets.AWS_S3_BUCKET }}/lambda/faiss_package.tar.gz echo "Upload complete." 上記の例では、 faiss_package.tar.gz が S3 に lambda/faiss_package.tar.gz というキーでアップロードされます。 Lambda側での動的ロード処理 ( setup_faiss 関数) setup_faiss 関数は、Lambda 実行時に S3 から faiss_package.tar.gz をダウンロードし、 /tmp ディレクトリに展開、 sys.path にパッケージパスを追加します。こうして Lambda 内で import faiss が可能になり、FAISS インデックス検索を実行できるようになります。 # setup_faiss例:S3上のfaissパッケージをダウンロードし、sys.pathに追加 import os import sys import tarfile from shared.logger import getLogger from shared.s3_client import S3Client logger = getLogger(__name__) def setup_faiss(s3_client: S3Client, s3_bucket: str) -> None: try: import faiss logger.info("faiss が既にインポートされています。") except ImportError: logger.info("faiss が見つかりません。S3からダウンロードします。") faiss_package_key = "lambda/faiss_package.tar.gz" faiss_package_path = "/tmp/faiss_package.tar.gz" faiss_extract_path = "/tmp/faiss_package" # S3からパッケージをダウンロードして展開 s3_client.download_file(bucket_name=s3_bucket, key=faiss_package_key, file_path=faiss_package_path) with tarfile.open(faiss_package_path, "r:gz") as tar: for member in tar.getmembers(): member.name = os.path.relpath(member.name, start=member.name.split("/")[0]) tar.extract(member, faiss_extract_path) sys.path.insert(0, faiss_extract_path) import faiss logger.info("faiss のインポートに成功しました。") EmbeddingsとFAISSインデックスを用いたRAG検索 search_data 関数では、S3 から取得した FAISS インデックスをローカルでロードし、クエリに合致する文書を検索します。 get_embeddings 関数によって生成される Embeddings クライアント(Azure OpenAI または OpenAI)を用いて文書をベクトル化しており、 faiss を活用した高速検索が可能です。 from typing import Any, Dict, List, Optional from langchain_community.vectorstores import FAISS from langchain_core.documents.base import Document from langchain_core.vectorstores.base import VectorStoreRetriever from shared.secrets import get_secret from shared.logger import getLogger from langchain_openai import AzureOpenAIEmbeddings, OpenAIEmbeddings logger = getLogger(__name__) def get_embeddings(secrets: Dict[str, str]): api_type: str = secrets.get("openai_api_type", "azure") if api_type == "azure": return AzureOpenAIEmbeddings( openai_api_key=secrets.get("azure_openai_api_key_eastus2"), azure_endpoint=secrets.get("azure_openai_endpoint_eastus2"), model="text-embedding-3-large", api_version=secrets.get("azure_openai_api_version_eastus2", "2023-07-01-preview"), ) elif api_type == "openai": return OpenAIEmbeddings( openai_api_key=secrets.get("openai_api_key"), model="text-embedding-3-large", ) else: logger.error("無効なAPIタイプが指定されています。") raise ValueError("Invalid api_type") def search_data( query: str, index_folder_path: str, search_type: str = "similarity", score_threshold: Optional[float] = None, k: Optional[int] = None, fetch_k: Optional[int] = None, lambda_mult: Optional[float] = None, ) -> List[Dict]: secrets: Dict[str, str] = get_secret() embeddings = get_embeddings(secrets) db: FAISS = FAISS.load_local( folder_path=index_folder_path, embeddings=embeddings, allow_dangerous_deserialization=True, ) search_kwargs = {"k": k} if search_type == "similarity_score_threshold" and score_threshold is not None: search_kwargs["score_threshold"] = score_threshold elif search_type == "mmr": search_kwargs["fetch_k"] = fetch_k or k * 4 if lambda_mult is not None: search_kwargs["lambda_mult"] = lambda_mult retriever: VectorStoreRetriever = db.as_retriever( search_type=search_type, search_kwargs=search_kwargs, ) results: List[Document] = retriever.invoke(input=query) return [{"content": doc.page_content, "metadata": doc.metadata} for doc in results] 非同期ダウンロードとLambdaハンドラ async_handler 内で setup_faiss を実行し、 download_files で S3 から FAISS インデックスファイルを取得します。その後 search_data で RAG 検索を実行し、結果を JSON で返します。 import asyncio import json import os from shared.s3_client import S3Client from shared.logger import getLogger from shared.token_verifier import with_token_verification logger = getLogger(__name__) RESULT_NUM = 5 @with_token_verification async def async_handler(event: Dict[str, Any], context: Any) -> Dict[str, Any]: env = os.getenv("ENV") s3_client = S3Client() s3_bucket = "bucket-name" setup_faiss(s3_client, s3_bucket) request_body_str = event.get("body", "{}") request_body = json.loads(request_body_str) query = request_body.get("query") index_path = request_body.get("index_path") local_index_dir = "/tmp/index_faiss" await download_files(s3_client, s3_bucket, index_path, local_index_dir) results = search_data( query, local_index_dir, search_type=request_body.get("search_type", "similarity"), score_threshold=request_body.get("score_threshold"), k=request_body.get("k", RESULT_NUM), fetch_k=request_body.get("fetch_k"), lambda_mult=request_body.get("lambda_mult"), ) return create_response(200, results) def retrieverHandler(event: Dict[str, Any], context: Any) -> Dict[str, Any]: return asyncio.run(async_handler(event, context)) def create_response(status_code: int, body: Any) -> Dict[str, Any]: return { "statusCode": status_code, "body": json.dumps(body, ensure_ascii=False), "headers": { "Content-Type": "application/json", }, } async def download_files(s3_client: S3Client, bucket: str, key: str, file_path: str) -> None: loop = asyncio.get_running_loop() await loop.run_in_executor(None, download_files_from_s3, s3_client, bucket, key, file_path) def download_files_from_s3(s3_client: S3Client, s3_bucket: str, prefix: str, local_dir: str) -> None: keys = s3_client.list_objects(bucket_name=s3_bucket, prefix=prefix) if not keys: logger.info(f"'{prefix}'内にファイルが存在しません。") return for key in keys: relative_path = os.path.relpath(key, prefix) local_file_path = os.path.join(local_dir, relative_path) os.makedirs(os.path.dirname(local_file_path), exist_ok=True) s3_client.download_file(bucket_name=s3_bucket, key=key, file_path=local_file_path) 5.4のまとめ setup_faiss による faiss 動的ロードで Lambda レイヤー容量問題を回避 非同期 I/O と S3 利用により、コンテナ化や EFS 接続なしで FAISS インデックスをロード search_data で Embedding 済みインデックスを検索し、RAG が迅速な類似文書提供を実現 これにより、RAG 検索を用いた高速なナレッジ検索が可能となり、LLM 回答に特化した情報提供が実現できます。 5.5 [Python] EmbeddingとFAISSインデックス化 このセクションでは、Confluence ドキュメントなどの社内ドキュメントを Embedding し、FAISS インデックスを作成・更新する定期バッチ処理の例を示します。 RAG パイプラインで参照するインデックスは、生成 AI が社内特有の知識を回答に反映するための重要な鍵です。そのため、定期的なドキュメント更新時には Embedding と FAISS インデックスを再構築し、最新情報を常に参照できるようにします。 処理の概要 S3 から JSON フォーマットのドキュメントを取得 取得したドキュメントを Embedding(OpenAI や Azure OpenAI の Embeddings API を利用) Embedding 済みのテキスト群を FAISS インデックス化 作成した FAISS インデックスを S3 へアップロード これらの手順を Lambda バッチ処理や Step Functions ワークフローで定期的に実行することで、問い合わせ時には常に最新インデックスを用いた RAG 検索が行えます。 ステップ1:JSONドキュメントの読み込み S3 上の JSON ファイル(Confluence ページ等を要約済みのもの)をダウンロード・パースし、 Document オブジェクトのリストに変換します。 import json from typing import Any, Dict, List from langchain_core.documents.base import Document from shared.logger import getLogger logger = getLogger(__name__) def load_json(file_path: str) -> List[Document]: """ JSONファイルを読み込み、Documentオブジェクトのリストを返します。 JSONは [{"title": "...", "content": "...", "id": "...", "url": "..."}] のような形式を想定。 """ with open(file_path, "r", encoding="utf-8") as f: data = json.load(f) if not isinstance(data, list): raise ValueError("JSONトップレベルがリストではありません。") documents = [] for record in data: if not isinstance(record, dict): logger.warning(f"スキップされたレコード(辞書でない): {record}") continue title = record.get("title", "") content = record.get("content", "") metadata = { "id": record.get("id"), "title": title, "url": record.get("url"), } # タイトルとコンテンツをまとめたテキストとしてDocument化 doc = Document(page_content=f"Title: {title}\nContent: {content}", metadata=metadata) documents.append(doc) logger.info(f"{len(documents)} 件のドキュメントをロードしました。") return documents ステップ2:EmbeddingとFAISSインデックス化 vectorize_and_save 関数では、 get_embeddings で取得した Embeddings クライアントでドキュメントを Embedding し、 FAISS インデックスを作成します。その後、ローカルにインデックスを保存します。 import os from langchain_community.vectorstores import FAISS from langchain_core.text_splitter import RecursiveCharacterTextSplitter from shared.logger import getLogger logger = getLogger(__name__) def vectorize_and_save(documents: List[Document], output_dir: str, embeddings) -> None: """ ドキュメントをEmbeddingし、FAISSインデックスを作成してローカルに保存します。 """ # テキスト分割器を使用してドキュメントを小さなチャンクに分割 text_splitter = RecursiveCharacterTextSplitter(chunk_size=1024, chunk_overlap=128) split_docs = text_splitter.split_documents(documents) logger.info(f"{len(split_docs)} 件の分割済みドキュメント") # Embeddingsでベクトル化し、FAISSインデックス構築 db: FAISS = FAISS.from_documents(split_docs, embeddings) logger.info("ベクトルDBの構築が完了しました。") os.makedirs(output_dir, exist_ok=True) db.save_local(output_dir) logger.info(f"ベクトルDBを {output_dir} に保存しました。") ステップ3:インデックスをS3へアップロード ローカルで作成した FAISS インデックスを S3 にアップロードすることで、RAG 検索用 Lambda から容易に取得可能になります。 from shared.s3_client import S3Client from shared.logger import getLogger logger = getLogger(__name__) def upload_faiss_to_s3(s3_client: S3Client, s3_bucket: str, local_index_dir: str, index_s3_path: str) -> None: """ FAISSインデックスをS3にアップロードします。 """ index_files = ["index.faiss", "index.pkl"] for file_name in index_files: local_file_path = os.path.join(local_index_dir, file_name) s3_index_key = os.path.join(index_s3_path, file_name) s3_client.upload_file(local_file_path, s3_bucket, s3_index_key) logger.info(f"FAISSインデックスファイルを s3://{s3_bucket}/{s3_index_key} にアップロードしました。") ステップ4:全体フローをLambdaで実行 index_to_s3 関数は全体フローをまとめています。S3 から JSON をダウンロード、Embedding と FAISS インデックス作成、そしてインデックスを S3 へアップロードします。この処理を Step Functions などのワークフローで定期的に実行し、常に最新のインデックスを用意します。 import os from shared.faiss import setup_faiss from shared.logger import getLogger from shared.s3_client import S3Client from shared.secrets import get_secret logger = getLogger(__name__) def index_to_s3(json_s3_key: str, index_s3_path: str) -> Dict[str, Any]: """ S3からJSONファイルをダウンロードし、EmbeddingとFAISSインデックス作成を行い、インデックスをS3に保存します。 """ env = os.getenv("ENV") if env is None: error_msg = "ENV 環境変数が設定されていません。" logger.error(error_msg) return {"status": "error", "message": error_msg} try: s3_client = S3Client() s3_bucket = "bucket-name" local_json_path = "/tmp/json_file.json" local_index_dir = "/tmp/index" # 必要なら faiss のセットアップ(S3からダウンロード) setup_faiss(s3_client, s3_bucket) # JSONファイルをS3からダウンロード s3_client.download_file(s3_bucket, json_s3_key, local_json_path) documents = load_json(local_json_path) # Embeddingsクライアント取得 secrets = get_secret() embeddings = get_embeddings(secrets) # ベクトル化とFAISSインデックス作成 vectorize_and_save(documents, local_index_dir, embeddings) # インデックスファイルをS3へアップロード upload_faiss_to_s3(s3_client, s3_bucket, local_index_dir, index_s3_path) return { "status": "success", "message": "FAISSインデックスを作成し、S3にアップロードしました。", "output": { "bucket": s3_bucket, "index_key": index_s3_path, }, } except Exception as e: logger.error(f"インデックス作成処理中にエラー発生: {e}") return {"status": "error", "message": str(e)} 5.5のまとめ load_json で JSON ファイルを読み込み、 vectorize_and_save で Embedding と FAISS インデックス作成 upload_faiss_to_s3 でローカルインデックスを S3 へアップロード index_to_s3 で全体フローをまとめ、定期バッチ処理で最新インデックスを作成・更新 これにより、社内ドキュメントを Embedding し、RAG 検索用の FAISS インデックスを作成・更新するバッチ処理を実現できます。 6. まとめ 本記事では、Slack 上で LLM を活用する社内チャットボットの開発背景や技術的実装ポイント、RAG パイプラインの導入手順、Confluence ドキュメントのサニタイズや Embedding/FAISS インデックスによる検索基盤の整備、さらには翻訳・要約などの機能拡張について紹介しました。 こうした仕組みにより、Slack 内で自然な操作で生成 AI を利用でき、社員は新たなツールやコマンドを学ぶことなく高度な情報活用が可能になります。 7. 今後の展望 私たちは社内向け生成AIツールをさらに進化させるため次の改善・拡張に積極的に取り組みます。 Azure 環境での構築強化 Azure Functions や Azure CosmosDB などの Azure サービスとの連携を本格化し RAG パイプラインのパフォーマンスや拡張性を抜本的に向上させます。 Azure Cosmos DBベクトル検索の導入 Azure Cosmos DB for NoSQL 上でベクトル検索機能を実用化しより高度な検索を提供します。 @ card AI Document Intelligenceの活用 AI Document Intelligence を積極的に取り込み RAG のナレッジ範囲を拡大させより多彩な情報活用を実現します。 @ card モデルの多様化・高度化 GPT-4o のみならず GPT-o1 や Google Gemini など最新で多様なモデルへの対応を推進し常に最先端のモデルを統合します。 Web UIの実装 Slack 依存の表現上の制約を解消するため Web UI を構築し多彩なインタラクションや新機能を柔軟に展開します。 プロンプト管理の拡充 既存のプロンプトをテンプレート化し用途別に容易な再利用を実現します。またプロンプト共有機能を充実させ社内全体での生成 AI 活用を一層促進します。 マルチエージェント化の実現 要約や翻訳、 RAG 検索など特定機能に特化した専門エージェントを配置し、エージェントビルダー機能で自由に組み合わせることでより柔軟で高度な情報活用を可能にします。 RAG精度の評価・改善 テストセットを構築し回答の自動評価を実施して精度を定量的に把握し継続的な品質向上につなげます。 ユーザーフィードバックを起点とした改善 利用実態やフィードバックを反映し対話フローの最適化やプロンプトチューニング外部サービス連携強化など実運用を通じて常に社内向け生成AIツールの利便性と有用性を高めていきます。 私たちはこれらの取り組みによって社内向け生成AIツールを持続的に進化させ、より多様なニーズに応えられる力強い社内支援ツールへ成長させます。
こんにちは、人事グループ組織人事チームのHOKAです。 本日は、 2024年3月に10X innovation culture programを受けた その後のお話をいたします。 はじめに KINTOテクノロジーズ(以下、KTC)では、イノベーションを生み出す組織環境づくりに挑戦しています。現在はまだその「過程」であり、試行錯誤をしていますが、これから 10X innovation culture program を導入しようと考えている方や、何かイノベーションを起こす組織を創りたいと考えている方に読んでもらえたら幸いです。 7月:自分たちで10X innovation culture programやってみた 3月にGoogleオフィスで10X innovation culture programを受ける前から、決意していたことがあります。 それは、10X innovation culture programを自社で実施していくということ。 「3か月ごとに実施しよう。アセスメント結果を見よう。」 「2回目からは自分たちで10X を実施しよう。」と誓った2024年3月の私たち。 夏の開催に向け、再びあわっちとHOKAは動き始めました。 まず最初に行ったのが、ファシリテーターを決めること。 今回はGoogleの方はいないので、自分たちで担当しなくてはなりません。 Slackで声をかけたところ、4人のメンバーがファシリテーターに立候補してくれました。 10X innovation culture programは、大きく分けて下記3つのコンテンツを実施します。そして、参加者が自分だったらどうするか?KTCだったらどれが良いかを考え、実行していきます。 【1】10Xの動画を視聴し、10Xとは何かを理解する「事前MTG」 【2】アセスメント結果から「現在地」を知る 【3】10Xの要素をテーマにディスカッションする これらを実施するだけです。 それなのに、すごく難しかった!!のです。 難しかったポイント 【時間配分】当日のプログラムは2時間必要なのか、3時間必要なのかさえ分からない 【コンテンツ】初めて参加する人と2回目に参加する人、2パターンいるがどうやって進めたら良いのか 【品質】「10Xとは」を語るシーンが重要なのだが、いざKTCメンバーが話すと、ただ読み上げているだけになってしまう 等々、基本の「き」から手探り状態でした。あわっちとファシリテーターの4人と一緒に、3月の研修をふまえて「たぶん、こうだよね」と話し合いながら何とか実施したというのが本音です。 コンテンツごとに振り返り 【1】動画を視聴し10Xとは何かを理解する「事前MTG」 前回と同様にzoomで実施。ファシリテーターが「10Xとは」を説明し、その後の10Xの動画を再生。最後にアセスメント回答をしました。 なぜか3月ほど盛り上がっていない。 もしかしたら、「なぜ10XをKTCが学ぶのか」が足りないのかも? と運営側では感じていました。 【2】アセスメントの結果から現在地を知る そして、2024年7月2日、10X innovation culture programを室町オフィスで開催しました。 Osaka Tech Lab.(大阪オフィス)や、名古屋からも参加し、総勢39名。初めて参加した人も、2回目に参加する人もいました。 事前にみんなが回答したアセスメントの結果を見て、前回よりも上がった/下がったを報告したが、なんだか反応が薄い。 前回(3月)から今回(7月)まで何かに取り組んだ訳ではないから、数値に思い入れが持てないのかも? アセスメント結果を共有されているだけでは、まだ良い・悪いは判断できないのかも? と運営側では仮説を立てました。 【3】10Xの要素をテーマにディスカッションする 続いて、「この3か月間の振り返り」をディスカッションしました。 全く覚えていない人がいたり、初めて参加した人は「動画を見ただけだから、何をしたら良いか分からない」という人も。前回、Googleオフィスで行った時には、スムーズにディスカッションが進んでいただけに、運営側としては想定外の事態でした。(今、思えば当たり前なんですけど) その後、10Xの要素の1つ「自主性」についてディスカッションを実施。前回と同様にグループに分かれて課題から書き出し、解決策をディスカッションしていただきました。 3か月間、特に10Xを意識した行動してない人がいる なぜか前回よりもディスカッションしづらい雰囲気がある という発見がありました。 実施後アンケート 前回 に比べ、3や2の数が増え、1が付いた項目もありました。 推進のモチベーションも下がっています。 また、アンケートコメントにおいても、参加者の方から以下のアドバイスをいただきました。 全体の感想 運営お疲れ様でした!楽しい会になりました。 今のところ特になし ぜひ他の組織でも行ってほしいです。他の人の考えが知れるだけでもとてもいい活動 前回の内容に関するフィードバック 前回の内容を簡単に説明して欲しかった。前回参加できていないかたが置いてきぼりの時間があった。 前回の課題の記憶取り戻しに時間を要したので、事前に振り返りの時間を作れたらと思った。 前回のほうがディスカッションが盛り上がった気がした、場を積極的に回す人がいなかったし(自発性の欠如)事前準備をきちんとしておらず、入り込むまでに時間がかかった。 時間・スケジュールに関するフィードバック 時間的には短かったよね。もっとグループワークしてディスカッションする時間があったほうがよかったかも。 タイムスケジュールがタイトすぎる(大体その通りいかないので余裕持たないと。分単位は危険すぎる) 確保時間の問題かな?(目的はこれだったと思うので、流れ的にネクストアクションとまではいっていなかった気がする) グループディスカッションに関するフィードバック グループディスカッションのメンバー選定について、チームを横断したメンバーではなく、実際の業務で組んでいるチームメンバーでやっても良いかなと 前回、今回のように他チームのメンバーと協議することは刺激的であり、新鮮です。ですが業務に即した結果が出にくいということも感じています。そこで同じチームメンバー同士で改めて10Xについて会話することも良いかなと思いました。 ワークショップの進行・運営に関するフィードバック アイスブレイク(自己紹介)などの時間が少なすぎ。ワークショップを始めるにあたって、知らない人同士の環境を緩めるには非常に重要。自己紹介も終わらなかった。 ワークショップの質問が抽象的で回答の出し合いに困っていた おそらく、このワークショップのゴール設定がなされていなかった可能性がある(運営側が) 参加する方も今回これを持ち帰ってねという握りをはじめにしておいた方がいいとおもう 内容の理解・フォローアップに関するフィードバック 初参加でしたが内容としては既習者向けの感があり、全体としてぼんやりとした内容という印象を受けました。 内容を絞ってコンパクトにするか、尺を拡大してしっかりした説明を加えたほうが良いのではと感じました。 その他 配布された紙(回答コメント)がなんのためか分からない デスク毎にリーダーを決めてもらうことをはじめにした方がよさそう 自発性とチーム内の話し合い また前回を振り返った時にアクションが少なかったので、定期的にチームでも話し合いの時間をもうけたい 内発的動機に興味あります。自立性と組み合わせれるとより一層のスピード感を持てると思います。 さらに、10X innovation culture program実施後にファシリテーターメンバーで集まって、振り返りを実施。アイデアがたくさん集まりました。 さて、どこから手をつけるべきか? そんな中、Googleの方から Google Cloud Next Tokyo'24 で登壇する機会をいただきました。 <<中編へ続く>>
この記事は KINTOテクノロジーズアドベントカレンダー2024 の22日目の記事です🎅🎄 はじめまして! KINTOテクノロジーズでUnlimited(Android)アプリを開発しているkikumidoと申します。 弊アプリでは、 GraphQL クライアントとして Apollo Kotlin を使用しています。 Apollo Kotlin v4では、パフォーマンスの向上や新機能の追加など、多くの改善が行われています。 これらの利点を活かすため、私たちはv3からv4へのアップグレードを決定しました。 本記事では、今年の7月にリリースされたApollo Kotlin v4への移行作業の流れと、その過程で遭遇した課題について詳しく説明します。 当初はスムーズな移行を期待していましたが、予想外の例外に直面し、解決策を見出すのに苦労する場面もありました。 この記事が、これからバージョンアップを検討している方々にとって、有益な情報源となれば幸いです。 v3からv4への移行 公式サイト に従い対応していきます。 尚、 Android Studioにプラグインをインストールすることで、半自動でバージョンアップすることも出来ます。 必要な対応を確認しながら移行作業を実施したかったので、私はプラグインを使わずに愚直に手動で対応しました。 一方、プラグインでどこまで自動でできるのかにも興味があったので、手動の場合との作業方法の比較を後半に記載します。 1.対応必須箇所 v3からv4への移行で、弊アプリでAndroid Studio上でエラーを無くす為に必須だった対応は5つあります。 以下に対応内容をひとつずつ記載していきます。 :::message alert アプリの実装状況により対応内容が異なる可能性は大いにあります あくまでも弊アプリの対応内容であることはご留意ください ::: 1.1.ライブラリのバージョンアップ 何はともあれ、まずは ライブラリ のバージョンアップをします。 apollographql = "3.8.5" apollo-runtime = { module = "com.apollographql.apollo3:apollo-runtime", version.ref = "apollographql" } apollographql-apollo = { id = "com.apollographql.apollo3", version.ref = "apollographql" } ↓ // 記事執筆時はv4.1.0がリリースされていますが、移行当時の最新である4.0.1で記載しています apollographql = "4.0.1" apollo-runtime = { module = "com.apollographql.apollo:apollo-runtime", version.ref = "apollographql" } apollographql-apollo = { id = "com.apollographql.apollo", version.ref = "apollographql" } ふむふむ。 com.apollographql.apollo3 が com.apollographql.apollo4 になったのではなく、「3」が消えましたね。 1.2.gradleファイルの修正 v3の時は不要でしたが、v4ではserviceで囲う必要があります。 apollo { packageName.set("com.example.xxx.xxx.xxx") ・・・ } ↓ apollo { service("service") { packageName.set("com.example.xxx.xxx.xxx") ・・・ } } 1.3.importの変更 先述の「3」が消えた時に予想できましたが、importのパッケージ名を変更する必要があります。 「3」を消すだけです。 import com.apollographql.apollo3.* ↓ import com.apollographql.apollo.* 1.4.例外処理を修正 execute() でフェッチエラーがスローされないように変更になりましたので対応します。 プロジェクトごとに対応方針が異なると思いますが、私たちは一旦既存処理への影響を最小限に抑える対応を実施することにしました。 v3の時にフェッチエラーが発生し ApolloException をスローしていたのと同じ条件の時に、 DefaultApolloException をスローするように修正する方法です。 共通処理を修正することにより、共通処理を呼び出している側では実装を修正することなく、既存と同じ挙動にできました。 apolloClient.query(query).execute() apolloClient.mutation(mutation).execute() ↓ execute(apolloClient.query(query)) execute(apolloClient.mutation(mutation)) private suspend inline fun <D : Operation.Data> execute(apolloCall: ApolloCall<D>): ApolloResponse<D> { val response = apolloCall.execute() if (response.data == null) { response.exception?.let { // response.dataがnullかつresponse.exceptionがnullでない場合はフェッチエラー throw DefaultApolloException(it.message, it.cause) } } return response } 既存実装やv4対応の方針により一気に移行することが難しい場合は、v3の挙動を変えずに移行する為のヘルパーとして executeV3() が準備されていますので、そちらに一旦置き換えることも可能です。 apolloClient.query(query).executeV3() apolloClient.mutation(mutation).executeV3() 機能毎など、徐々にv4への移行を進めたい場合はこちらを使うとよさそうです。 :::message alert executeV3() は非推奨メソッドなのでいずれは対応が必要になるはずですのでご注意ください ::: 1.5.ApolloExceptionをDefaultApolloExceptionに修正 ApolloException が sealed class になったため、インスタンスを生成していた箇所を DefaultApolloException に置き換えます。 Android Studio上でエラーを無くすために必要な対応は以上となります。 2.ビルド エラーも無くなったので・・・・ それでは、待ちに待ったビルドを実行してみましょう! ダララララララララララララララララララララララララララララララララ(ドラムロール)・・・ジャン! はい!出ました! ビルドエラー・・・! ・・・まあ、そんなにすんなり行くとは思っていませんでしたが・・・地味にショック・・・ さて、気を取り直してエラーログを確認していきます。 2.1.エラーログを確認 見慣れないエラーログが大量に吐かれていました。 要するに「KSP[^1]でAssistedInjectProcessingStep[^2]の時に必要なClassがないよ」ということらしい。 [^1]:弊アプリでは、 KSP を使用しています [^2]:弊アプリでは、依存関係インジェクションライブラリとして Hilt を使用しています If type 'error.NonExistentClass' is a generated type, check above for compilation errors that may have prevented the type from being generated. Otherwise, ensure that type 'error.NonExistentClass' is on your classpath. e: [ksp] AssistedInjectProcessingStep was unable to process 'XXXXXViewModel(java.lang.String,long,com.xx.xx.XXXXXRepository)' because 'error.NonExistentClass' could not be resolved. もちろんソース上は存在するクラスですし、本対応前は問題なくビルドが成功していました。 v4移行で必要な対応が漏れていないか?など色々調べましたがなかなかわからず・・・ 色々調査した結果、下記3種類の方法でビルドを成功させることができました。 A. Hilt を KSP から kapt に戻す B. build.gradle.ktsに追記する:パターン1 androidComponents { onVariants(selector().all()) { variant -> afterEvaluate { val variantName = variant.name.replaceFirstChar { if (it.isLowerCase()) it.titlecase(Locale.getDefault()) else it.toString() } val generateTask = project.tasks.findByName("generateServiceApolloSources") val kspTask = project.tasks.findByName("ksp${variantName}Kotlin") as? org.jetbrains.kotlin.gradle.tasks.AbstractKotlinCompileTool<*> kspTask?.run { generateTask?.let { setSource(it.outputs) } } } } } C. build.gradle.ktsに追記する:パターン2 apollo { service("service") { packageName.set("com.example.xxx.xxx.xxx") // 追記start outputDirConnection { connectToAndroidSourceSet("main") } // 追記end ・・・ } } ちなみに Hilt の AssistedInject を使用している(定義方法によっては問題ない場合もあるようです) Hilt に KSP を使用している 先述の「1.2.gradleファイルの修正」で service で囲う 上記の条件が揃っていればv3でも再現しますので厳密には「v4対応」とは言えませんが、同時に対応したので記載しておきます。 弊アプリでは最初「B」で対応していましたが、ApolloExtensionの service の不具合[^3]で「C」で対応できることがわかった為、「C」を採用しました。 [^3]: Issues → 記事執筆時最新のv4.1.0でも再現しました 以上でビルドが成功し、アプリが起動・既存と同じ挙動をするようv4へ移行することが出来ました! 3.非推奨箇所の対応 続いて、非推奨でワーニングとなった以下の2つに対応します。 3.1.ApolloResponse.Builderを修正 @Deprecated("Use 2 params constructor instead", ReplaceWith("Builder(operation = operation, requestUuid = requestUuid).data(data = data)")) とのことなので、その通りに修正します。 ApolloResponse.Builder(operation(), UUID_CONST, data).build() ↓ ApolloResponse.Builder<D>(operation(), UUID_CONST).data(data).build() data が外に出ましたね。 Builderパターンに則った形式に変更されたようです。 3.2.Errorインスタンス生成処理をBuilderに修正 Errorインスタンス生成でコンストラクタを使用していた箇所を、Builderを使用するように修正します。 Error("occurred Error", null, null, mapOf("errorCode" to responseCode), null) ↓ Error.Builder(message = "occurred Error") .putExtension("errorCode", responseCode) .build() 以上でワーニングを消すことも出来ました。 4.プラグインでの移行 Android StudioでApolloのプラグインを使用することによりある程度自動で移行してくれます。 実行方法はとても簡単で、 Android StudioでApolloのプラグインをインストールし Tools > Apollo > Migrate to Apollo Kotlin 4... をタップするだけです。簡単ですね。  では実行結果を確認します。 先述の 1.1.ライブラリのバージョンアップ 1.2.gradleファイルの修正 1.3.importの変更 は自動で移行してくれました。 1.4.例外処理を修正 は executeV3() に置き換えることしか行われないので、v4として適切な対応は手動で行う必要があります。 1.5.ApolloExceptionをDefaultApolloExceptionに修正 は移行してくれませんでしたので、対応は手動で行う必要があります。 文字通り、機械的にできる箇所は自動で移行してくれるので、 プラグインを使用して移行した上で、必要な箇所のみ手動で対応する方法もありだと思います。 ちなみに このプラグインは未使用フィールドをグレー表示してくれたり、移行時以外も活躍してくれるので、インストールしておくと良いと思います。 5.まとめ Apollo Kotlinをv3からv4へ移行した時の話は以上になります。 実際に対応した時から時間が経過してしまったので「すでに対応済み」という方も多くいらっしゃると思いますが、何かしらお役に立つものがあると嬉しいです。 最後までお読みいただきありがとうございました。 6. 関連リンク https://www.apollographql.com/docs/kotlin/migration/4.0 https://www.apollographql.com/docs/kotlin/testing/android-studio-plugin https://developer.android.com/build/migrate-to-ksp?hl=ja